> ## Documentation Index
> Fetch the complete documentation index at: https://docs.open-metadata.org/llms.txt
> Use this file to discover all available pages before exploring further.

# Unity Catalog Connector | OpenMetadata Data Governance

> Learn how to connect Unity Catalog to OpenMetadata with our comprehensive connector guide. Setup instructions, configuration tips, and metadata integrat...

export const ConnectorDetailsHeader = ({name, icon, stage, availableFeatures, unavailableFeatures = [], availableFeaturesCollate = []}) => {
  const showSubHeading = availableFeatures?.length > 0 || unavailableFeatures?.length > 0 || availableFeaturesCollate?.length > 0;
  const totalAvailableFeatures = [...availableFeatures || [], ...availableFeaturesCollate || []];
  return <div className="container">
      <div className="Heading">
        <div className="flex items-center gap-3">
          {icon && <div className="IconContainer">
              <img src={icon} alt={name} noZoom className="ConnectorIcon" />
            </div>}
          <h1 className="ConnectorName">{name}</h1>
          <span className={`StageBadge ${stage === 'PROD' ? 'prod' : 'beta'}`}>
            {stage}
          </span>
        </div>
      </div>
      {showSubHeading && <div className="SubHeading">
          <div className="FeaturesHeading">Feature List</div>
          <div className="FeaturesList">
            {totalAvailableFeatures.map(feature => <div className="FeatureTag AvailableFeature" key={feature}>
                ✓ {feature}
              </div>)}
            {unavailableFeatures.map(feature => <div className="FeatureTag UnavailableFeature" key={feature}>
                ✕ {feature}
              </div>)}
          </div>
        </div>}
    </div>;
};

<ConnectorDetailsHeader icon="/public/images/connectors/databrick.webp" name="Unity Catalog" stage="PROD" availableFeatures={["Metadata", "Query Usage", "Data Profiler", "Data Quality", "Lineage", "Column-level Lineage", "dbt", "Sample Data", "Owners", "Tags", "Auto-Classification"]} unavailableFeatures={["Stored Procedures"]} />

In this section, we provide guides and references to use the Unity Catalog connector.

<Info>
  **Supported Authentication Types:**

  * **Personal Access Token** — Generated token from your Databricks workspace (**User Settings** > **Developer** > **Access Tokens**).
  * **Databricks OAuth** — OAuth2 Machine-to-Machine authentication using Service Principal credentials.
  * **Azure AD Setup** — Azure Active Directory authentication using Service Principal for Azure Databricks workspaces.
</Info>

Configure and schedule Unity Catalog metadata workflow from the OpenMetadata UI:

* [Requirements](#requirements)
* [Metadata Ingestion](#metadata-ingestion)
  * [Incremental Extraction](/v2.0.x/connectors/ingestion/workflows/metadata/incremental-extraction/unity-catalog)
* [Data Quality](/v2.0.x/how-to-guides/data-quality-observability/quality)
* [Lineage](/v2.0.x/connectors/ingestion/lineage)
* [dbt Integration](/v2.0.x/connectors/database/dbt)
* [Troubleshooting](/v2.0.x/connectors/database/unity-catalog/troubleshooting)

## How to Run the Connector Externally

To run the Ingestion via the UI you'll need to use the OpenMetadata Ingestion Container, which comes shipped with
custom Airflow plugins to handle the workflow deployment.

If, instead, you want to manage your workflows externally on your preferred orchestrator, you can check
the following docs to run the Ingestion Framework **anywhere**.

<Columns cols={2}>
  <Card title="External Schedulers" href="/v2.0.x/deployment/ingestion">
    Get more information about running the Ingestion Framework Externally
  </Card>
</Columns>

## Requirements

Before configuring the Unity Catalog connector, make sure the following requirements are in place.

### Permission Requirement

To enable full functionality of metadata extraction, profiling, usage, and lineage features in OpenMetadata, the following permissions must be granted to the relevant users in your Databricks environment.

### Metadata and Profiling Permissions

These permissions are required on the catalogs, schemas, and tables from which metadata and profiling information will be ingested.

```sql theme={null}
GRANT USE CATALOG ON CATALOG <catalog_name> TO `<user>`;
GRANT USE SCHEMA ON SCHEMA <schema_name> TO `<user>`;
GRANT SELECT ON TABLE <table_name> TO `<user>`;
```

Ensure these grants are applied to all relevant tables for metadata ingestion and profiling operations.

### Usage

These permissions enable OpenMetadata to extract query history for usage statistics.

```sql theme={null}
GRANT SELECT ON SYSTEM.QUERY.HISTORY TO `<user>`;
GRANT USE SCHEMA ON SCHEMA system.query TO `<user>`;
```

### Lineage

These permissions enable OpenMetadata to extract table and column-level lineage from Databricks system tables.

```sql theme={null}
GRANT SELECT ON system.access.table_lineage TO `<user>`;
GRANT SELECT ON system.access.column_lineage TO `<user>`;
GRANT USE SCHEMA ON SCHEMA system.access TO `<user>`;
```

For external table lineage (linking tables to their storage locations), the following is also required:

```sql theme={null}
GRANT SELECT ON system.information_schema.tables TO `<user>`;
```

### Tags

These permissions enable OpenMetadata to extract Unity Catalog tags from catalogs, schemas, tables, and columns.

```sql theme={null}
GRANT SELECT ON <catalog_name>.information_schema.catalog_tags TO `<user>`;
GRANT SELECT ON <catalog_name>.information_schema.schema_tags TO `<user>`;
GRANT SELECT ON <catalog_name>.information_schema.table_tags TO `<user>`;
GRANT SELECT ON <catalog_name>.information_schema.column_tags TO `<user>`;
```

<Tip>
  Adjust \<user>, \<catalog\_name>, \<schema\_name>, and \<table\_name> according to your specific deployment and security requirements.
</Tip>

## Metadata Ingestion

To ingest metadata from Unity Catalog, you need to create a service connection. The service connects Unity Catalog with OpenMetadata. Once you create a service, OpenMetadata automatically starts ingesting metadata.

### Step 1: Add New Service

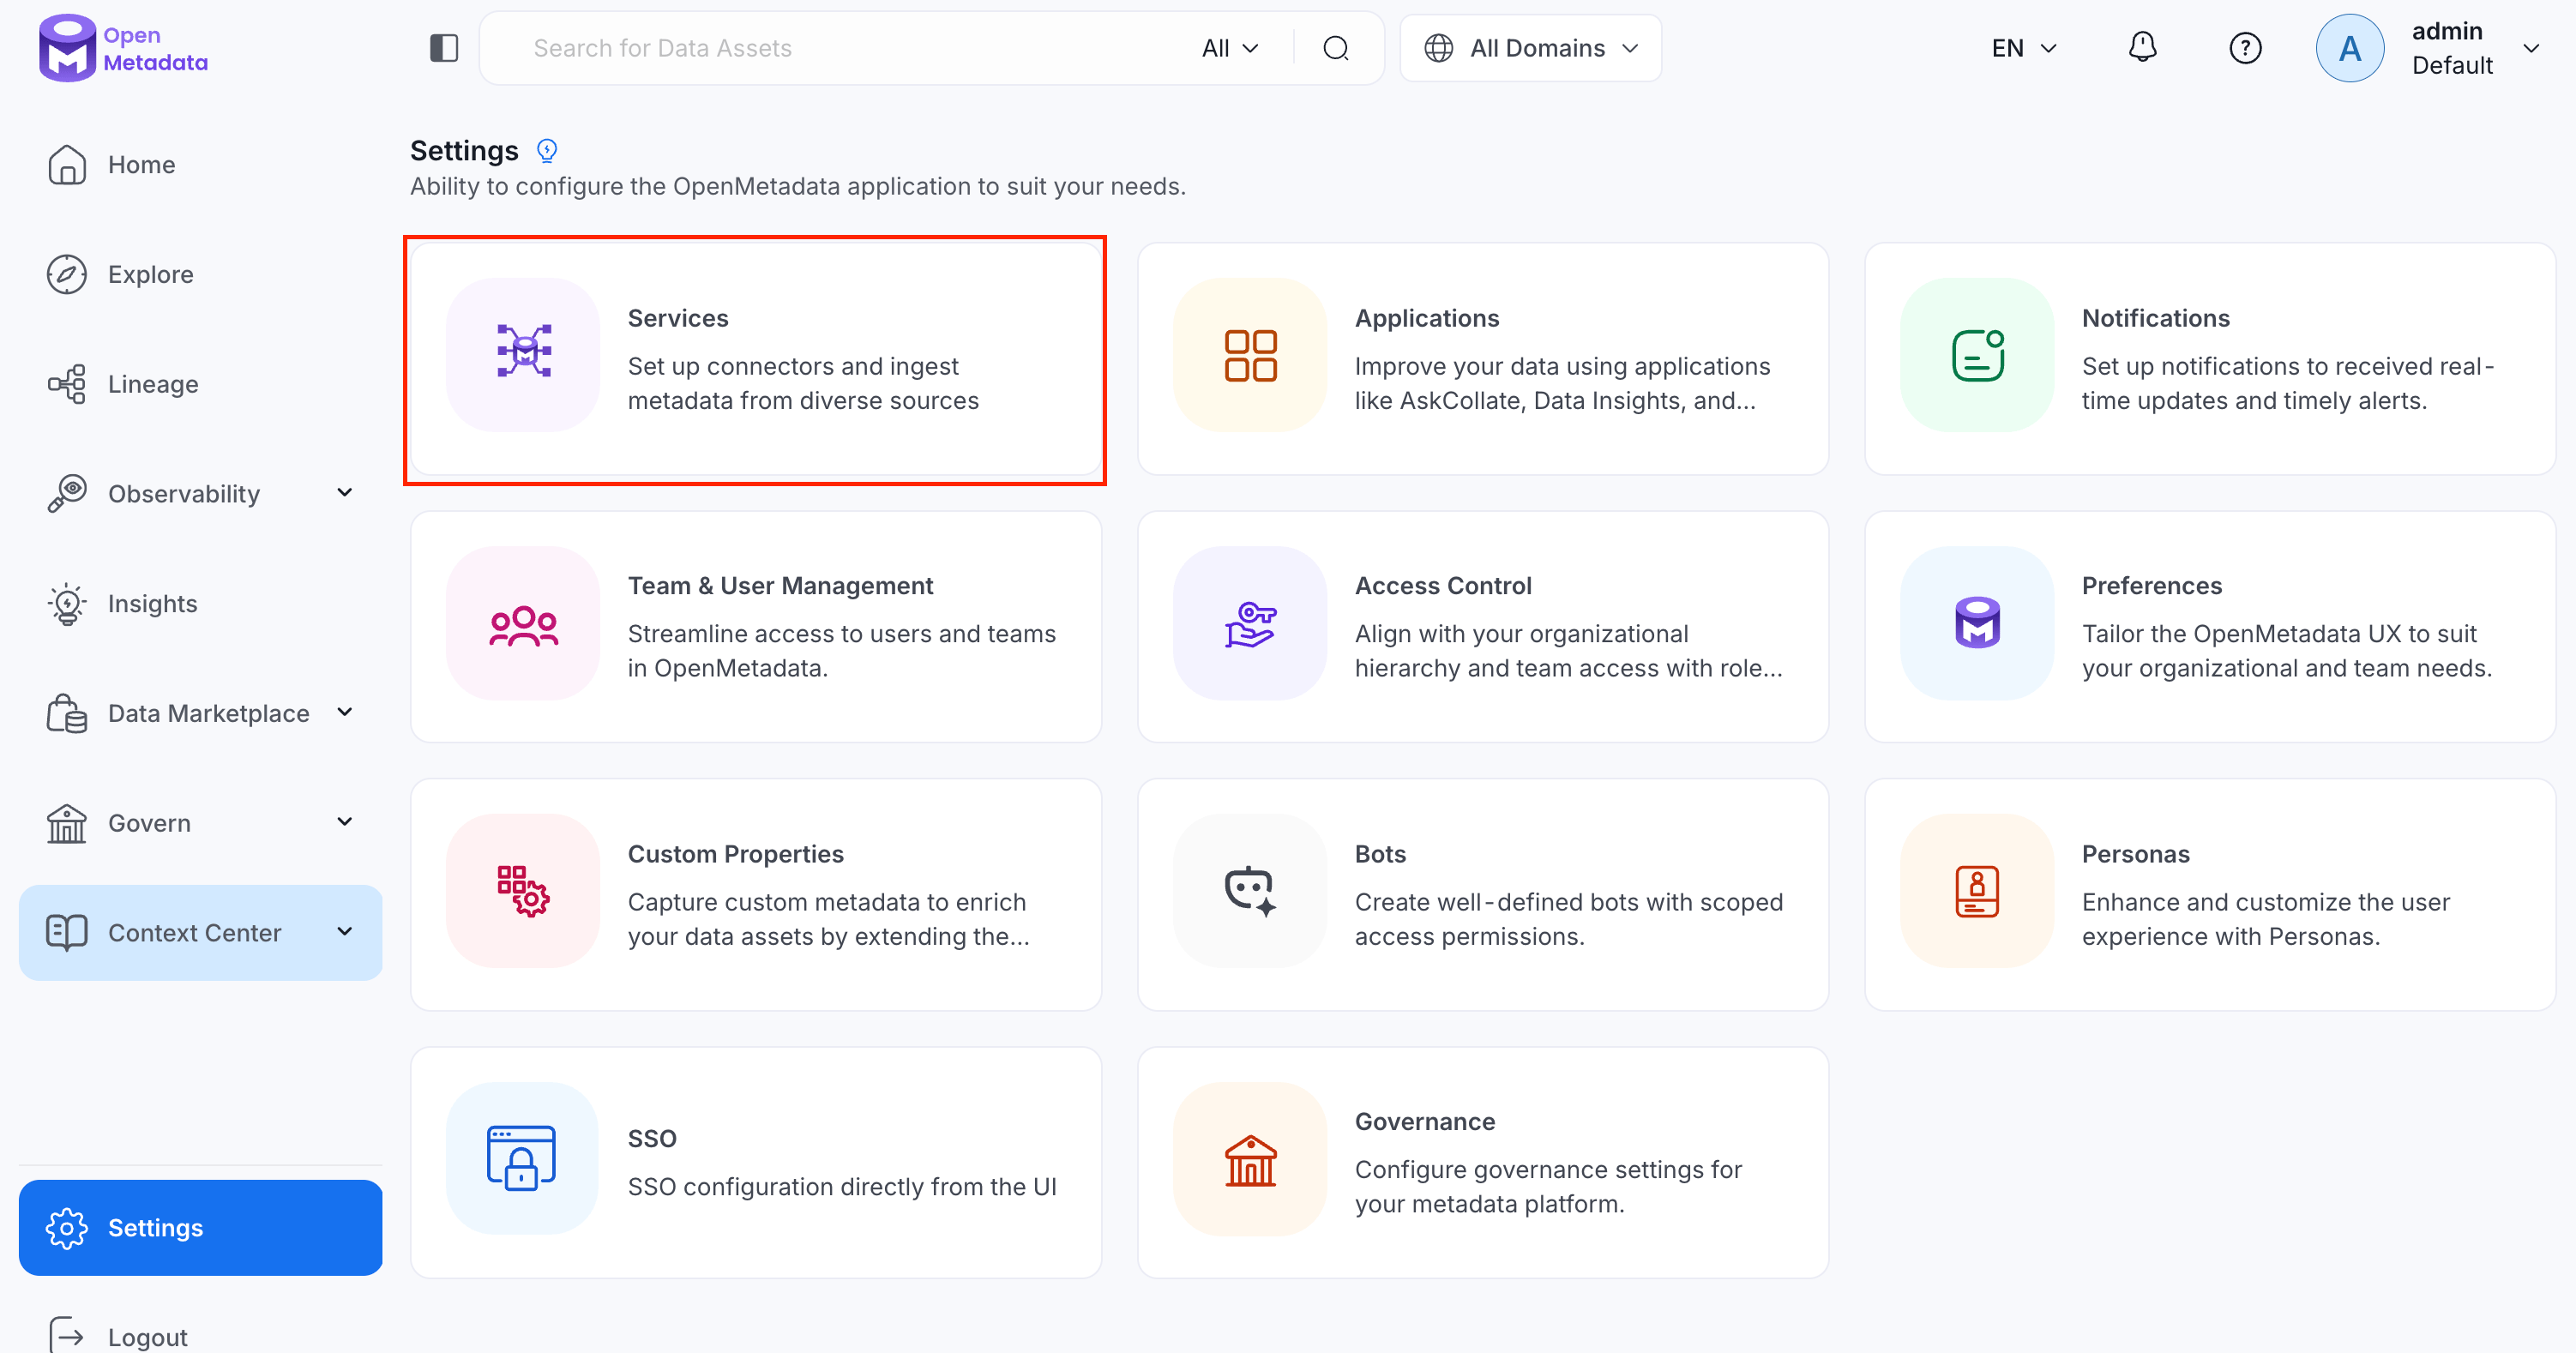
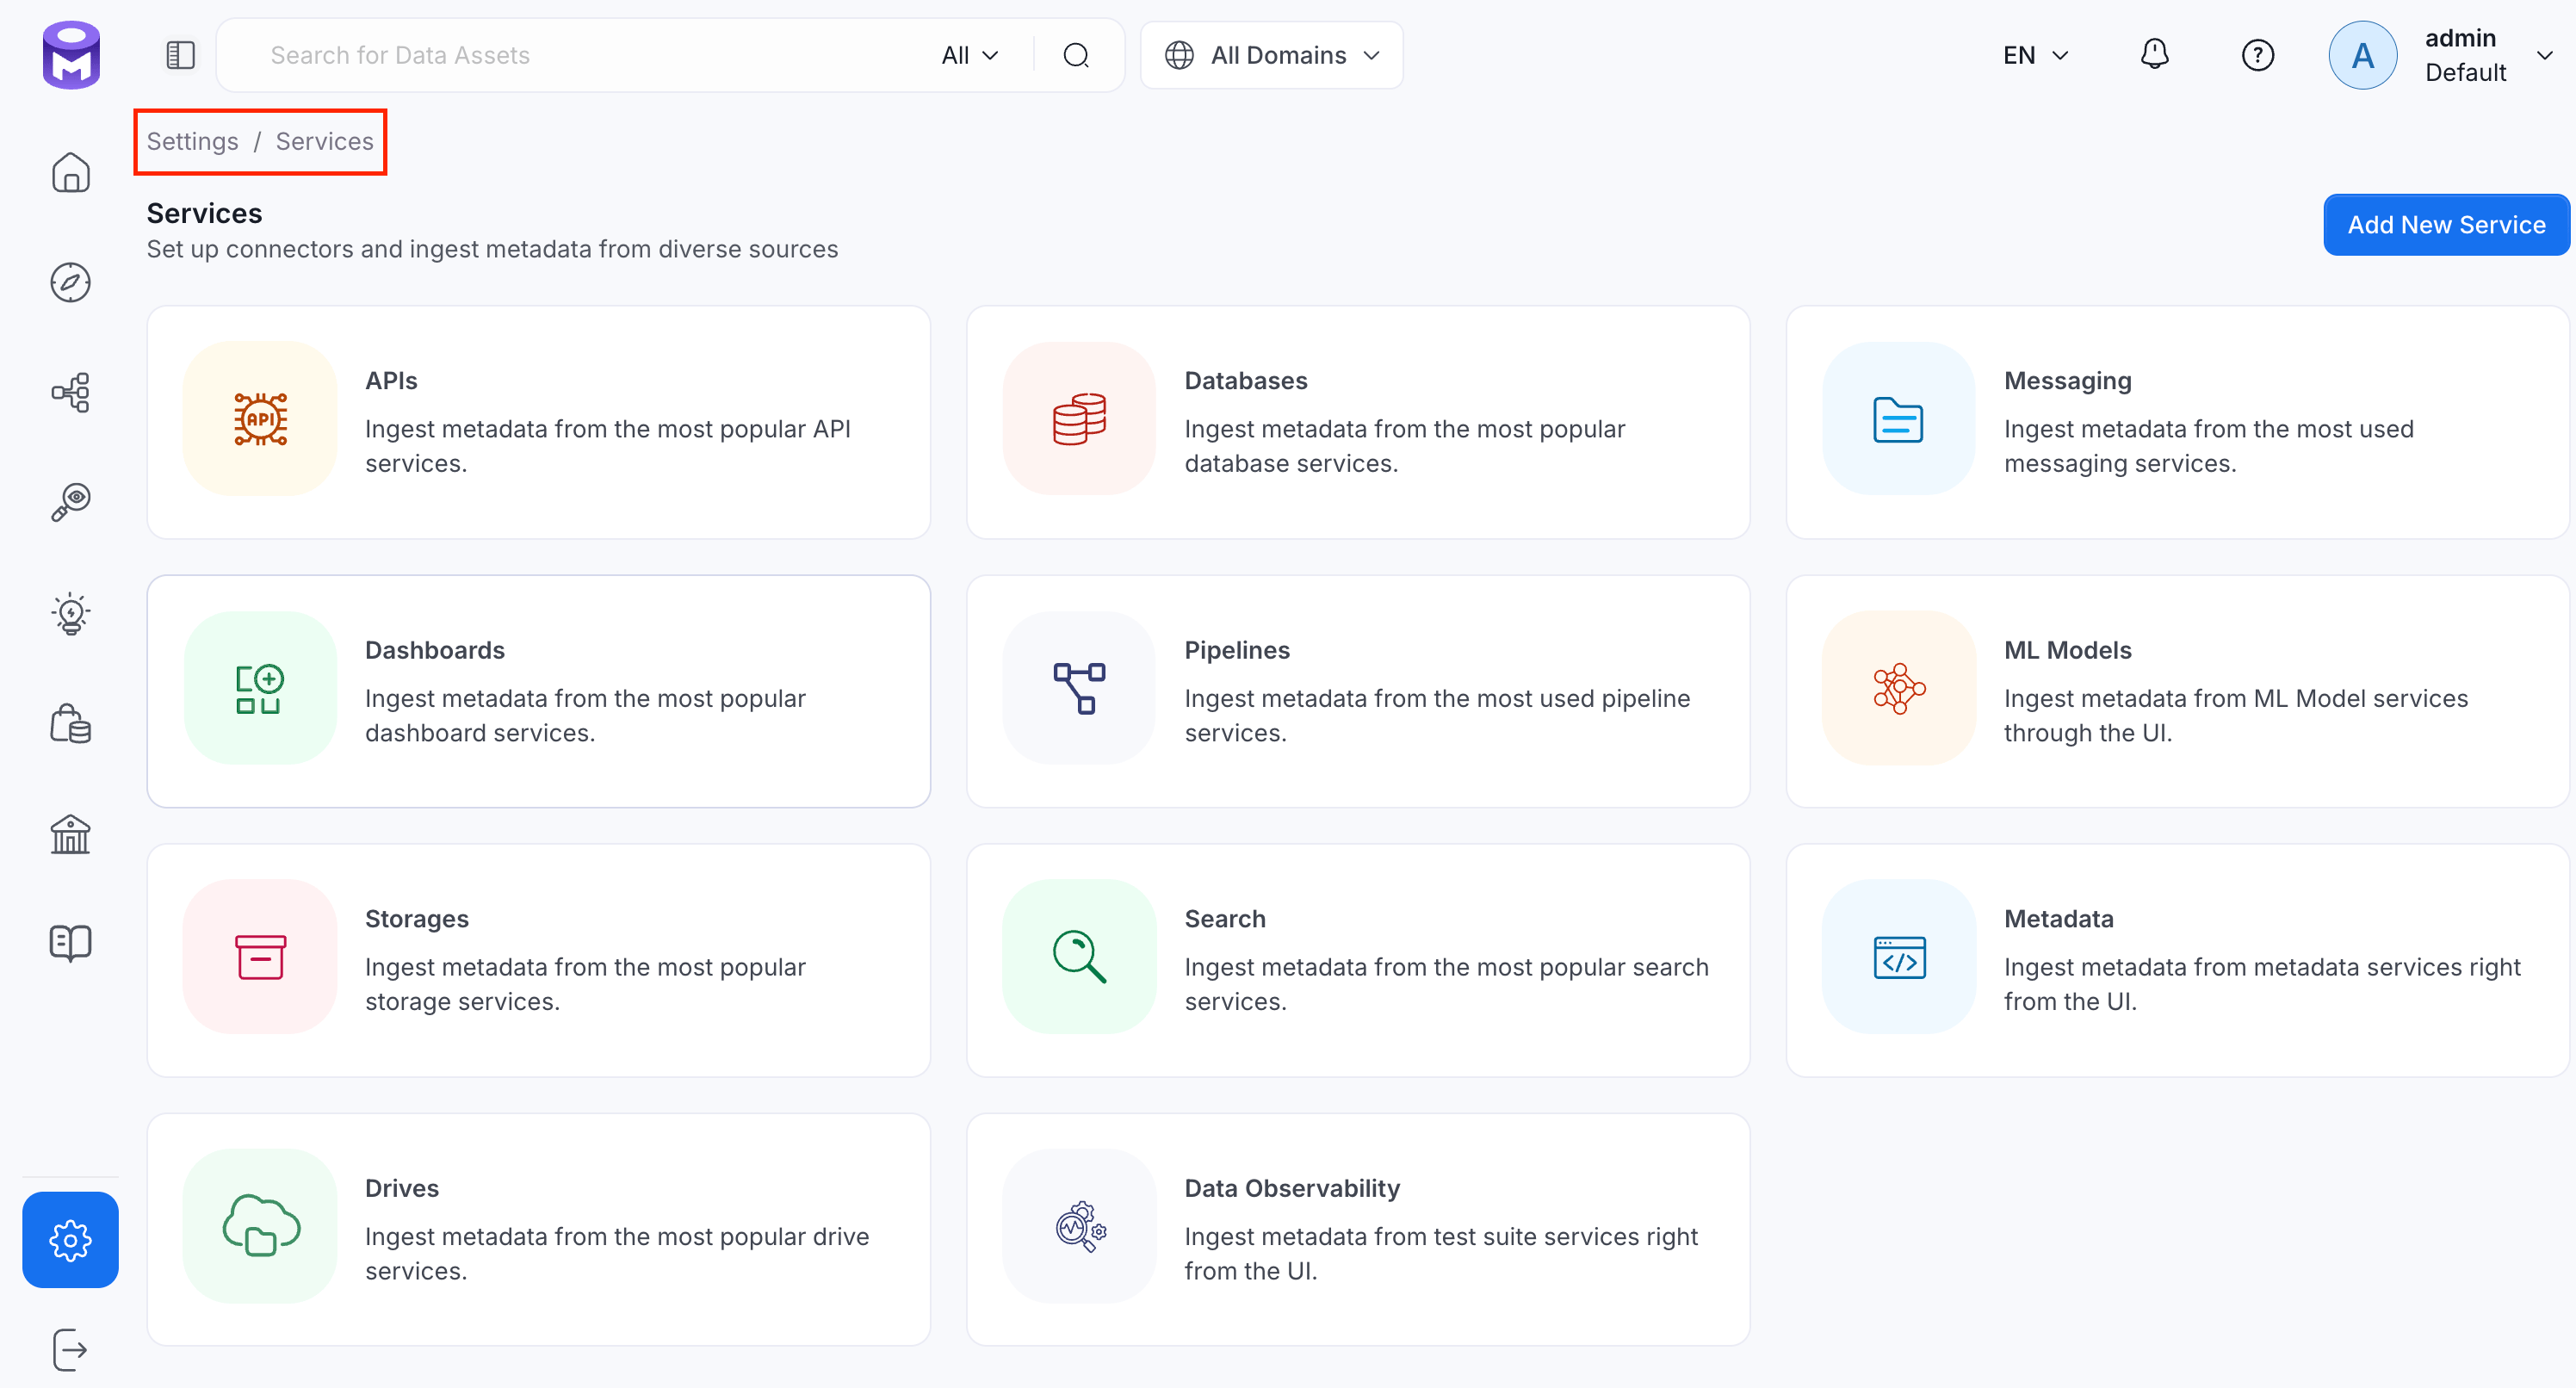
1. Navigate to **Settings** > **Services**.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/access-services.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=c95e6e79c73eea68039c10115c7f80d6" alt="Navigate to Settings and Services" width="3004" height="1578" data-path="public/images/connector2.0/metadata-ingestion/access-services.png" />

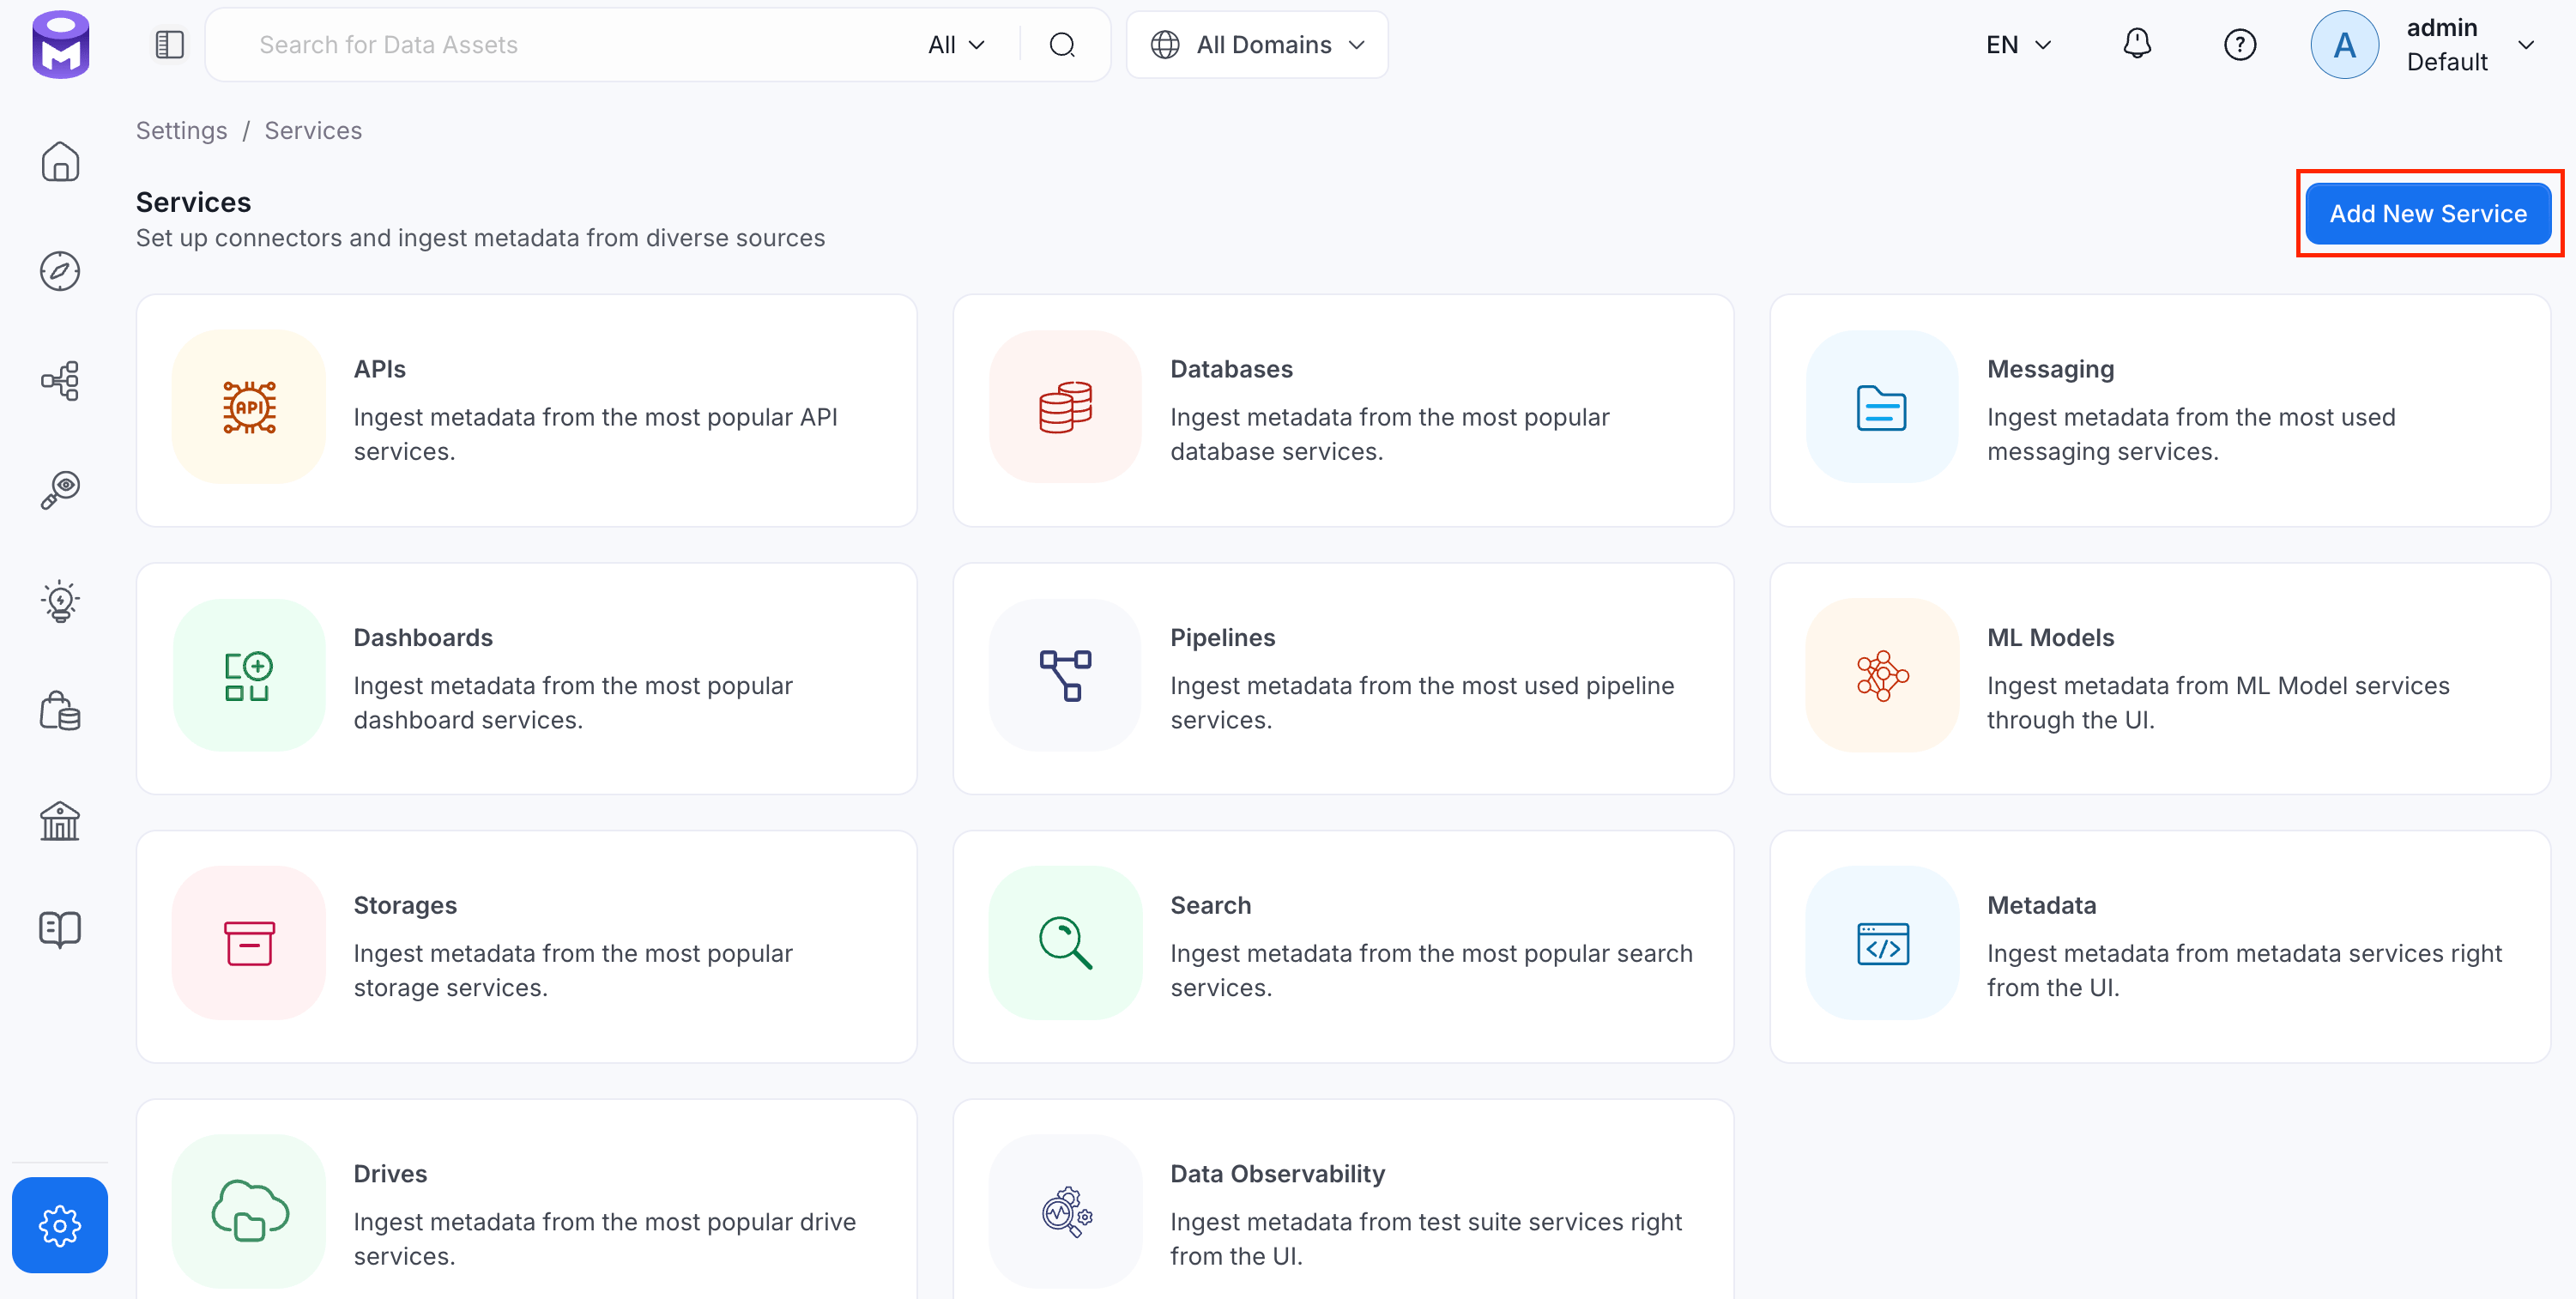
2. Click **Add New Service**.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/add-new-service.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=13457ef6e565aa39d339db30ce1f354d" alt="Add New Service" width="3002" height="1514" data-path="public/images/connector2.0/metadata-ingestion/add-new-service.png" />

### Step 2: Select a Service and Connector

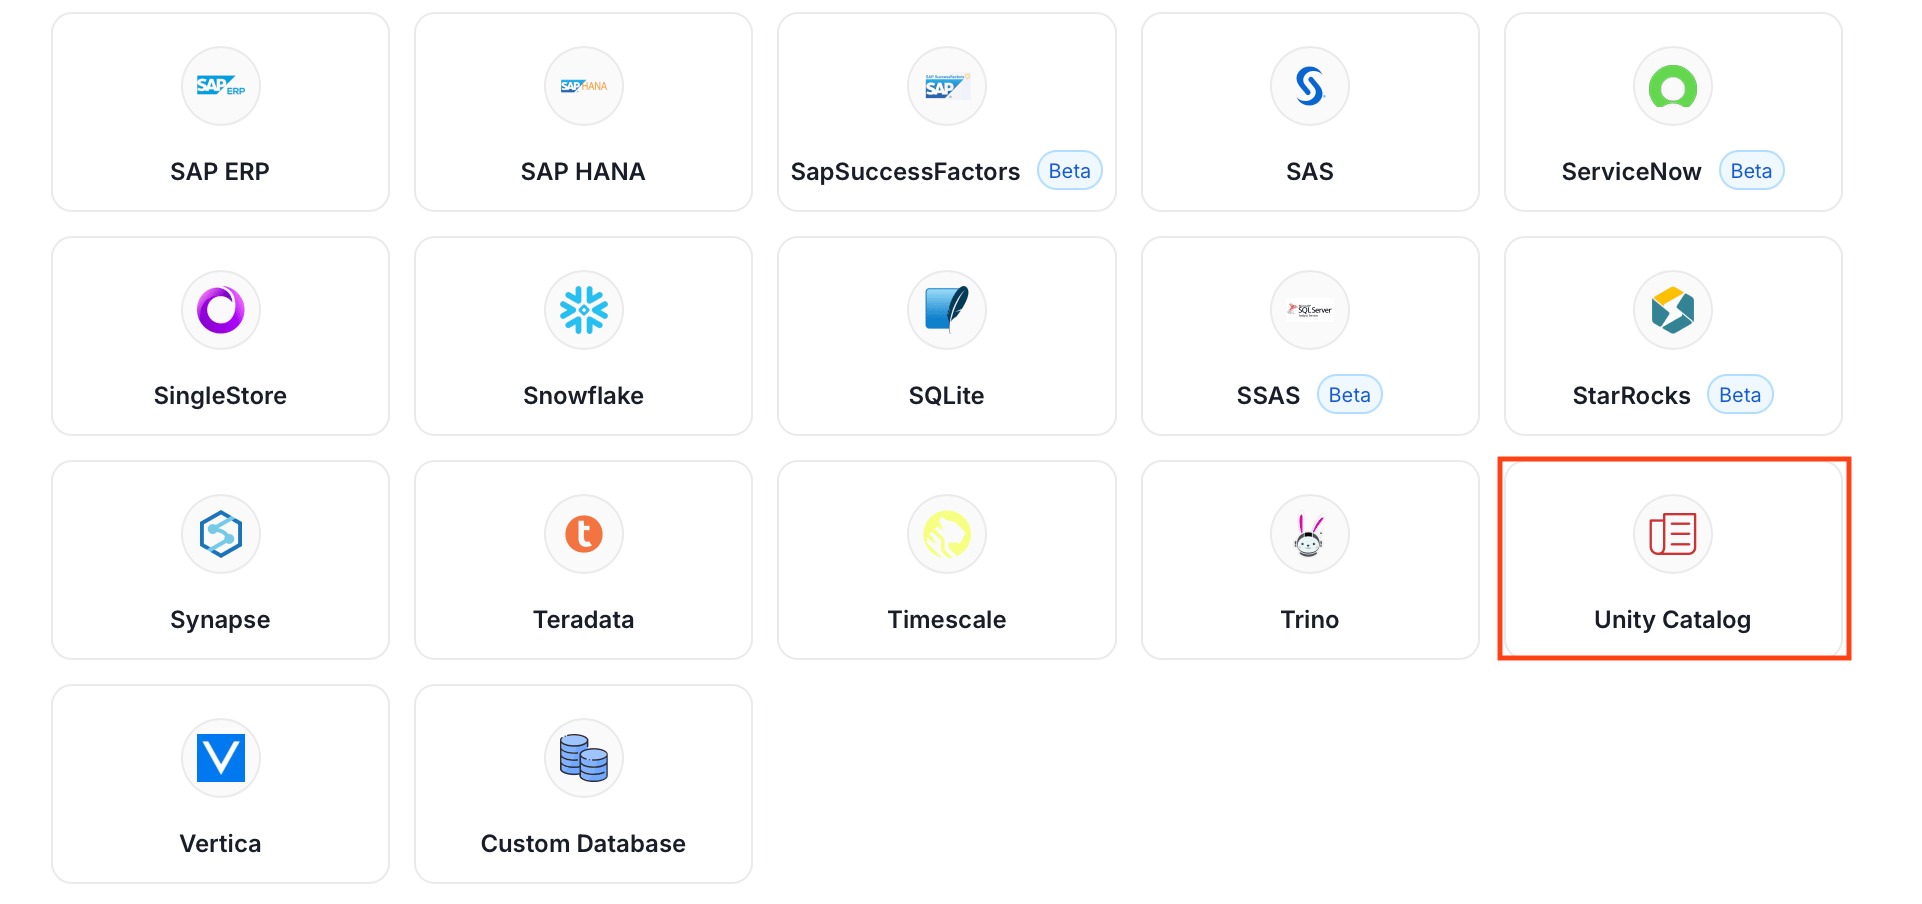
From the service type dropdown, select **Database Services**, then click the **Unity Catalog** connector tile.
<img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/select-service/unity-catalog.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=8ab0234fc41c07b61c42053dec97a54b" alt="Select Service" width="1922" height="904" data-path="public/images/connector2.0/metadata-ingestion/Database/select-service/unity-catalog.png" />

### Step 3: Add Service Name and Description

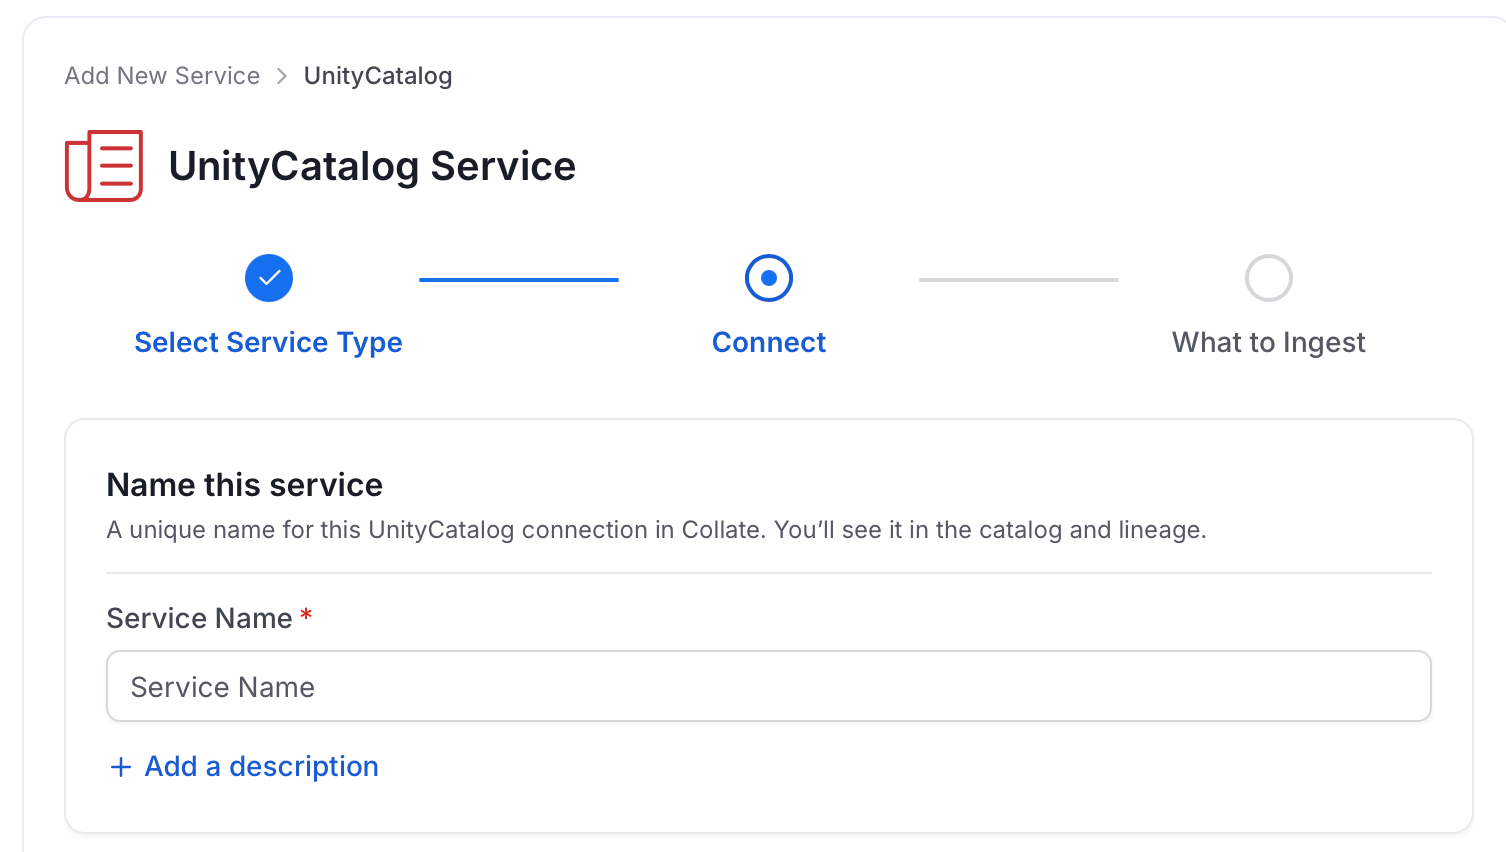
* Enter a unique, descriptive **Service Name**. OpenMetadata identifies services by their service name. Enter a name that distinguishes this deployment from other Unity Catalog services you are ingesting metadata from.
* Optional: Enter a **Description** for the service.
<img src="https://mintcdn.com/openmetadata/lclr4-hP2CvWdln8/public/images/connector2.0/metadata-ingestion/Database/service-name/unity-catalog.png?fit=max&auto=format&n=lclr4-hP2CvWdln8&q=85&s=d287f7d91c4033317fc9326f380777ca" alt="Configure Service" width="1506" height="852" data-path="public/images/connector2.0/metadata-ingestion/Database/service-name/unity-catalog.png" />

<Note>
  **Note**: The service name cannot be changed after it is set.
</Note>

### Step 4: Configure Connection Options

Specify your source credentials and verify the connection.

#### Enter Connection Details

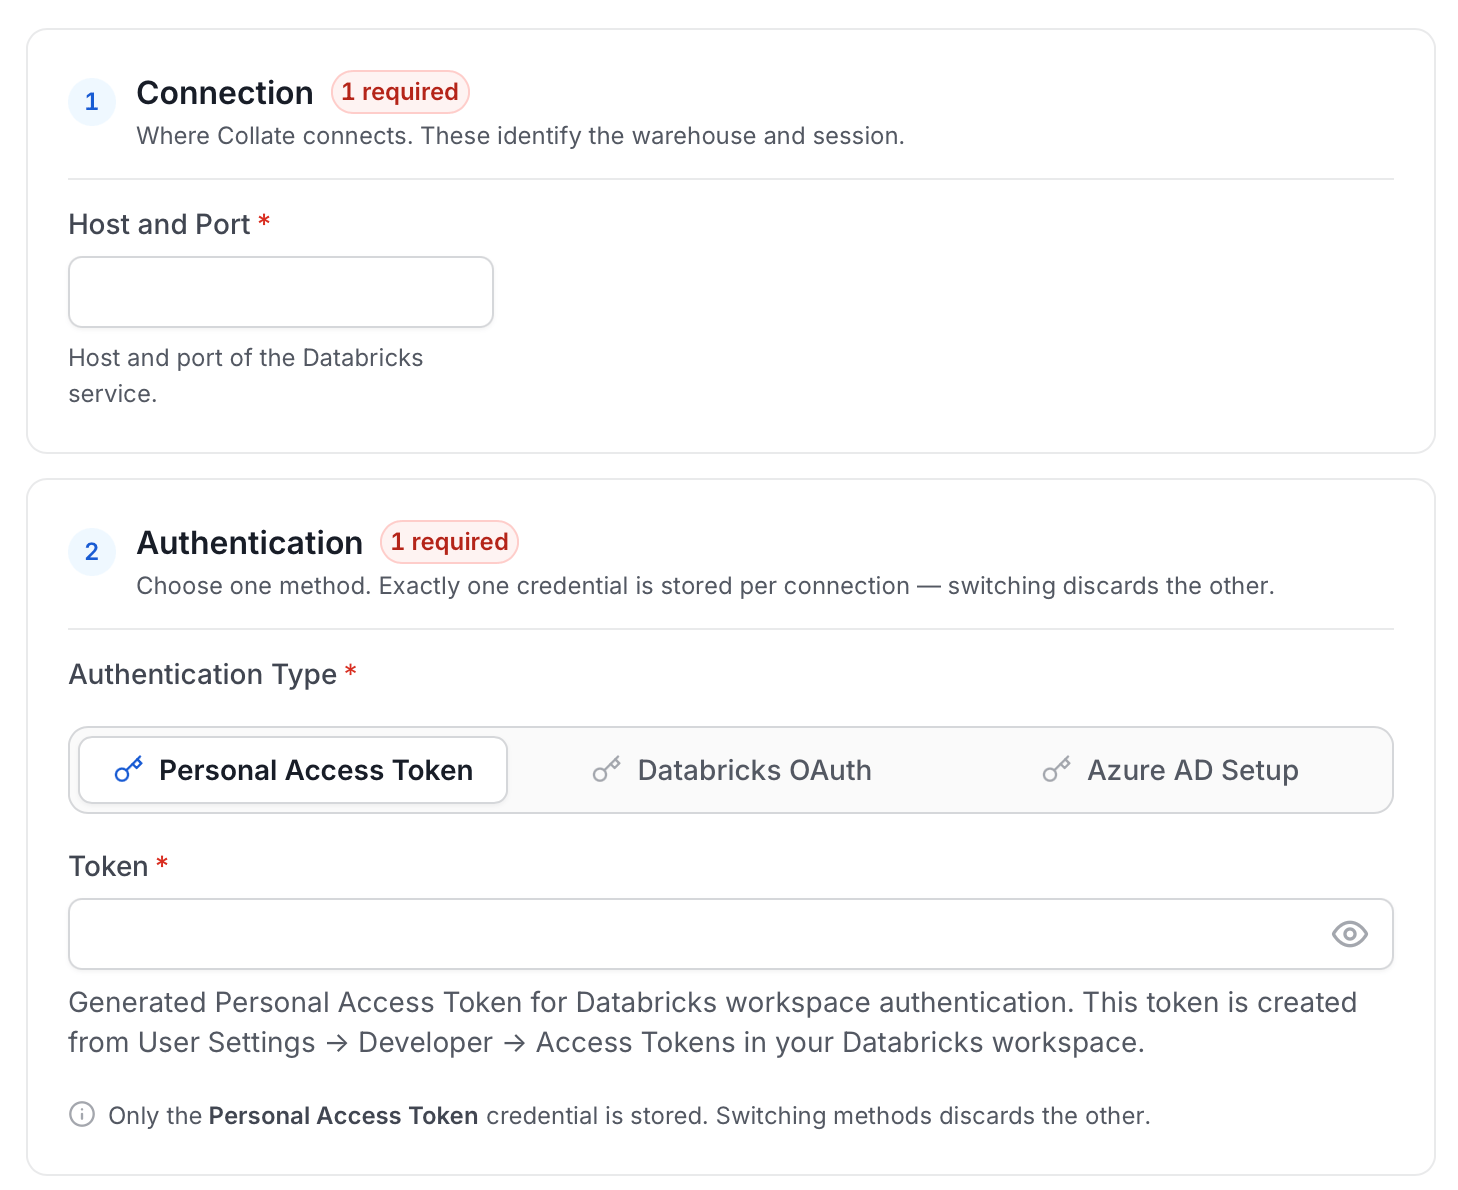
Enter the connection details for Unity Catalog. The right-hand panel in the UI displays inline help for each field.

<img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/connection-details/unity-catalog.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=bcf0c618c1a505391533644c38b46a87" alt="Configure Service Connection" width="1458" height="1190" data-path="public/images/connector2.0/metadata-ingestion/Database/connection-details/unity-catalog.png" />

**Connection**

* **Host and Port**: Enter the fully qualified hostname and port number for your Databricks deployment in the Host and Port field.
* **HTTP Path**: Databricks compute resources URL.

**Authentication**

Choose one of the following authentication methods:

* **Personal Access Token**: Provide the token generated from your Databricks workspace (**User Settings** > **Developer** > **Access Tokens**).
* **Databricks OAuth**: Provide the Service Principal `Client ID` and `Client Secret` created in your Databricks Account Console.
* **Azure AD Setup**: Provide the `Azure Client ID`, `Azure Client Secret`, and `Azure Tenant ID` from your Azure Active Directory Service Principal.

**Scope & Options**

* **connectionTimeout**: The maximum amount of time (in seconds) to wait for a successful connection to the data source. If the connection attempt takes longer than this timeout period, an error is returned.
* **Catalog**: Catalog of the data source (for example, `hive_metastore`). This is an optional parameter, if you would like to restrict the metadata reading to a single catalog. When left blank, OpenMetadata attempts to scan all catalogs.
* **Database Schema**: Database schema of the data source. This is an optional parameter, if you would like to restrict the metadata reading to a single database schema. When left blank, OpenMetadata attempts to scan all database schemas.

#### Test Connection

Once the credentials have been added, click on **Test Connection** and **Save** the changes.
<img src="https://mintcdn.com/openmetadata/9G75p72jJKYgvFUQ/public/images/connectors/test-connection.png?fit=max&auto=format&n=9G75p72jJKYgvFUQ&q=85&s=4ac71a56e30fa3dd1be86f82c1f07068" alt="Test Connection" width="1494" height="310" data-path="public/images/connectors/test-connection.png" />

### Step 5: Configure Ingestion Options

In the **What to Ingest** step, use filter patterns to control which assets OpenMetadata ingests from your database service. Filter patterns use regular expressions applied to asset names.

#### How Filter Patterns Work

* **Include**: Add one or more comma-separated regular expressions. OpenMetadata ingests only assets whose names match at least one expression. Leave blank to include all assets.
* **Exclude**: Add one or more comma-separated regular expressions. OpenMetadata skips any asset whose name matches an expression. Leave blank to exclude nothing.

Rules match asset names using one of five expressions:

* **contains**: matches any name containing the value. For example, `sales` matches `my_sales_data` and `sales_2024`.
* **starts with**: matches names beginning with the value. For example, `prod_` matches `prod_db` and `prod_schema`.
* **ends with**: matches names ending with the value. For example, `_raw` matches `events_raw` and `logs_raw`.
* **is exactly**: matches the exact name only. For example, `analytics` matches only `analytics`.
* **matches regex**: matches names using a regular expression. For example, `^prod_.*_v\d+$` matches `prod_events_v1`.

When both Include and Exclude are set, Exclude takes priority.
<Tip>
  Leave all filter patterns empty to ingest all databases, schemas, and tables available in the source.
</Tip>

**Filter Options**

The Database, Schema, and Table sections each include the following filter options:

* **Database**: Controls which databases OpenMetadata ingests from the source.
* **Schema**: Controls which schemas within the ingested databases are included.
* **Table**: Controls which tables and views within the ingested schemas are included.

Each section provides the following controls:

* **Scan Mode**: You can choose between the following scan modes:
  * **Scan all**: Ingests every asset of that type the connector can access. This is the default.
  * **Only specific**: Enables include rules so only assets matching at least one rule are ingested.
* **Exclude system toggle**: Use this toggle to automatically filter out system-reserved names defined by the connector, for example, **Exclude system databases** for the Databases section.
* **Always exclude**: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
* **Preview**: Shows a real-time summary of what will be in scope based on your current rules.
* **Include rules** *(available only in **Only specific** mode)*: Click **+ Add** to define a rule. Added rules appear as chips; an asset is included if it matches any rule.

### Step 6: Create & Deploy

Click **Create & Deploy** to deploy the agent and start the first metadata ingestion run. OpenMetadata saves the service configuration and immediately begins pulling metadata from the source.

To monitor ingestion progress or view the service you just added, go to **Settings** > **Services** and select your service.

## Configure Metadata Agent and Schedule Ingestion

The **Metadata Agent** extracts schemas, tables, columns, and other structural metadata from your source and keeps your OpenMetadata catalog in sync. It powers discovery, lineage, and governance across your data assets.

When you click **Create & Deploy**, OpenMetadata automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the **Agents** tab on the service detail page.

To configure the additional Metadata Agent and schedule ingestion, follow these steps:

1. Navigate to **Settings** > **Services** and select the service type.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/access-service-type.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=4471655da6e39d91776597e4a7eea513" alt="Navigate to Settings and Services" width="2992" height="1612" data-path="public/images/connector2.0/metadata-ingestion/access-service-type.png" />

2. Click the service you have added.

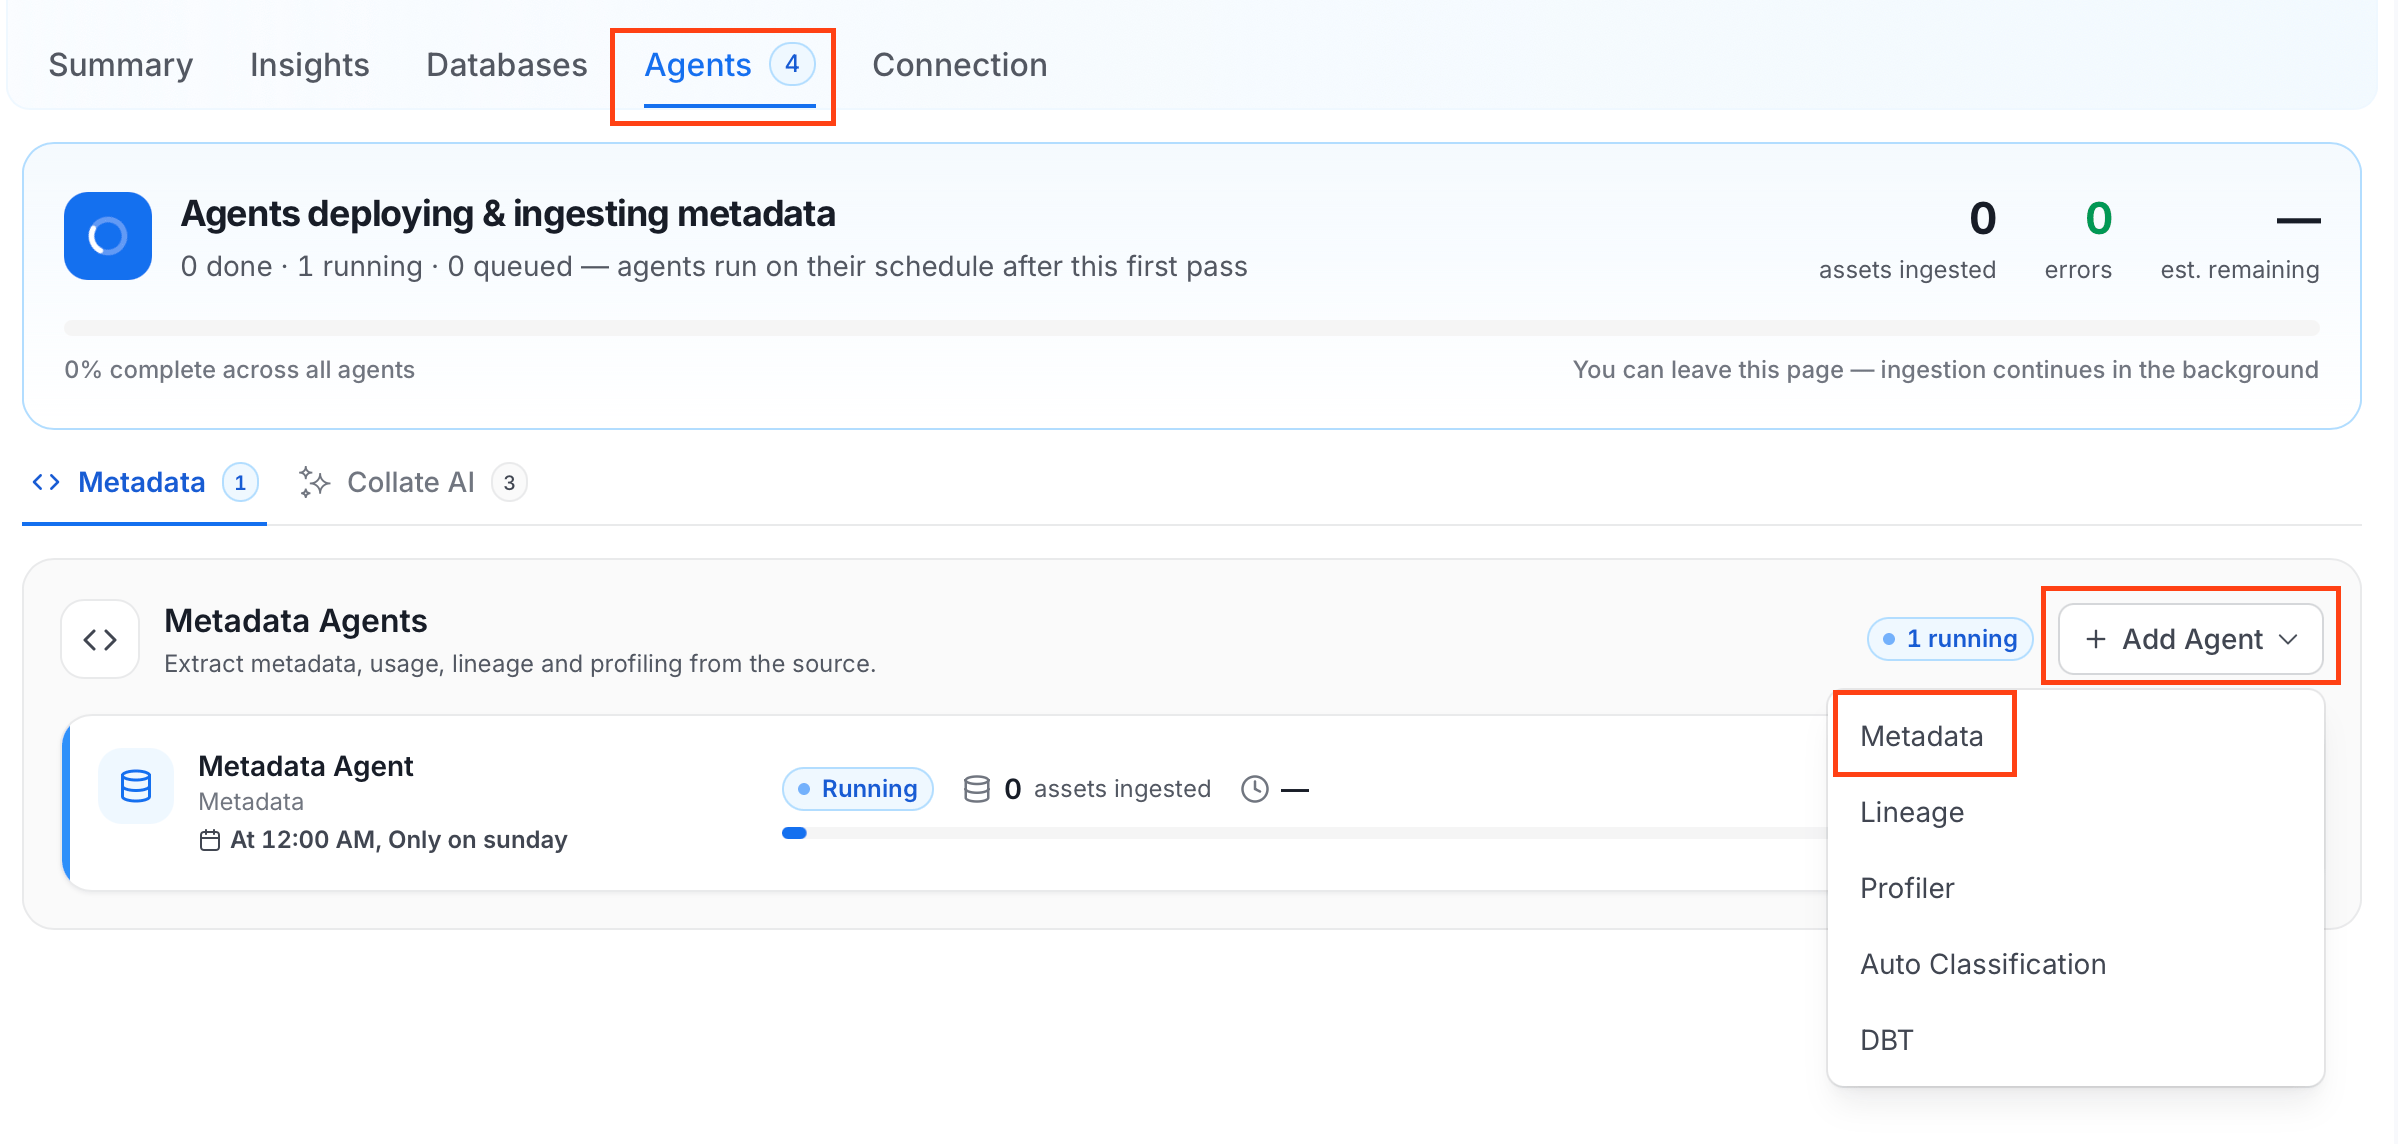
3. Select the **Agents** tab and click **Add Agent** > **Metadata**.
   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/add-metadata-agent.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=a654d9700126ce64cb6c9a99b8d69b1a" alt="Add Metadata Agent" width="2398" height="1144" data-path="public/images/connector2.0/metadata-ingestion/add-metadata-agent.png" />

   For some services, the dropdown is not available and clicking **Add Agent** takes you directly to the agent configuration page.

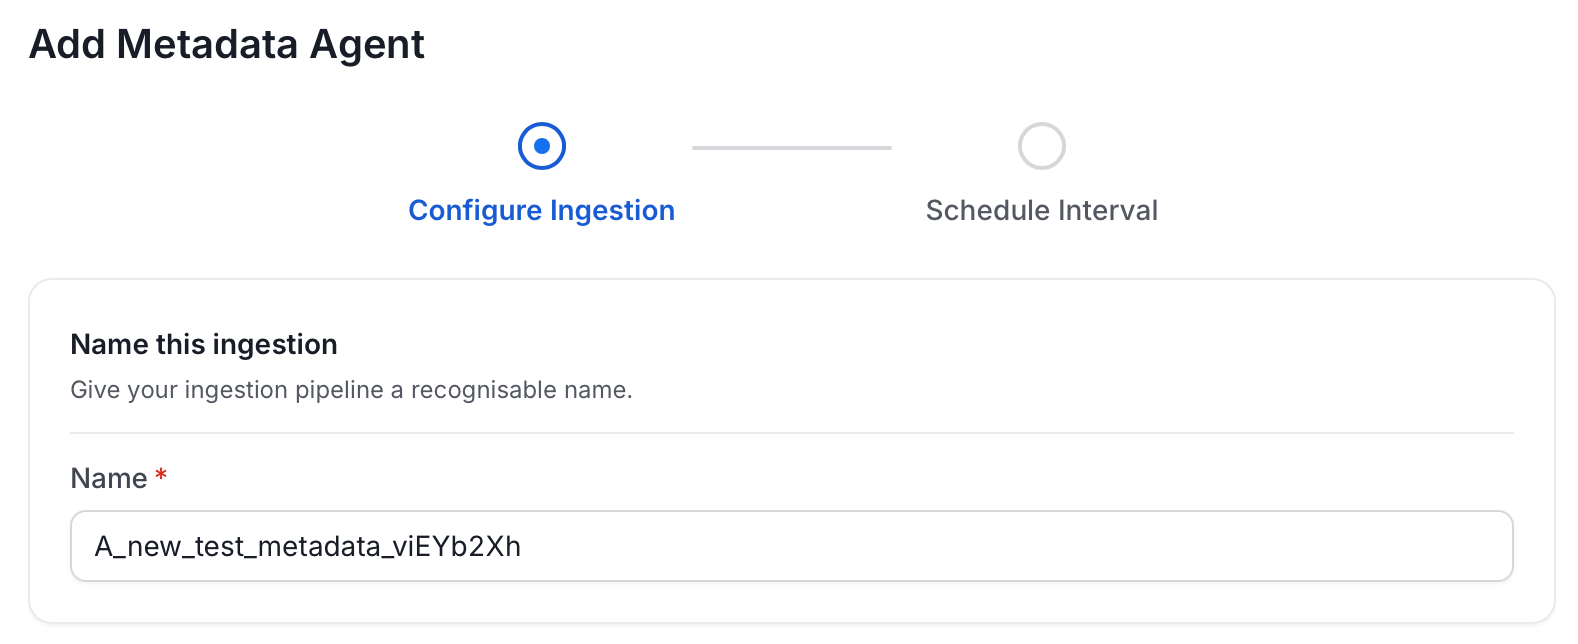
4. On the **Configure Ingestion** page, do the following and click **Next**.

   * **Name this Ingestion**: Enter a unique recognizable name for this ingestion pipeline.
     <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/metadata-agent-name.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=92954c166518e3ac07589ab20865e3e7" alt="Name this Ingestion" width="1578" height="644" data-path="public/images/connector2.0/metadata-ingestion/metadata-agent-name.png" />

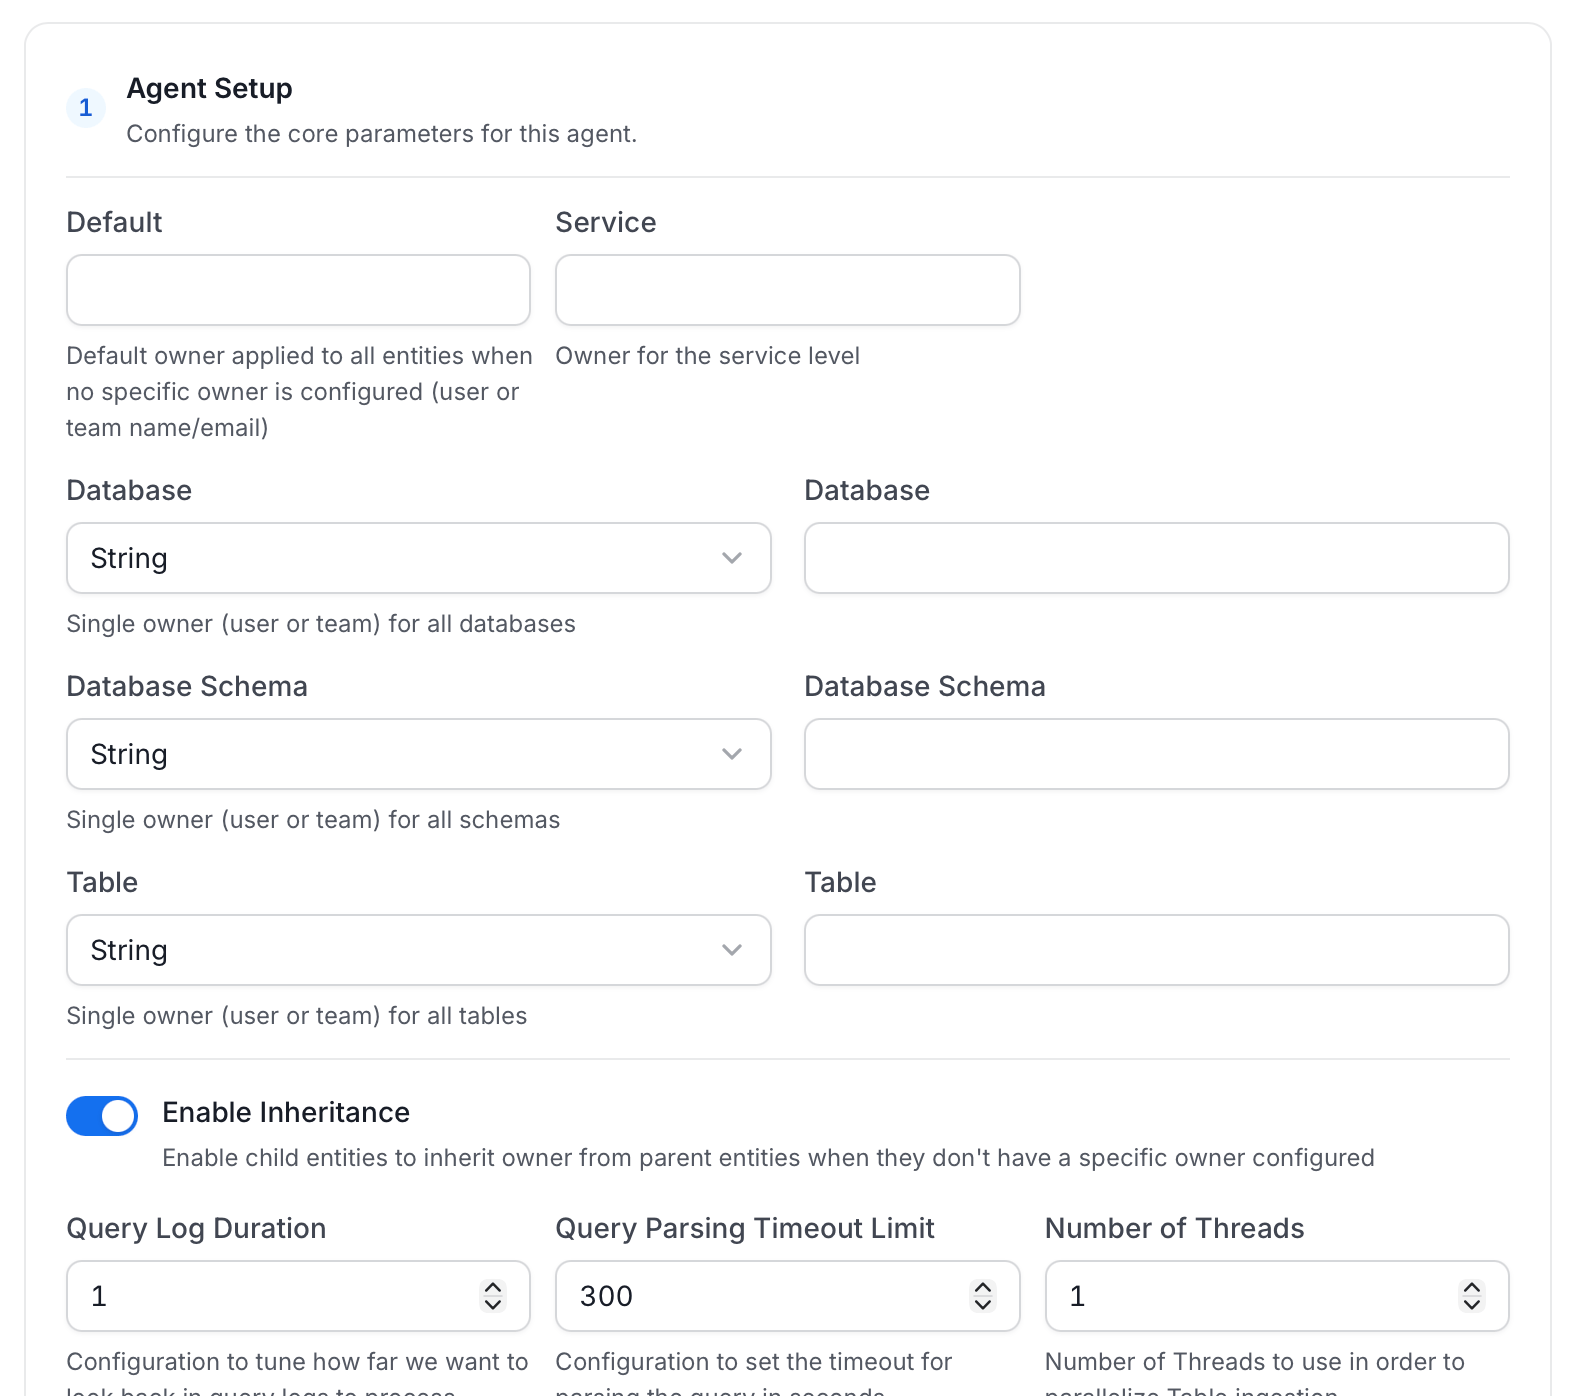
   * **Agent Setup**: Configure core parameters for metadata extraction. The following fields are available:

     | Field | Default | Description |
     | - | - | - |
     | **Default Owner** | — | Owner applied to any entity that has no owner from a more specific field below. Accepts a user or a team, by name or email. |
     | **Service Owner** | — | Owner assigned to the service entity itself (the connector/service you're setting up, not the data inside it). |
     | **Database Owner** | — | Owner assigned to every database this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per database. |
     | **Database Schema Owner** | — | Owner assigned to every schema this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per schema. |
     | **Table Owner** | — | Owner assigned to every table this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per table. |
     | **Enable Inheritance** | On | When on, an entity with no owner of its own inherits one from the nearest parent that has one, checked in this order: table, then schema, then database, then service, then Default Owner. Turn off if you want only the owners set explicitly above to apply, with no fallback. |
     | **Query Log Duration** | 1 | How many days of query logs to look back through when processing stored procedure results. |
     | **Query Parsing Timeout Limit** | 300 | How many seconds to spend parsing a single query before giving up on it and moving to the next. Raise this if large or complex queries are being skipped. |
     | **Number of Threads** | 1 | How many tables to ingest in parallel. Raising this can speed up ingestion on databases with many tables, at the cost of more load on the source. |
     | **Incremental Extraction** | Off | When on, a run extracts only entities that changed since the last successful run, instead of re-scanning everything every time. Faster on large, mostly unchanged databases. |
     | **Successful Pipeline Run Lookback Days** | 7 | Only used when Incremental Extraction is on. How many days back to search for a prior successful run to use as the starting point for what changed since then. |
     | **Safety Margin Days** | 1 | Only used when Incremental Extraction is on. Extra days added before that starting point, as a buffer so changes still in flight when the last run finished aren't missed. |
     | **Extract JSON Schema** | Off | Sample values in JSON columns to infer and ingest their schema, so the individual fields inside a JSON column are visible in OpenMetadata rather than just "JSON". Requires `SELECT` permission on the sampled tables. If that permission is missing, the JSON column is still ingested, just without a detailed schema. |
     | **JSON Schema Sample Size** | 10 | Only used when Extract JSON Schema is on. Number of rows sampled per JSON column to infer its schema. A larger sample gives more accurate results but takes longer to run. |

     For more information about how the Default Owner, Service Owner, Database Owner, Database Schema Owner, Table Owner, and Enable Inheritance fields resolve an owner, see [Hierarchical Owner Configuration](/connectors/ingestion/workflows/metadata/hierarchical-owner-configuration).
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-agent-setup.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=d0b1251c1b9aacd64c95278645f89127" alt="Agent Setup" width="1570" height="1396" data-path="public/images/connector2.0/metadata-ingestion/Database/database-agent-setup.png" />

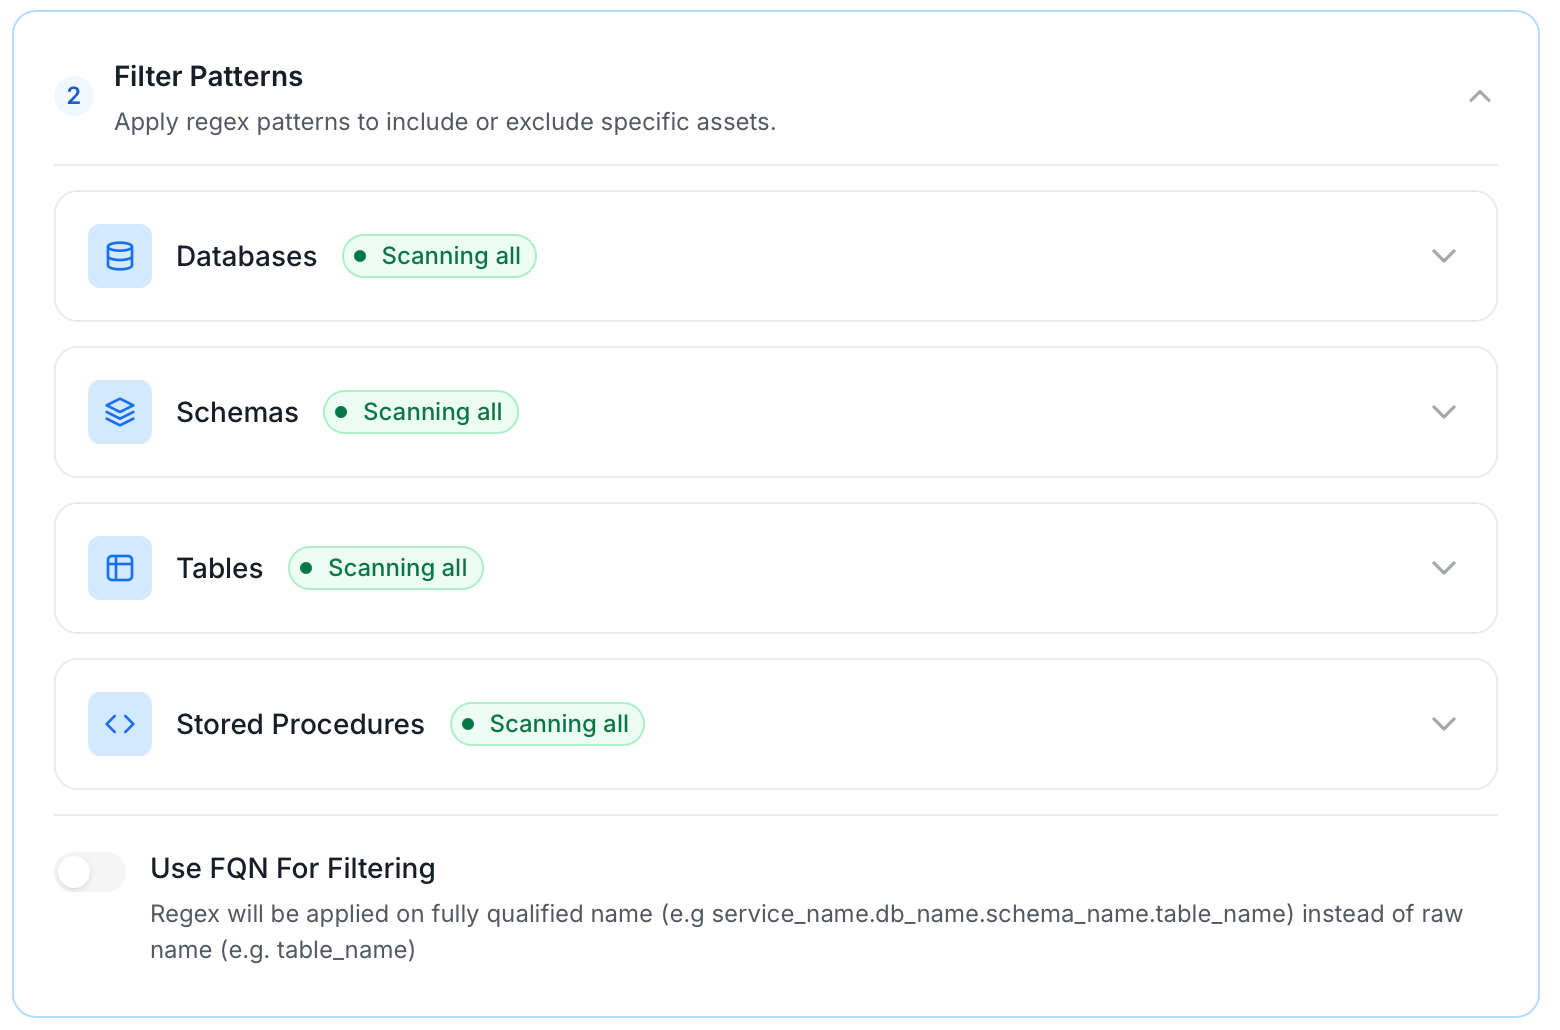
   * **Filter Patterns**: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. For more information about various filter options, see **Step 6: Configure Ingestion Options**.
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-filter-pattern.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=cc4693554363e81232fde8c3fb602e25" alt="Filter Patterns" width="1560" height="1030" data-path="public/images/connector2.0/metadata-ingestion/Database/database-filter-pattern.png" />

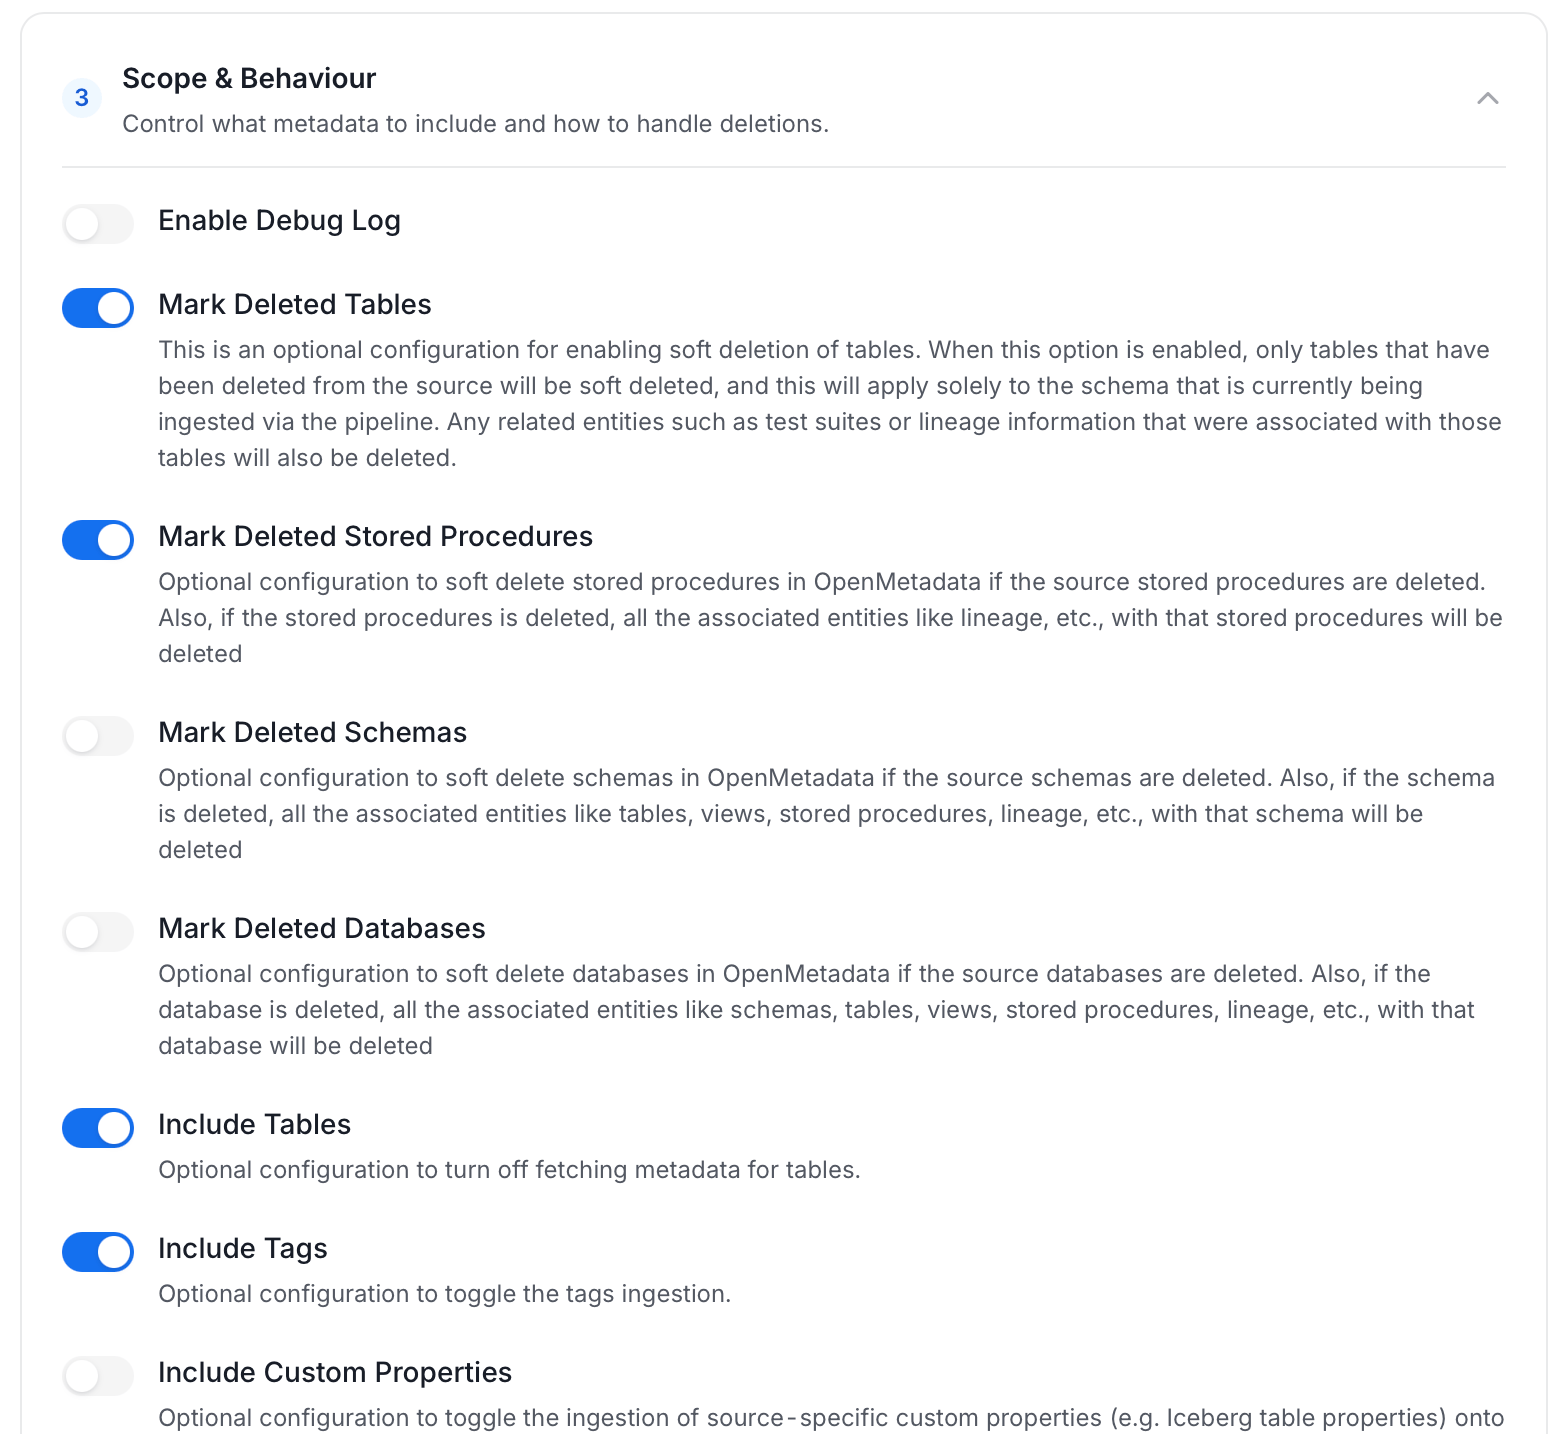
   * **Scope & Behaviour**: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:

     | Toggle | Default | Description |
     | - | - | - |
     | **Include Tables** | On | Ingest tables and their columns. Turn off to skip tables entirely, for example if this agent exists only to pull tags or stored procedures. |
     | **Include Tags** | On | Ingest tags already defined on tables/columns in the source system (for example, a classification tag applied in Snowflake) and bring them into OpenMetadata as tags on the same assets. |
     | **Include Stored Procedures** | On | Ingest stored procedures as their own assets, so they show up in the catalog and can be linked into lineage. |
     | **Include DDL Statements** | Off | Also ingest the raw `CREATE TABLE` / `CREATE VIEW` statement for each asset, so it's viewable in OpenMetadata alongside the asset's metadata. |
     | **Include Owners** | Off | When an ingested asset's owner in the source system is an email that matches an existing OpenMetadata user, assign that user as the asset's owner. Never overwrites an owner an asset already has in OpenMetadata. |
     | **Include Custom Properties** | Off | Ingest source-specific metadata that doesn't map to a standard OpenMetadata field (for example, a database-specific attribute) into custom properties on the asset, if custom properties have been defined for that entity type. |
     | **Mark Deleted Tables** | On | If a table this agent previously ingested no longer exists in the source, soft-delete it in OpenMetadata too. Only affects tables within schemas this agent actually scans. |
     | **Mark Deleted Stored Procedures** | On | Same as Mark Deleted Tables, but for stored procedures. |
     | **Mark Deleted Schemas** | Off | If an entire schema this agent previously ingested no longer exists in the source, soft-delete the schema and everything in it. |
     | **Mark Deleted Databases** | Off | If an entire database this agent previously ingested no longer exists in the source, soft-delete the database and everything in it. |
     | **Override Metadata** | Off | On: values from the source (descriptions, tags, owners, display names) overwrite what's currently in OpenMetadata, even if someone edited it there. A description or display name that the source doesn't send never replaces an existing value, and existing table constraints are kept when the source sends none. Override replaces tags only within the classifications the source sends, so tags from other classifications and glossary terms are kept. Retention periods that users set are kept. Off: OpenMetadata only fills in fields that are still empty, so manual edits in OpenMetadata are preserved. |
     | **Enable Debug Log** | Off | Run this ingestion at DEBUG log verbosity instead of the normal level. Turn on when troubleshooting a failing or unexpected run. Leave off otherwise, since debug logs are much larger. |
     <Note>
       Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
     </Note>

     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-scope-behaviour.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=03b790d0d7ce6a5f75f46002b06dcc05" alt="Scope & Behaviour" width="1566" height="1436" data-path="public/images/connector2.0/metadata-ingestion/Database/database-scope-behaviour.png" />

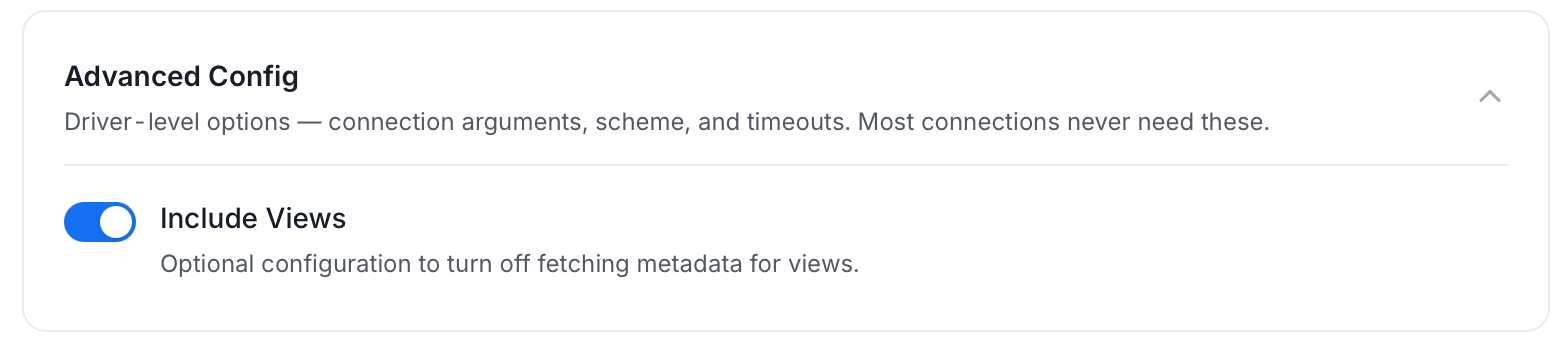
   * **Advanced Config**: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:

     | Toggle | Default | Description |
     | - | - | - |
     | **Include Views** | On | Ingest views in addition to tables. Turn off to skip views entirely. Since view lineage is derived from parsing each view's SQL definition, turning this off also stops view-based lineage from being generated for this service. |
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-advance.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=70399f49ea960130062a9cd3c91a1840" alt="Advanced Config" width="1564" height="352" data-path="public/images/connector2.0/metadata-ingestion/Database/database-advance.png" />

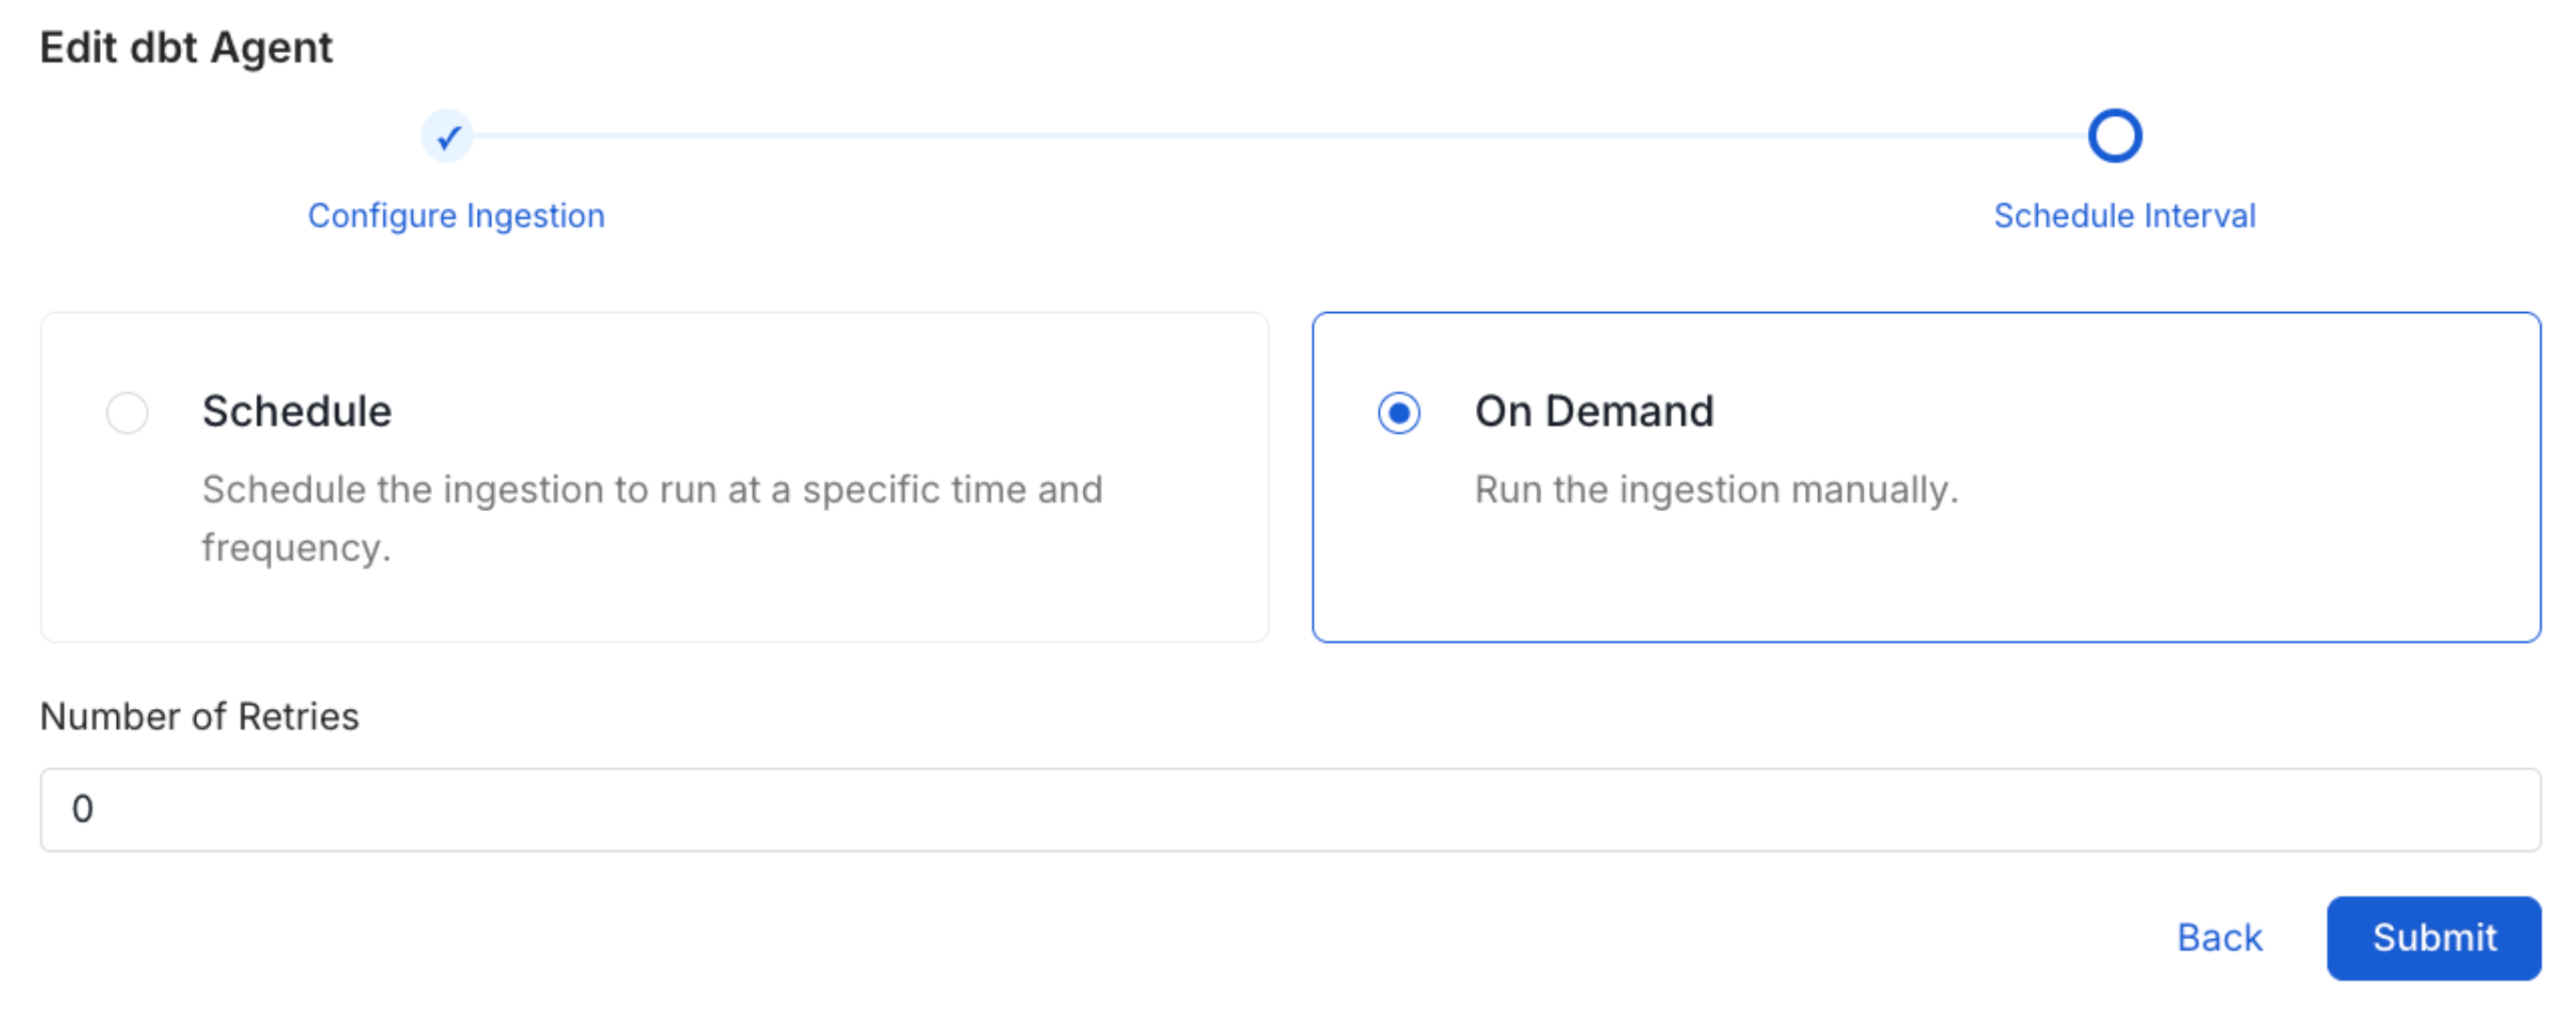
5. On the **Schedule Interval** page, set when the agent runs:

   * **Schedule**: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
   * **On-Demand**: No automatic schedule; trigger the agent manually when needed.
   <img src="https://mintcdn.com/openmetadata/j50Bw6ZBiFbbFFnF/public/images/connectors/schedule.png?fit=max&auto=format&n=j50Bw6ZBiFbbFFnF&q=85&s=24b0c2f55f803efde5fb3b3bc24ed3ae" alt="Schedule Interval" width="2733" height="1083" data-path="public/images/connectors/schedule.png" />

6. Click **Add** to deploy the agent.

## Related

<Columns cols={2}>
  <Card title="Usage Workflow" href="/v2.0.x/connectors/ingestion/workflows/usage">
    Learn more about how to configure the Usage Workflow to ingest Query information from the UI.
  </Card>

  <Card title="Lineage Workflow" href="/v2.0.x/connectors/ingestion/workflows/lineage">
    Learn more about how to configure the Lineage from the UI.
  </Card>

  <Card title="Profiler Workflow" href="/v2.0.x/how-to-guides/data-quality-observability/profiler/profiler-workflow">
    Learn more about how to configure the Data Profiler from the UI.
  </Card>

  <Card title="Data Quality Workflow" href="/v2.0.x/how-to-guides/data-quality-observability/quality/configure">
    Learn more about how to configure the Data Quality tests from the UI.
  </Card>

  <Card title="dbt Integration" href="/v2.0.x/connectors/database/dbt">
    Learn more about how to ingest dbt models' definitions and their lineage.
  </Card>
</Columns>


This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.