> ## Documentation Index
> Fetch the complete documentation index at: https://docs.open-metadata.org/llms.txt
> Use this file to discover all available pages before exploring further.

# ClickZetta Connector | OpenMetadata Database Integration

> Connect ClickZetta to OpenMetadata with the database connector guide. Step-by-step setup, configuration examples, and metadata extraction tips.

export const ConnectorDetailsHeader = ({name, icon, stage, availableFeatures, unavailableFeatures = [], availableFeaturesCollate = []}) => {
  const showSubHeading = availableFeatures?.length > 0 || unavailableFeatures?.length > 0 || availableFeaturesCollate?.length > 0;
  const totalAvailableFeatures = [...availableFeatures || [], ...availableFeaturesCollate || []];
  return <div className="container">
      <div className="Heading">
        <div className="flex items-center gap-3">
          {icon && <div className="IconContainer">
              <img src={icon} alt={name} noZoom className="ConnectorIcon" />
            </div>}
          <h1 className="ConnectorName">{name}</h1>
          <span className={`StageBadge ${stage === 'PROD' ? 'prod' : 'beta'}`}>
            {stage}
          </span>
        </div>
      </div>
      {showSubHeading && <div className="SubHeading">
          <div className="FeaturesHeading">Feature List</div>
          <div className="FeaturesList">
            {totalAvailableFeatures.map(feature => <div className="FeatureTag AvailableFeature" key={feature}>
                ✓ {feature}
              </div>)}
            {unavailableFeatures.map(feature => <div className="FeatureTag UnavailableFeature" key={feature}>
                ✕ {feature}
              </div>)}
          </div>
        </div>}
    </div>;
};

<ConnectorDetailsHeader icon="/public/images/connectors/clickzetta.svg" name="ClickZetta" stage="BETA" availableFeatures={["Metadata", "Query Usage", "Lineage", "Column-level Lineage", "Data Profiler", "Data Quality", "dbt", "Sample Data", "Auto-Classification"]} unavailableFeatures={["Owners", "Tags", "Stored Procedures"]} />

This section provides guides and references for the ClickZetta connector.
Configure and schedule ClickZetta metadata and profiler workflows from the OpenMetadata UI:

* [Requirements](#requirements)
* [Metadata Ingestion](#metadata-ingestion)
* [Troubleshooting](/v2.1.x-SNAPSHOT/connectors/database/clickzetta/troubleshooting)

## Requirements

OpenMetadata connects to ClickZetta with a SQLAlchemy driver, using a username and password and a virtual cluster to run its read-only queries. The connecting user needs to be able to use that virtual cluster and to read the catalog, the tables you want to ingest, and the query-history view.

Grant the following to the role your ingestion user connects with:

```sql theme={null}
-- Allow the user's role to run queries on the virtual cluster used for ingestion
GRANT USAGE ON VCLUSTER <virtual_cluster> TO ROLE <role>;

-- Allow reading metadata and data from the schemas you want to ingest
GRANT SELECT ON SCHEMA <workspace>.<schema_name> TO ROLE <role>;
```

### Profiler and Data Quality

Running the profiler workflow, data quality tests, or data diff requires `SELECT` on the tables and schemas being profiled or tested. The profiler uses ClickZetta's native sampling to keep profiling efficient. For more information, see [Profiler Workflow](/v2.1.x-SNAPSHOT/how-to-guides/data-quality-observability/profiler/profiler-workflow) and [Data Quality](/v2.1.x-SNAPSHOT/how-to-guides/data-quality-observability/quality).

### Usage and Lineage

Query Usage and query-based lineage read from a ClickZetta query-history source. Grant `SELECT` on the query-history view you configure:

```sql theme={null}
-- Workspace-local history
GRANT SELECT ON TABLE information_schema.job_history TO ROLE <role>;
-- or cross-workspace history
GRANT SELECT ON TABLE sys.information_schema.job_history TO ROLE <role>;
```

For more information, see [Usage Workflow](/v2.1.x-SNAPSHOT/connectors/ingestion/workflows/usage) and [Lineage Workflow](/v2.1.x-SNAPSHOT/connectors/ingestion/workflows/lineage).

## Metadata Ingestion

To ingest metadata from ClickZetta, you need to create a service connection. The service connects ClickZetta with OpenMetadata. After you create the service and deploy the metadata agent, OpenMetadata starts ingesting metadata.

### Step 1: Add New Service

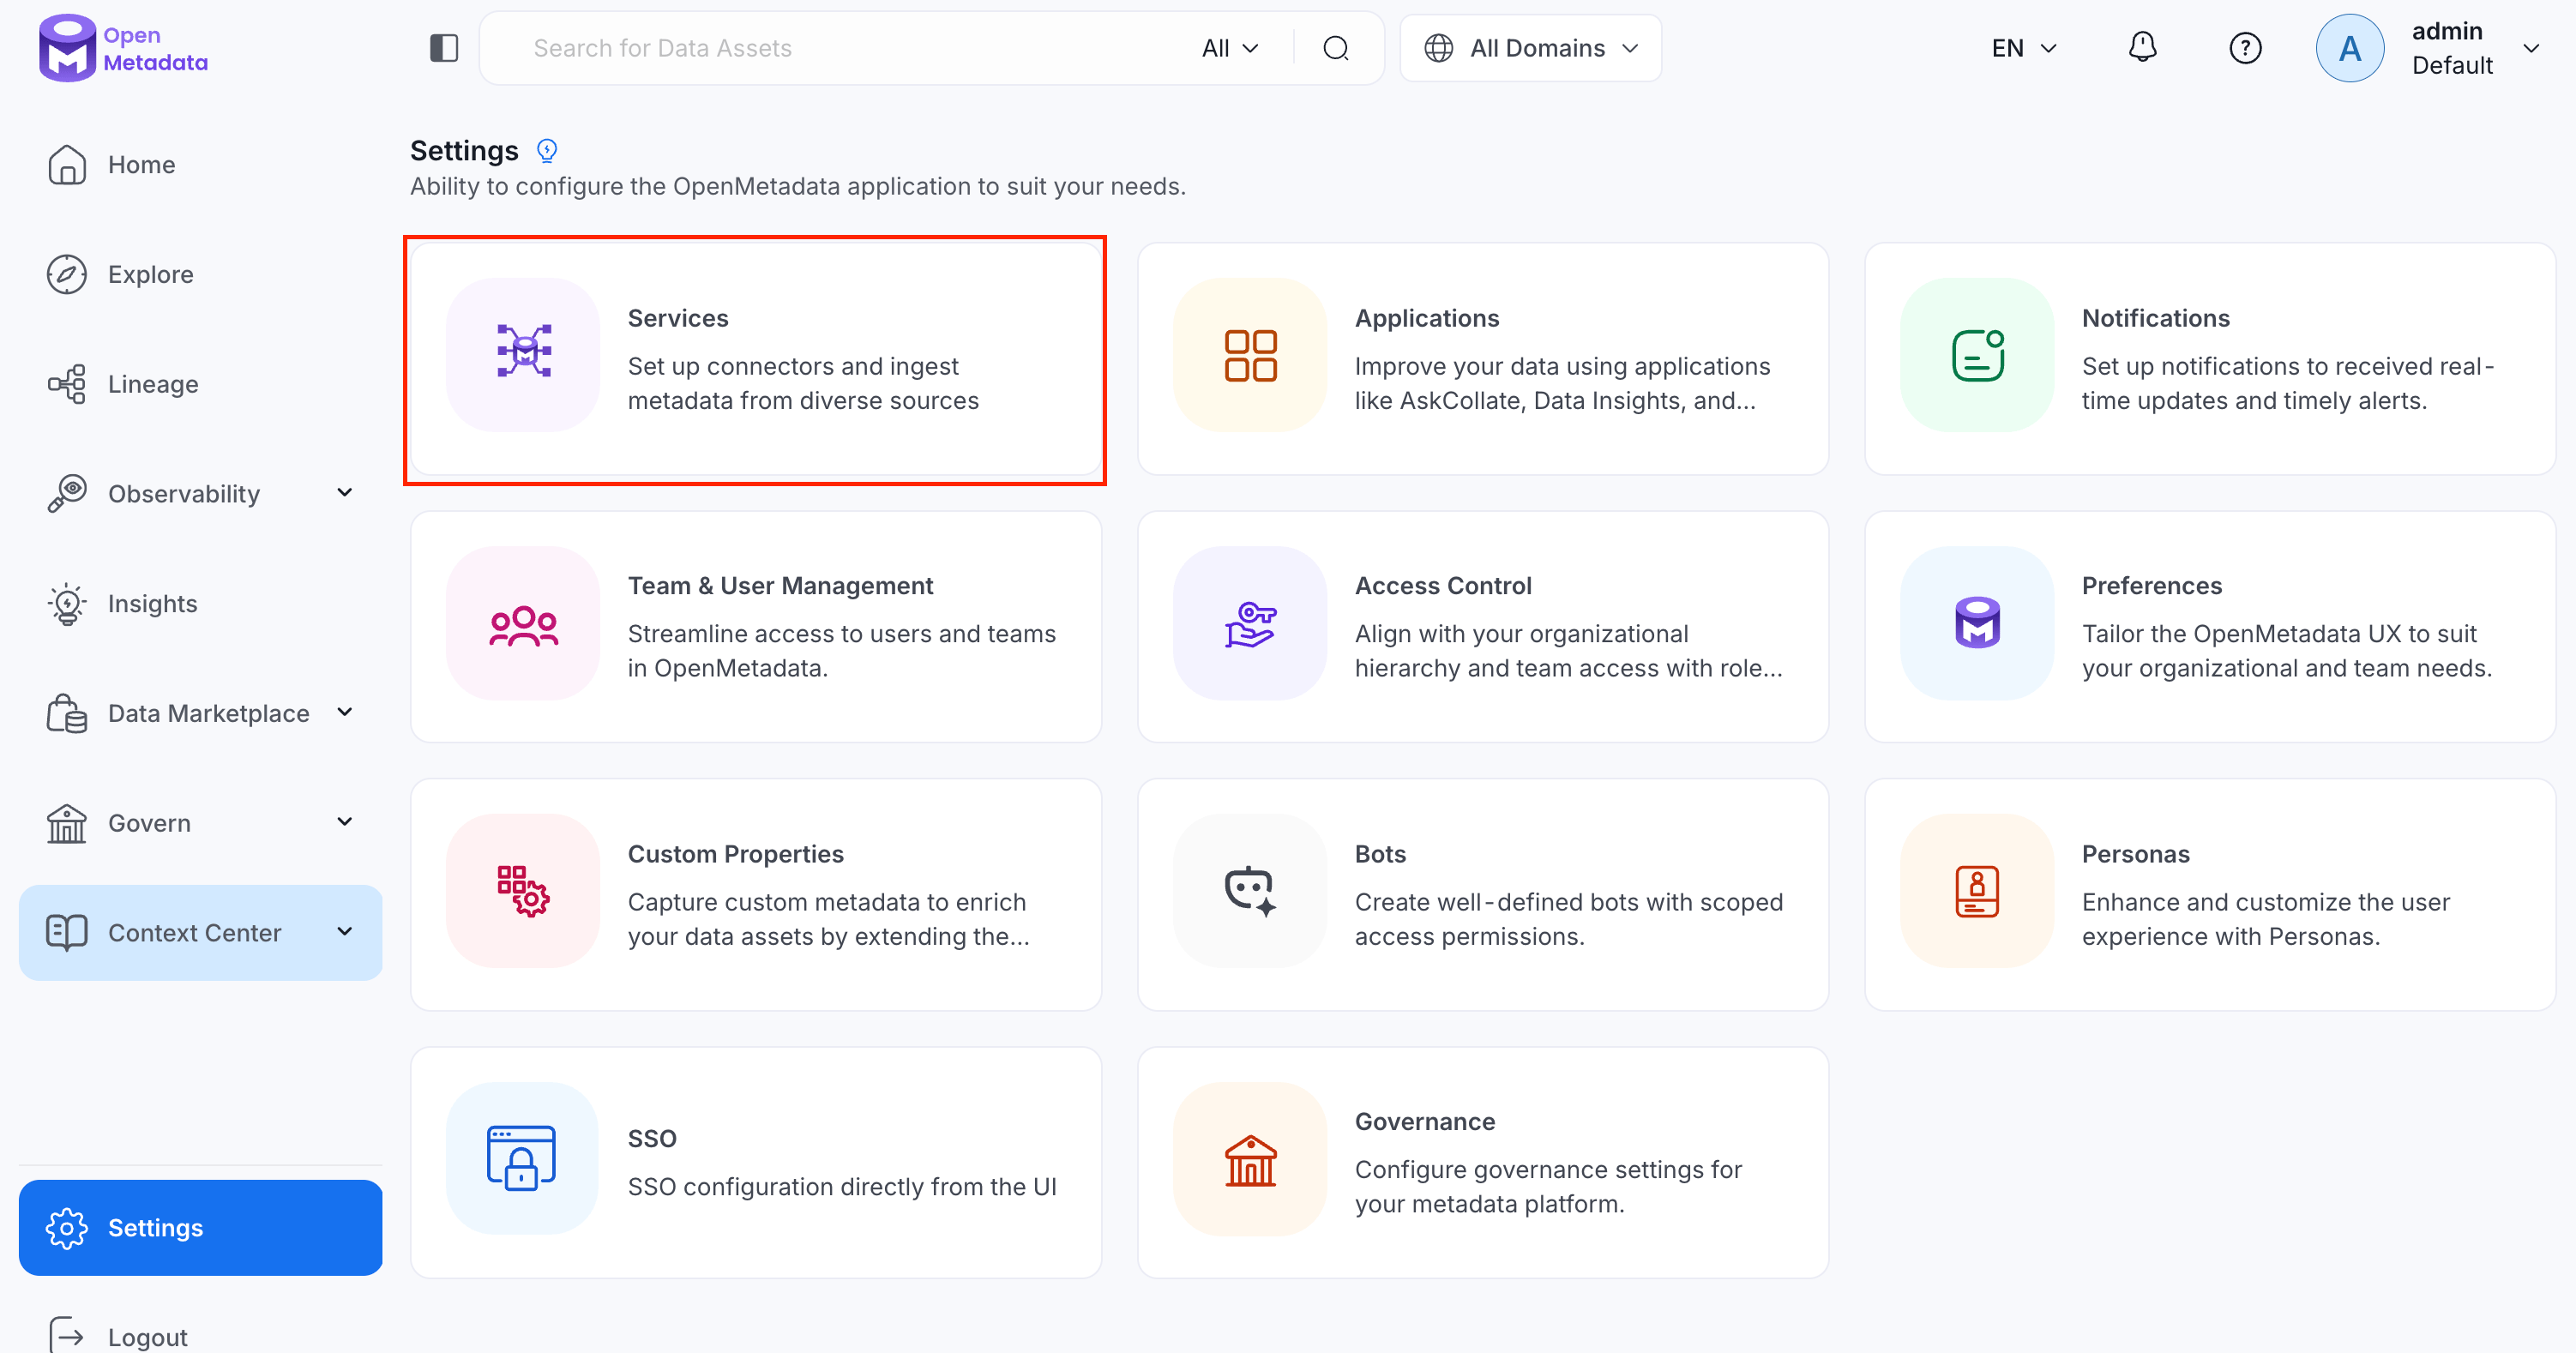
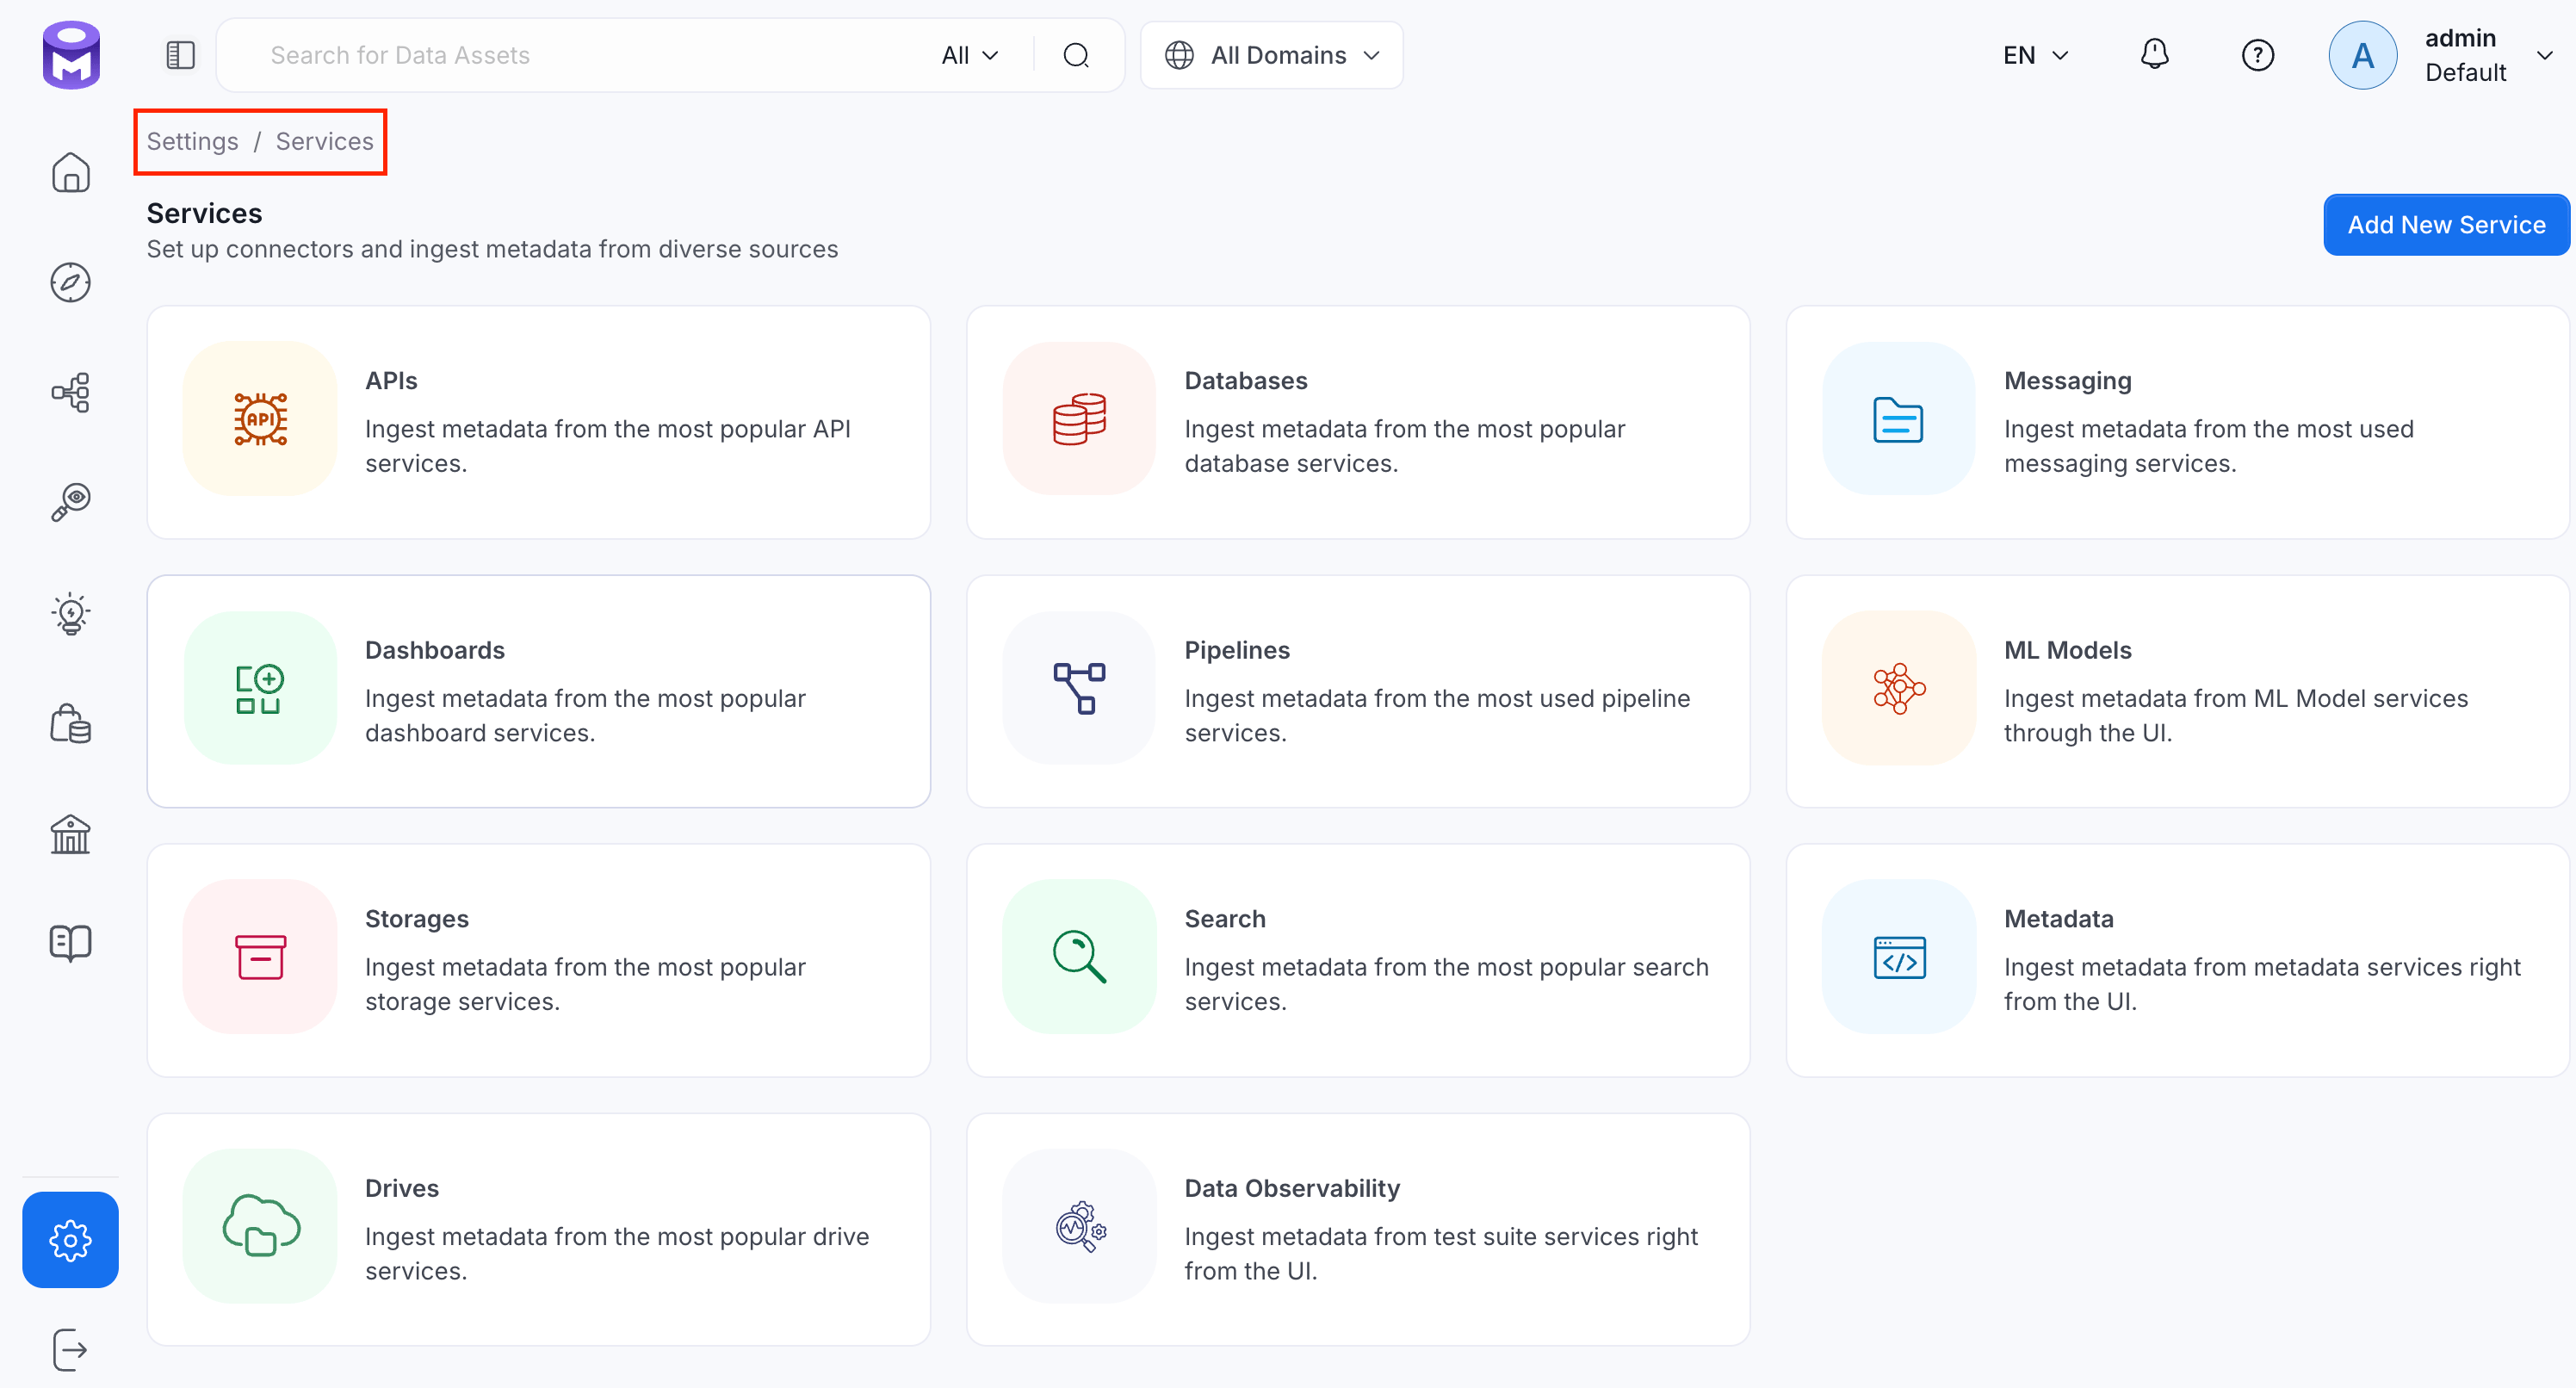
1. Navigate to **Settings** > **Services**.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/access-services.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=c95e6e79c73eea68039c10115c7f80d6" alt="Navigate to Settings and Services" width="3004" height="1578" data-path="public/images/connector2.0/metadata-ingestion/access-services.png" />

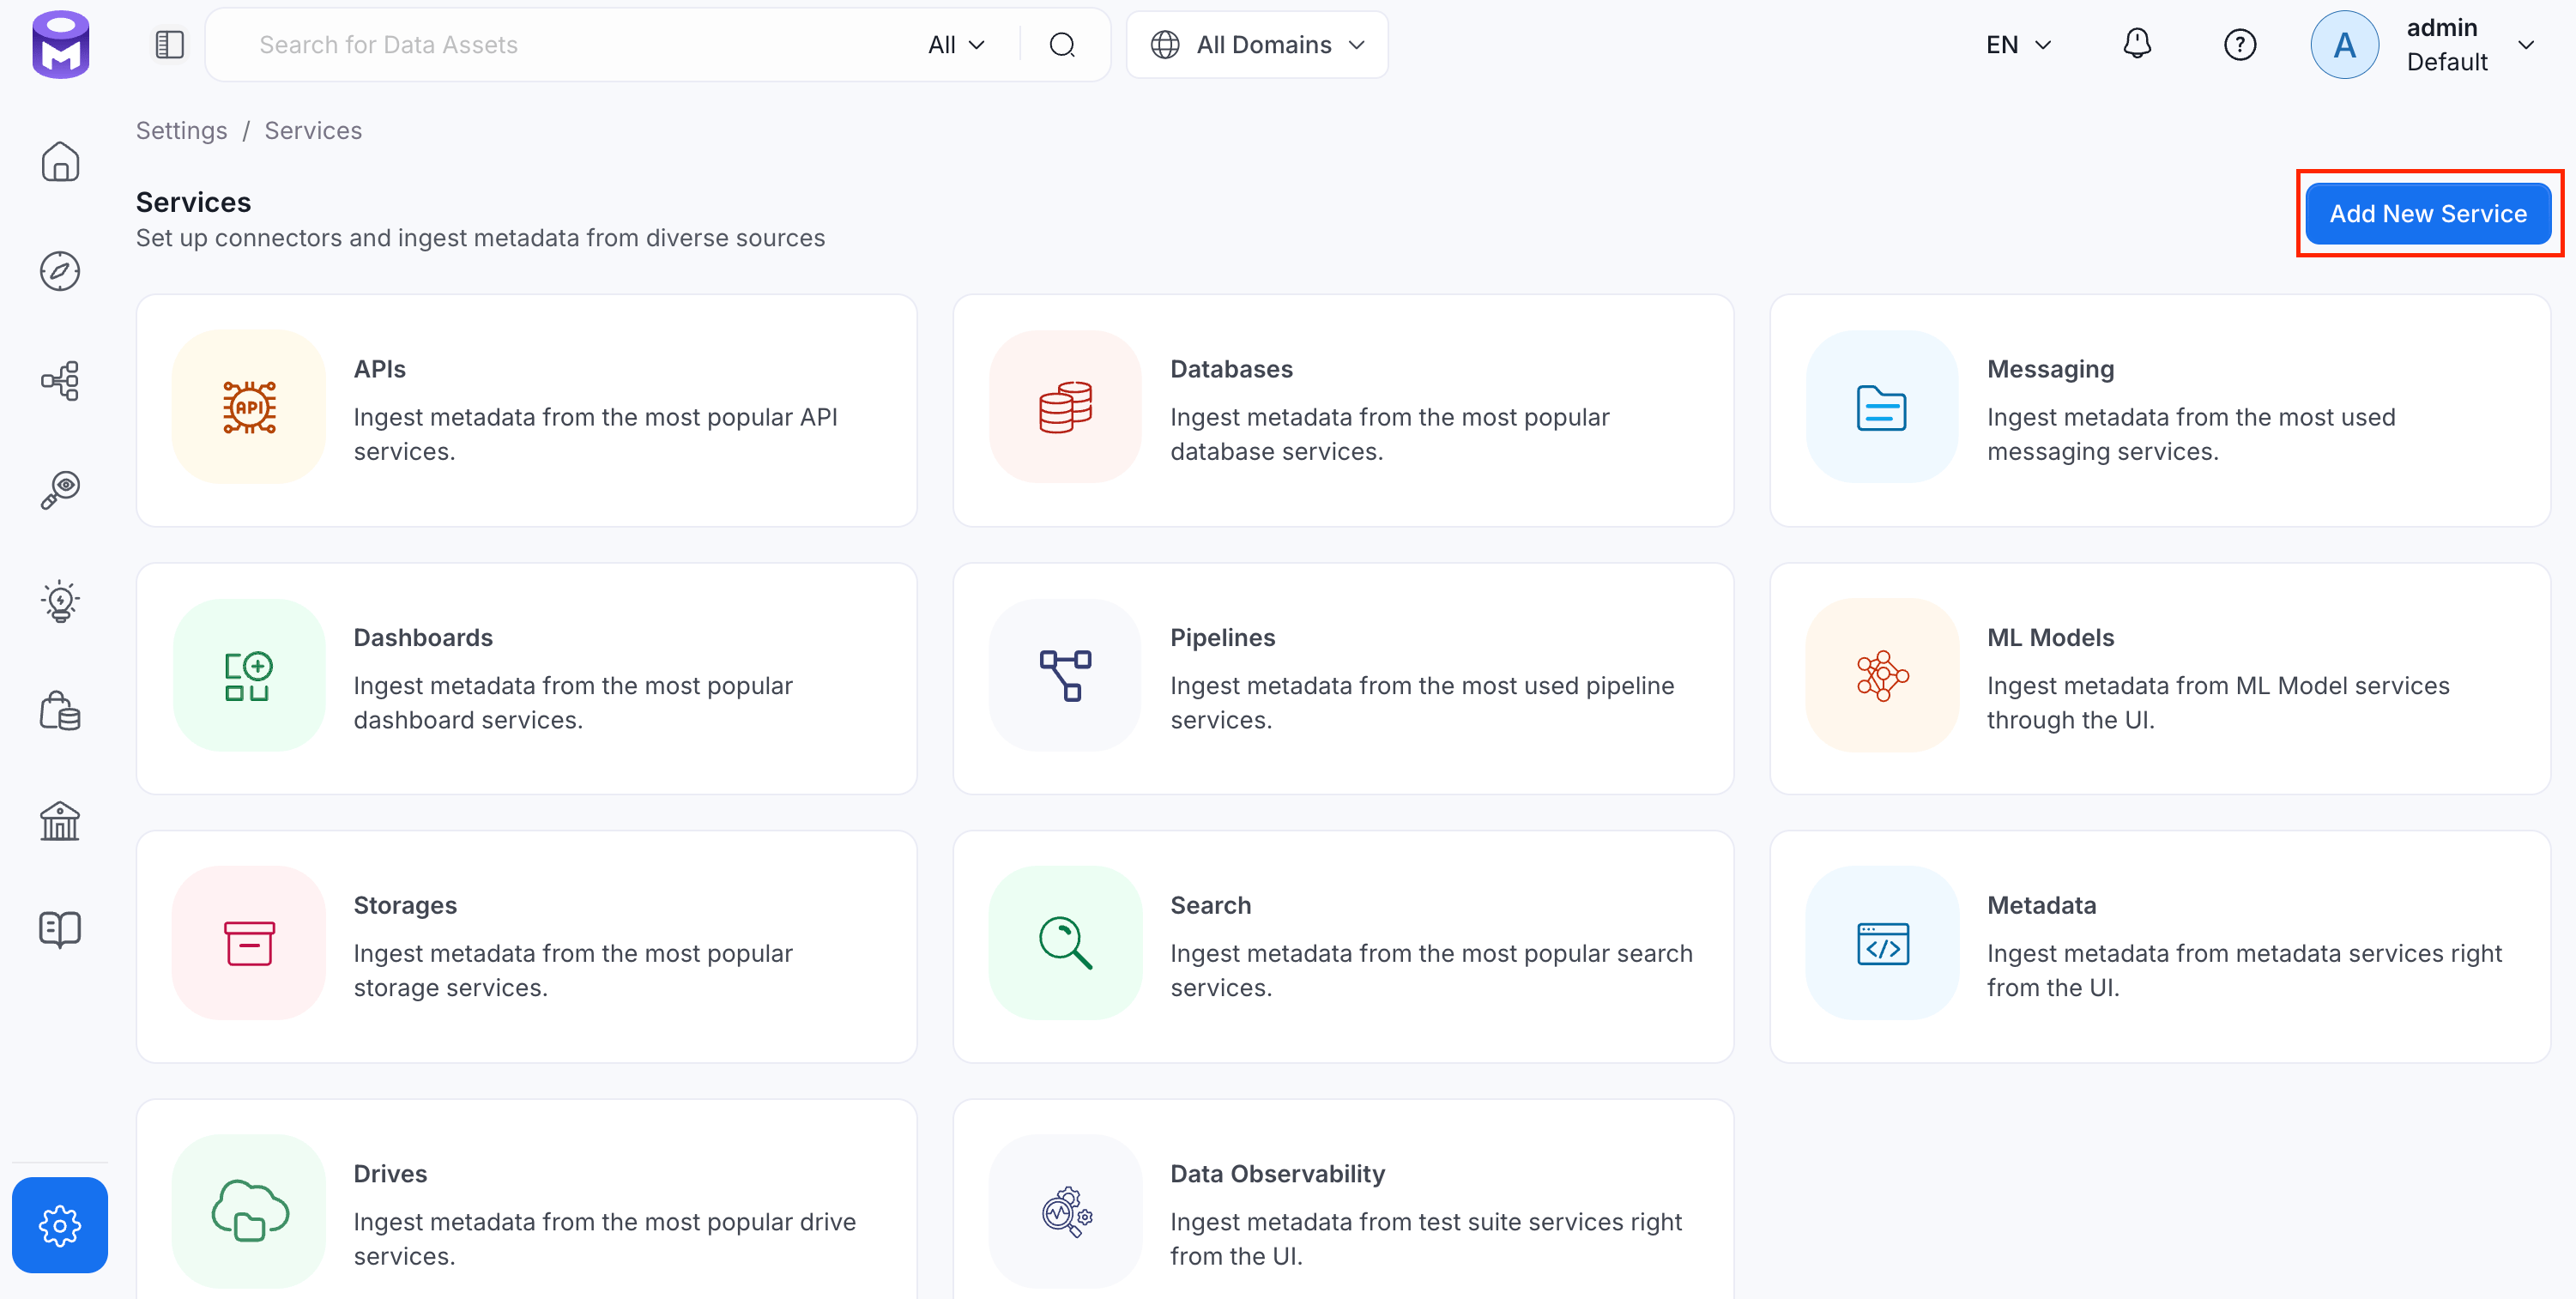
2. Click **Add New Service**.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/add-new-service.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=13457ef6e565aa39d339db30ce1f354d" alt="Add New Service" width="3002" height="1514" data-path="public/images/connector2.0/metadata-ingestion/add-new-service.png" />

### Step 2: Select a Service and Connector

From the service type dropdown, select **Database Services**, then click the **Clickzetta** connector tile.
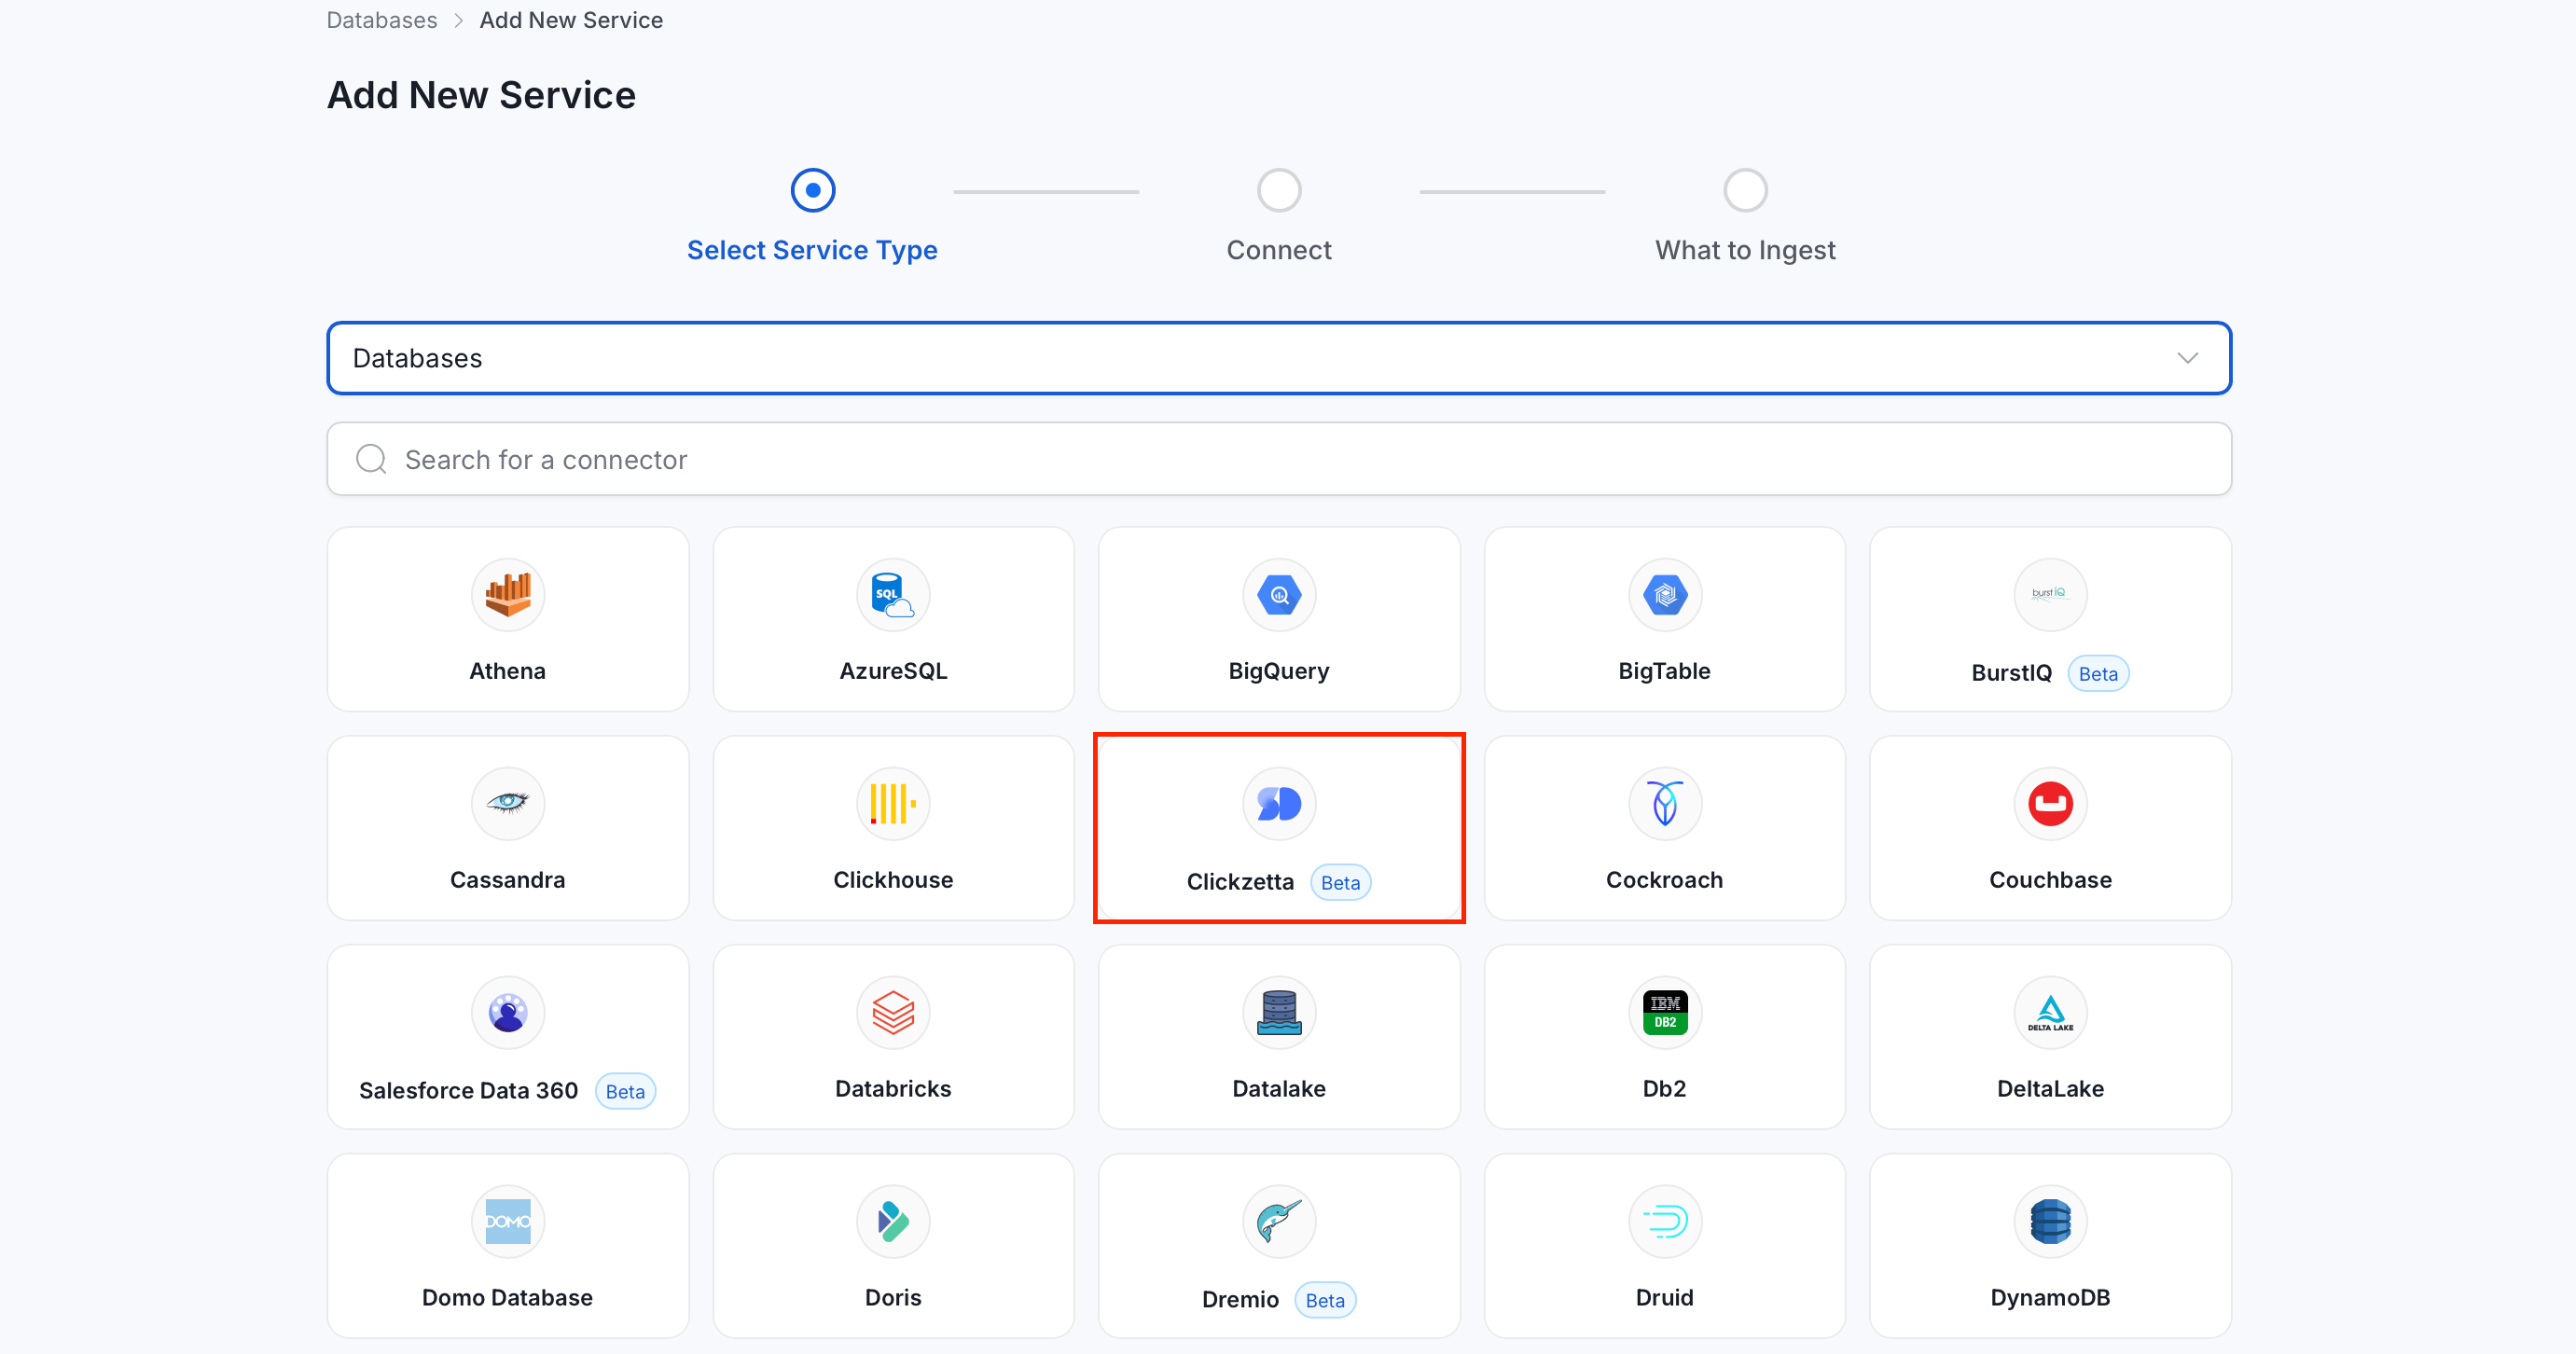
<img src="https://mintcdn.com/openmetadata/btXC0_YmKX84TZhC/public/images/connector2.0/metadata-ingestion/Database/select-service/clickzetta.png?fit=max&auto=format&n=btXC0_YmKX84TZhC&q=85&s=122aca0339e013ff18d03162db582852" alt="Select Service" width="2762" height="1452" data-path="public/images/connector2.0/metadata-ingestion/Database/select-service/clickzetta.png" />

### Step 3: Add Service Name and Description

* Enter a unique, descriptive **Service Name**. OpenMetadata identifies services by their service name. Enter a name that distinguishes this deployment from other ClickZetta services you're ingesting metadata from.
* Optional: Enter a **Description** for the service.
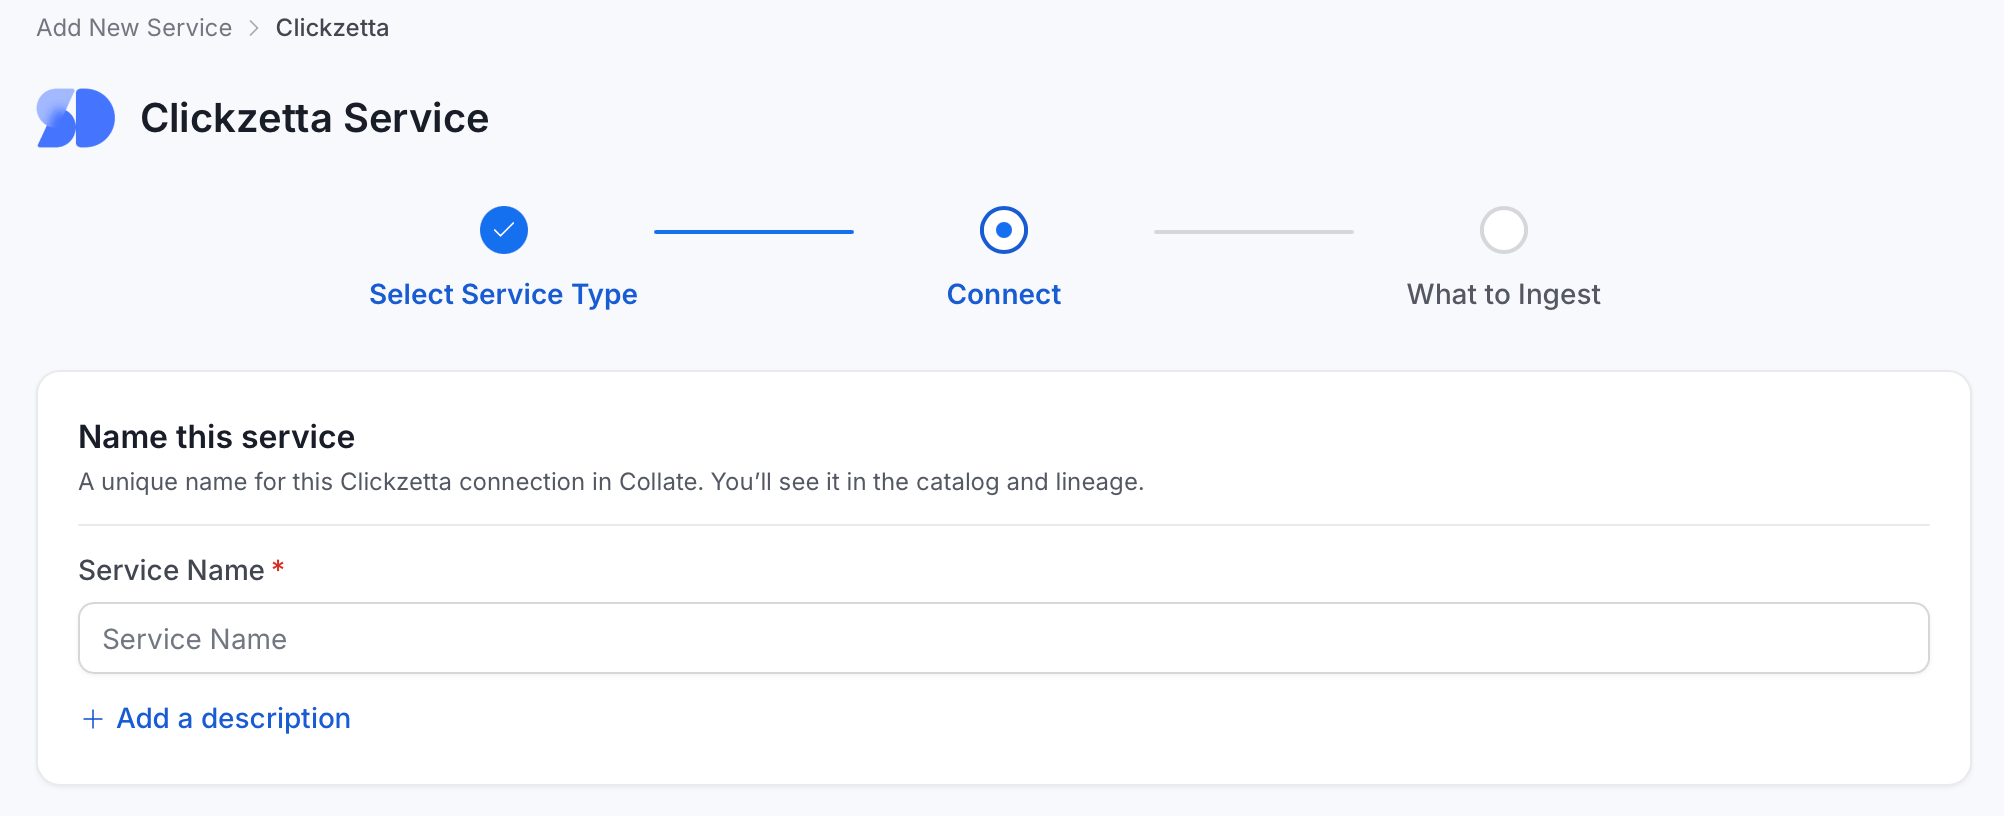
<img src="https://mintcdn.com/openmetadata/btXC0_YmKX84TZhC/public/images/connector2.0/metadata-ingestion/Database/service-name/clickzetta.png?fit=max&auto=format&n=btXC0_YmKX84TZhC&q=85&s=b27cfac50027d8398472a80064245712" alt="Add New Service Name" width="2004" height="816" data-path="public/images/connector2.0/metadata-ingestion/Database/service-name/clickzetta.png" />

<Note>
  The service name can't be changed after it's set.
</Note>

### Step 4: Configure Connection Options

Specify your source credentials and verify the connection.

#### Enter Connection Details

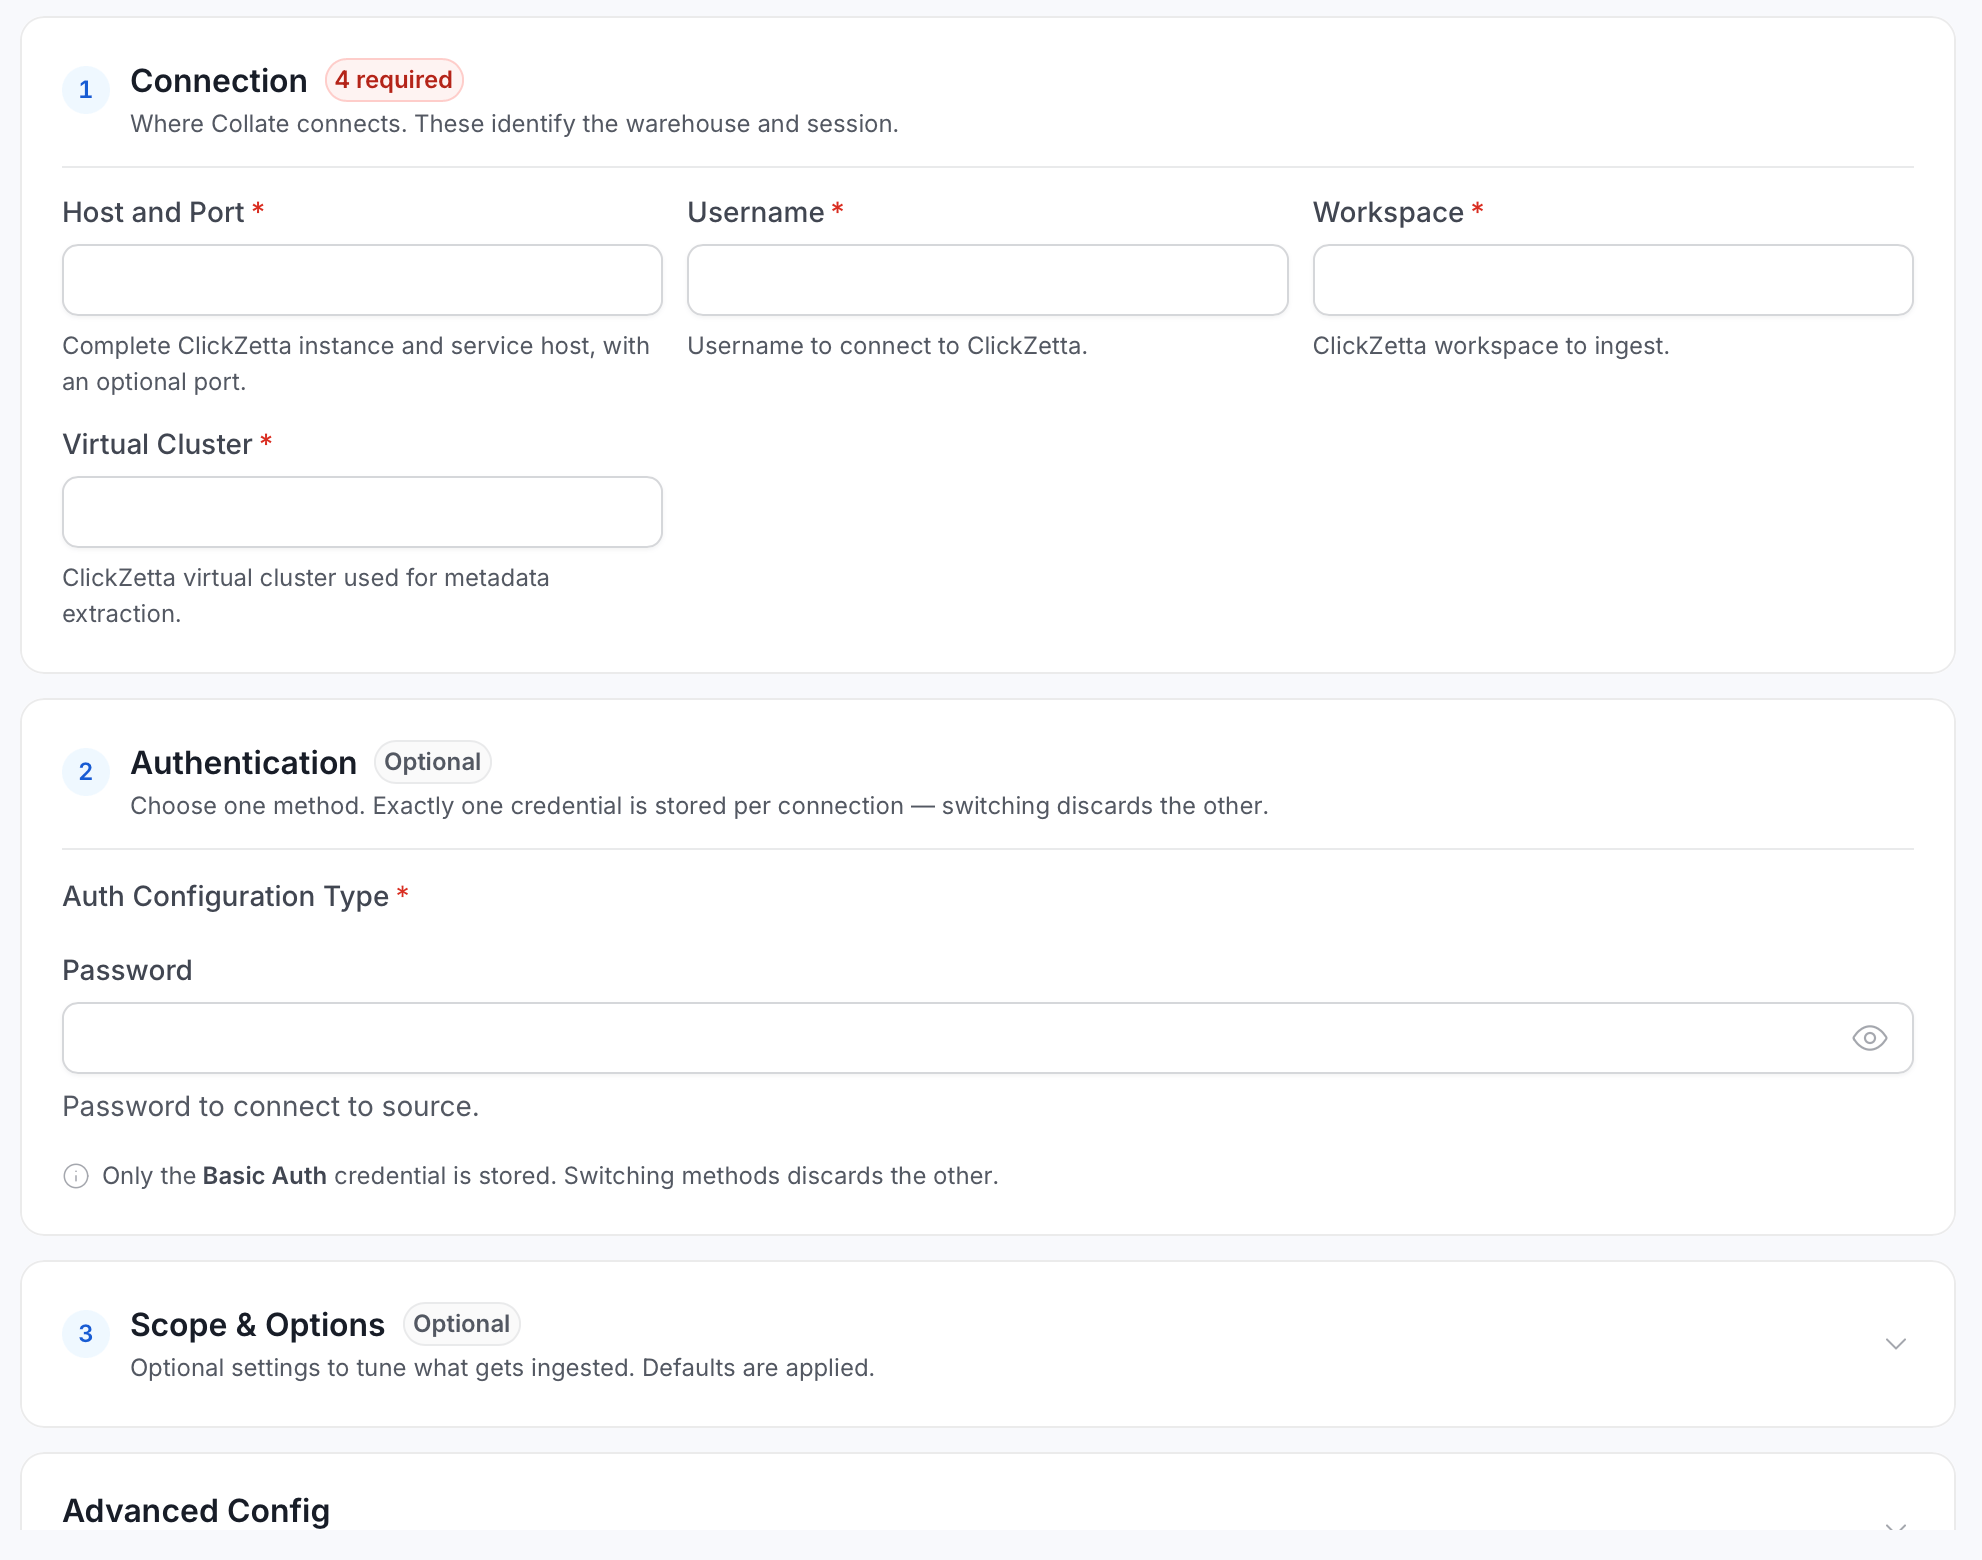
Enter the connection details for ClickZetta. The inline help panel in the UI describes each field.

<img src="https://mintcdn.com/openmetadata/tzk3NBXjCi0JT4fO/public/images/connector2.0/metadata-ingestion/Database/connection-details/clickzetta.png?fit=max&auto=format&n=tzk3NBXjCi0JT4fO&q=85&s=bf8d78ee4a9143cc578298c9345227ce" alt="Configure Service Connection" width="1982" height="1560" data-path="public/images/connector2.0/metadata-ingestion/Database/connection-details/clickzetta.png" />

* **Host and Port**: Complete ClickZetta instance and service host, with an optional port (for example, `your-instance.clickzetta.com` or `your-instance.clickzetta.com:8443`).
* **Username**: Username to connect to ClickZetta. It should have enough privileges to read all the metadata.
* **Workspace**: The ClickZetta workspace to ingest.
* **Virtual Cluster**: The ClickZetta virtual cluster used to run the metadata extraction queries.
* **Password**: Password to connect to ClickZetta.
* **Database Schema**: Optional schema restriction. When left blank, OpenMetadata attempts to scan all schemas.
* **Query History Table**: ClickZetta table or view used for usage and query-lineage extraction. It's required for the Query Usage and Lineage agents, which fail if it's unset. Set this to `information_schema.job_history` for workspace-local native history. Use `sys.information_schema.job_history` for cross-workspace native history. The connector maps the native columns from either source and scopes them to the configured workspace and schema. Custom tables or views must expose the following columns:
  * Query columns: `query_text`, `query_type`, `user_name`
  * Scope and timing columns: `database_name`, `schema_name`, `start_time`, `end_time`, `duration`, `aborted`, `cost`
* **Protocol**: Protocol used to connect to ClickZetta. Choose `https` (default) or `http`.

#### Test Connection

After you add the credentials, click **Test Connection**, then click **Save**.
<img src="https://mintcdn.com/openmetadata/9G75p72jJKYgvFUQ/public/images/connectors/test-connection.png?fit=max&auto=format&n=9G75p72jJKYgvFUQ&q=85&s=4ac71a56e30fa3dd1be86f82c1f07068" alt="Test Connection" width="1494" height="310" data-path="public/images/connectors/test-connection.png" />

### Step 5: Configure Ingestion Options

In the **What to Ingest** step, configure filter rules for databases, schemas, and tables.

#### How Filter Rules Work

Each rule matches asset names using one of five match types:

* **Contains**: Matches any name containing the value. For example, `sales` matches `my_sales_data` and `sales_2024`.
* **Starts with**: Matches names beginning with the value. For example, `prod_` matches `prod_db` and `prod_schema`.
* **Ends with**: Matches names ending with the value. For example, `_raw` matches `events_raw` and `logs_raw`.
* **Is exactly**: Matches the exact name only. For example, `analytics` matches only `analytics`.
* **Matches regex**: Matches names using a regular expression. For example, `^prod_.*_v\d+$` matches `prod_events_v1`.

When include rules and exclude rules both match an asset, the exclude rule takes priority.
<Tip>
  Leave all filter rules empty to ingest all databases, schemas, and tables available in the source.
</Tip>

#### Filter Options

The **Database**, **Schema**, and **Table** sections control ingestion for the corresponding asset type. Each section provides the following controls:

* **Scan Mode**: Choose one of the following scan modes:
  * **Scan all**: Ingests every asset of that type the connector can access. This is the default.
  * **Only specific**: Enables include rules so only assets matching at least one rule are ingested.
* **Exclude system toggle**: Use this toggle to automatically filter out system-reserved names defined by the connector, for example, **Exclude system databases** for the Databases section.
* **Always exclude**: Add permanent exclusion rules (shown in red). OpenMetadata never ingests assets matching these rules, regardless of include rules.
* **Preview**: View a real-time summary of what's in scope based on your current rules.
* **Include rules**: In **Only specific** mode, click **+ Add** to define a rule. Added rules appear as chips. OpenMetadata includes an asset if it matches any rule.

### Step 6: Create & Deploy

Click **Create & Deploy** to deploy the agent and start the first metadata ingestion run. OpenMetadata saves the service configuration and immediately begins pulling metadata from the source.

To monitor ingestion progress or view the service you just added, go to **Settings** > **Services** and select your service.

## Configure Metadata Agent and Schedule Ingestion

The **Metadata Agent** extracts schemas, tables, columns, and other structural metadata from your source and keeps your OpenMetadata catalog in sync. It powers discovery, lineage, and governance across your data assets.

When you click **Create & Deploy**, OpenMetadata automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the **Agents** tab on the service detail page.

To configure the additional Metadata Agent and schedule ingestion, follow these steps:

1. Navigate to **Settings** > **Services** and select the service type.

   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/access-service-type.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=4471655da6e39d91776597e4a7eea513" alt="Navigate to Settings and Services" width="2992" height="1612" data-path="public/images/connector2.0/metadata-ingestion/access-service-type.png" />

2. Click the service you have added.

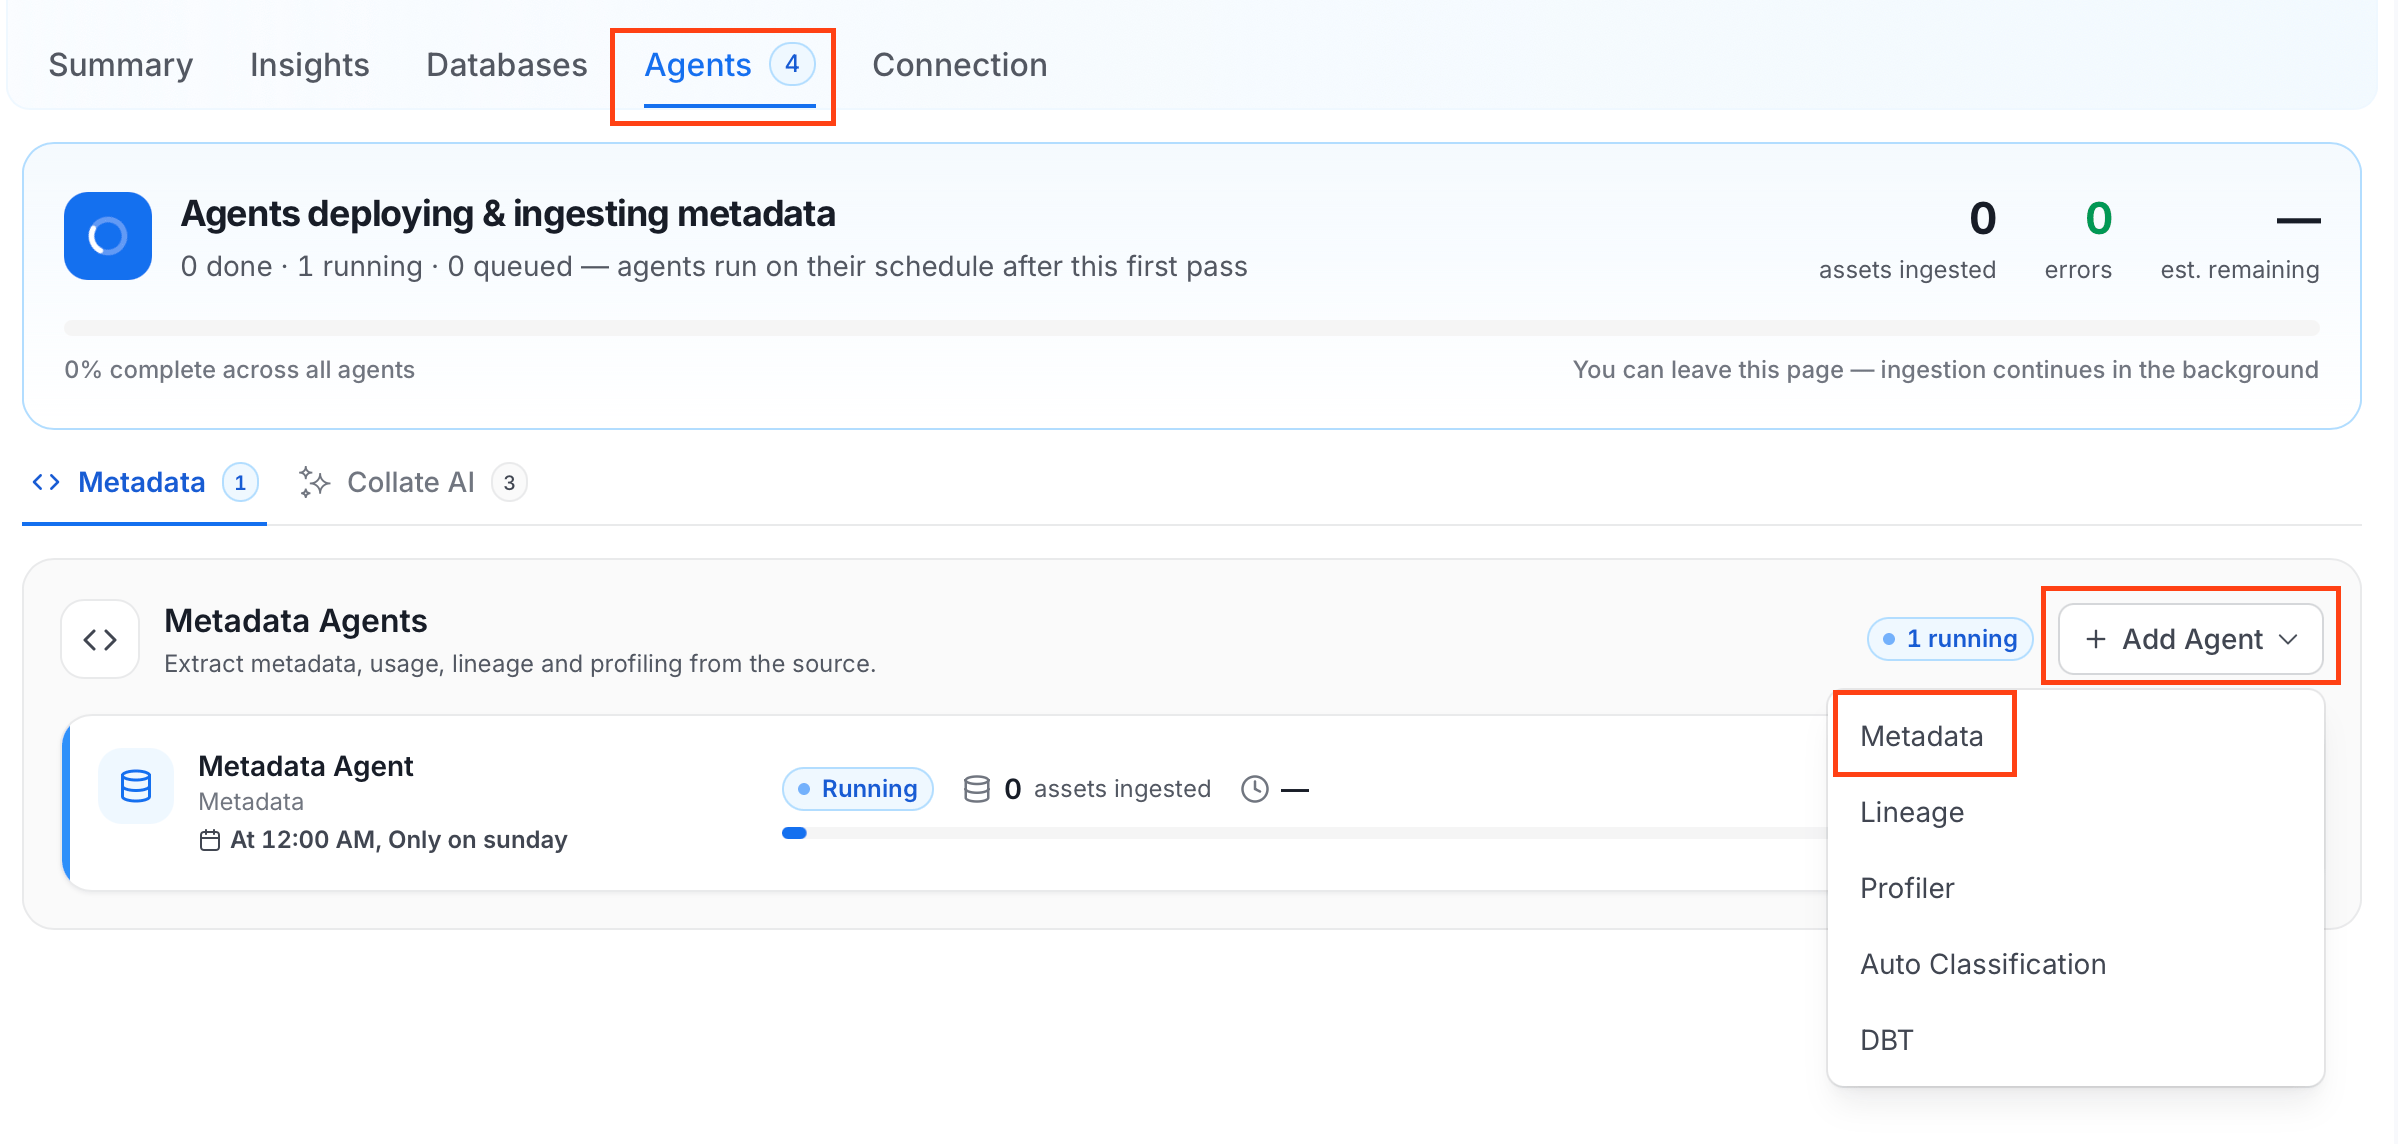
3. Select the **Agents** tab and click **Add Agent** > **Metadata**.
   <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/add-metadata-agent.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=a654d9700126ce64cb6c9a99b8d69b1a" alt="Add Metadata Agent" width="2398" height="1144" data-path="public/images/connector2.0/metadata-ingestion/add-metadata-agent.png" />

   For some services, the dropdown is not available and clicking **Add Agent** takes you directly to the agent configuration page.

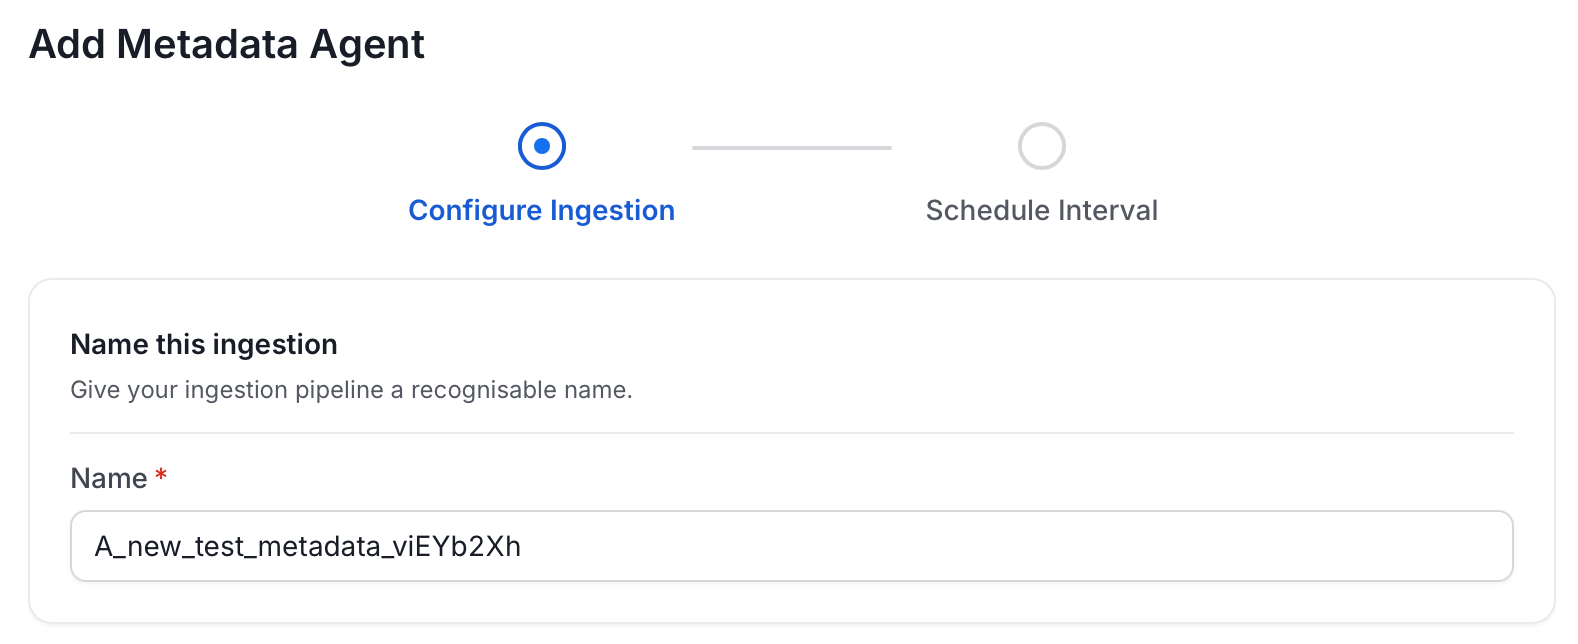
4. On the **Configure Ingestion** page, do the following and click **Next**.

   * **Name this Ingestion**: Enter a unique recognizable name for this ingestion pipeline.
     <img src="https://mintcdn.com/openmetadata/pD1dbe0lKPSqnODv/public/images/connector2.0/metadata-ingestion/metadata-agent-name.png?fit=max&auto=format&n=pD1dbe0lKPSqnODv&q=85&s=92954c166518e3ac07589ab20865e3e7" alt="Name this Ingestion" width="1578" height="644" data-path="public/images/connector2.0/metadata-ingestion/metadata-agent-name.png" />

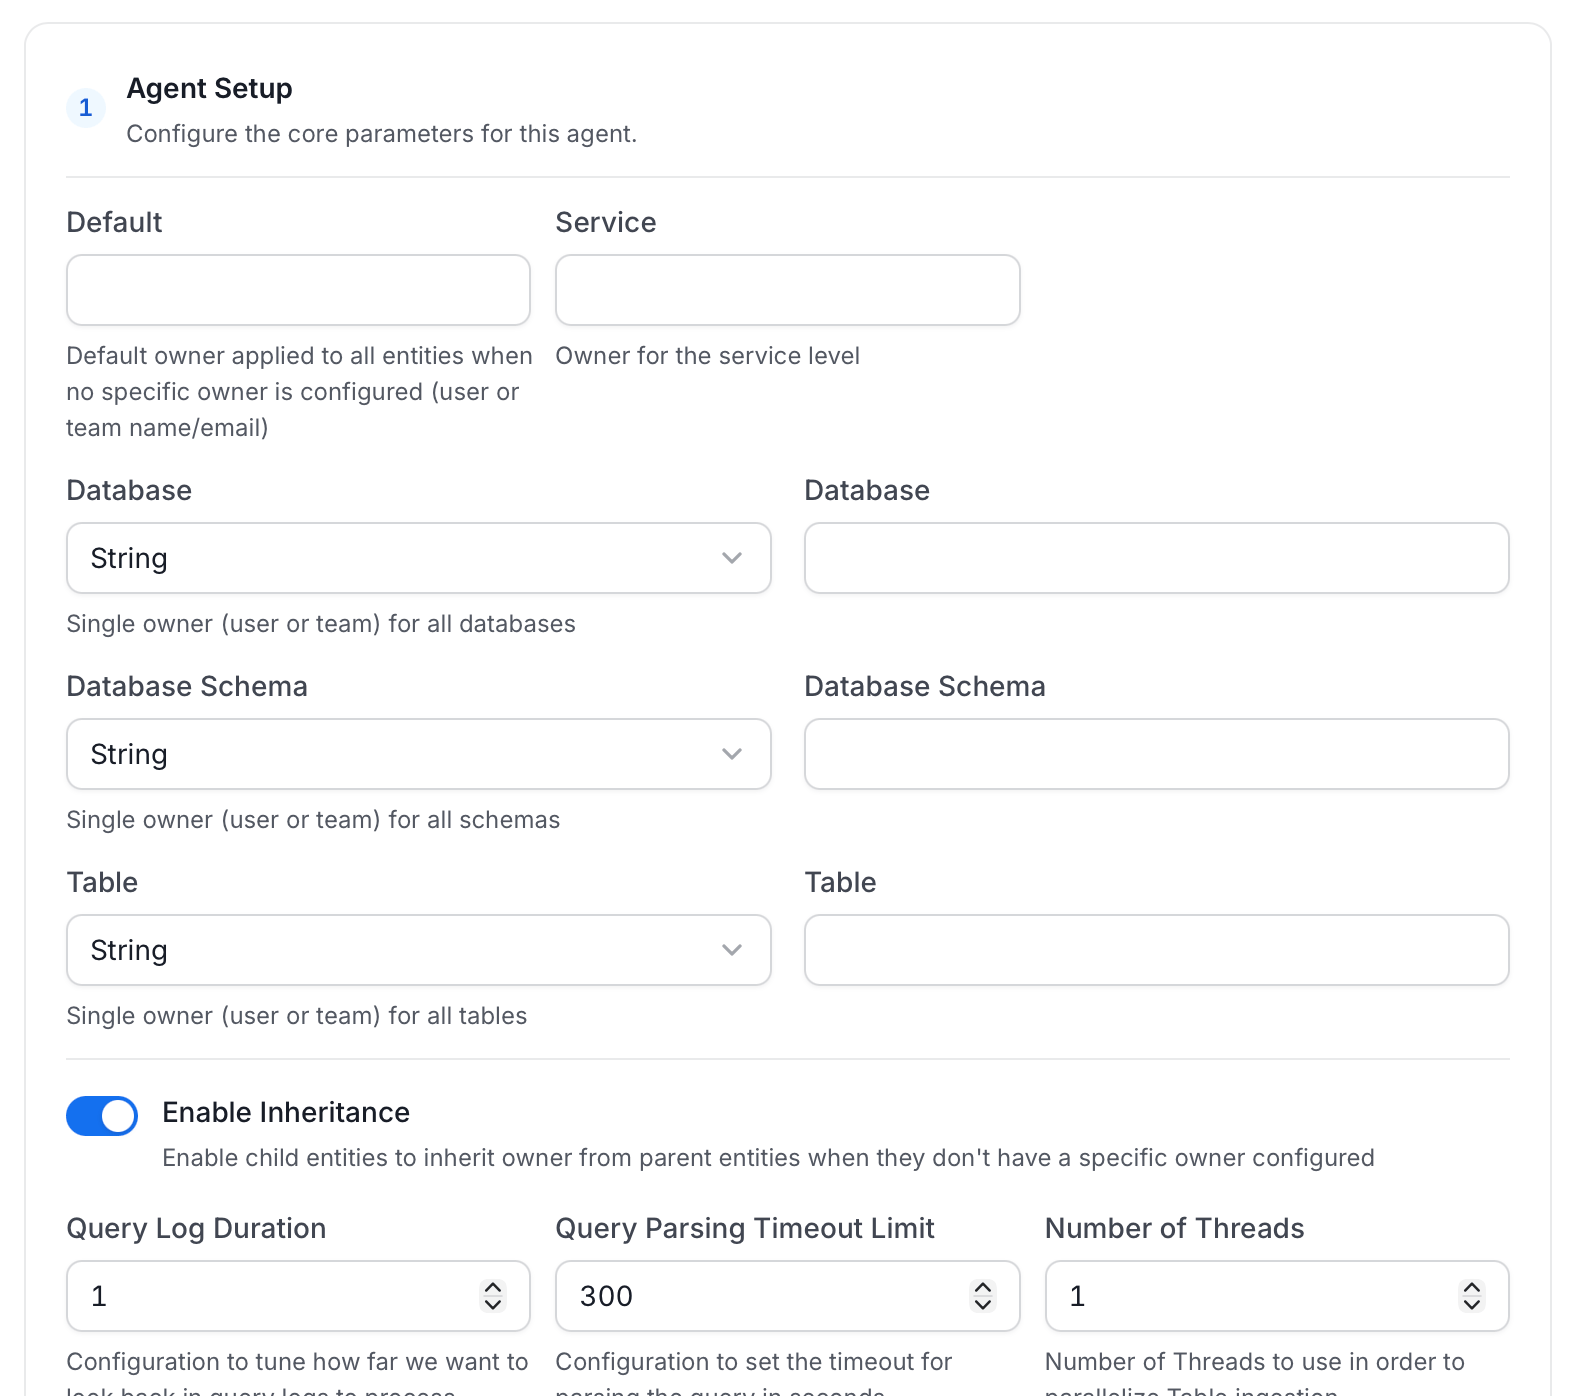
   * **Agent Setup**: Configure core parameters for metadata extraction. The following fields are available:

     | Field | Default | Description |
     | - | - | - |
     | **Default Owner** | — | Owner applied to any entity that has no owner from a more specific field below. Accepts a user or a team, by name or email. |
     | **Service Owner** | — | Owner assigned to the service entity itself (the connector/service you're setting up, not the data inside it). |
     | **Database Owner** | — | Owner assigned to every database this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per database. |
     | **Database Schema Owner** | — | Owner assigned to every schema this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per schema. |
     | **Table Owner** | — | Owner assigned to every table this agent ingests. Accepts either one owner for all of them, or a mapping of specific owners per table. |
     | **Enable Inheritance** | On | When on, an entity with no owner of its own inherits one from the nearest parent that has one, checked in this order: table, then schema, then database, then service, then Default Owner. Turn off if you want only the owners set explicitly above to apply, with no fallback. |
     | **Query Log Duration** | 1 | How many days of query logs to look back through when processing stored procedure results. |
     | **Query Parsing Timeout Limit** | 300 | How many seconds to spend parsing a single query before giving up on it and moving to the next. Raise this if large or complex queries are being skipped. |
     | **Number of Threads** | 1 | How many tables to ingest in parallel. Raising this can speed up ingestion on databases with many tables, at the cost of more load on the source. |
     | **Incremental Extraction** | Off | When on, a run extracts only entities that changed since the last successful run, instead of re-scanning everything every time. Faster on large, mostly unchanged databases. |
     | **Successful Pipeline Run Lookback Days** | 7 | Only used when Incremental Extraction is on. How many days back to search for a prior successful run to use as the starting point for what changed since then. |
     | **Safety Margin Days** | 1 | Only used when Incremental Extraction is on. Extra days added before that starting point, as a buffer so changes still in flight when the last run finished aren't missed. |
     | **Extract JSON Schema** | Off | Sample values in JSON columns to infer and ingest their schema, so the individual fields inside a JSON column are visible in OpenMetadata rather than just "JSON". Requires `SELECT` permission on the sampled tables. If that permission is missing, the JSON column is still ingested, just without a detailed schema. |
     | **JSON Schema Sample Size** | 10 | Only used when Extract JSON Schema is on. Number of rows sampled per JSON column to infer its schema. A larger sample gives more accurate results but takes longer to run. |

     For more information about how the Default Owner, Service Owner, Database Owner, Database Schema Owner, Table Owner, and Enable Inheritance fields resolve an owner, see [Hierarchical Owner Configuration](/connectors/ingestion/workflows/metadata/hierarchical-owner-configuration).
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-agent-setup.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=d0b1251c1b9aacd64c95278645f89127" alt="Agent Setup" width="1570" height="1396" data-path="public/images/connector2.0/metadata-ingestion/Database/database-agent-setup.png" />

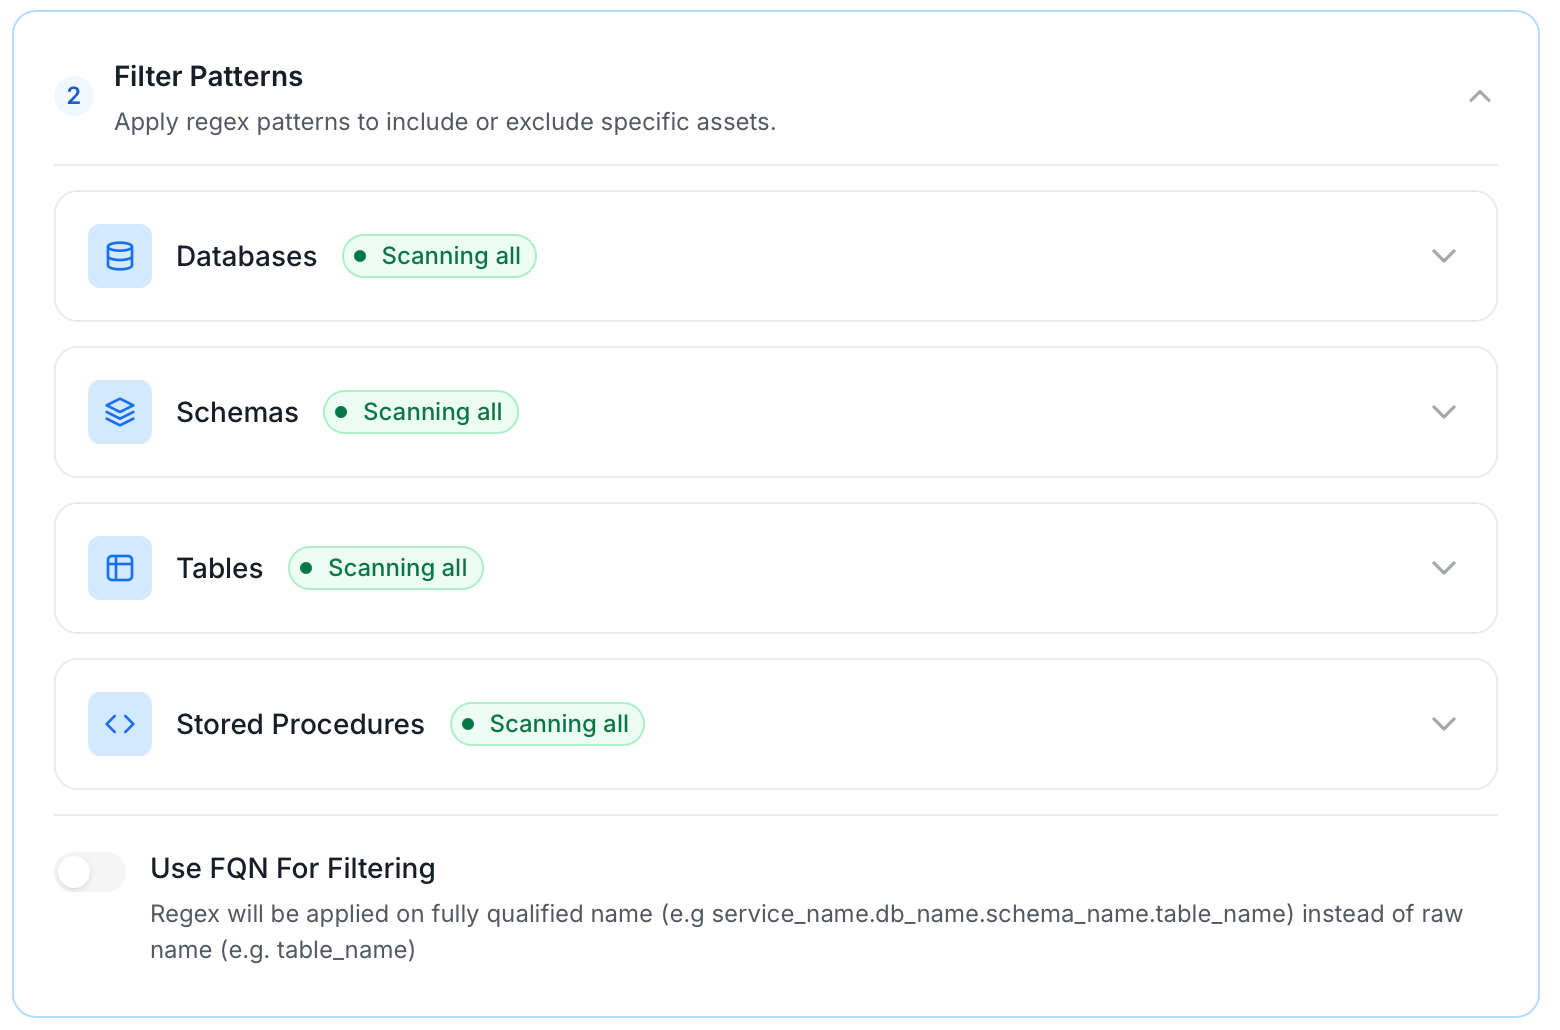
   * **Filter Patterns**: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. For more information about various filter options, see **Step 6: Configure Ingestion Options**.
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-filter-pattern.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=cc4693554363e81232fde8c3fb602e25" alt="Filter Patterns" width="1560" height="1030" data-path="public/images/connector2.0/metadata-ingestion/Database/database-filter-pattern.png" />

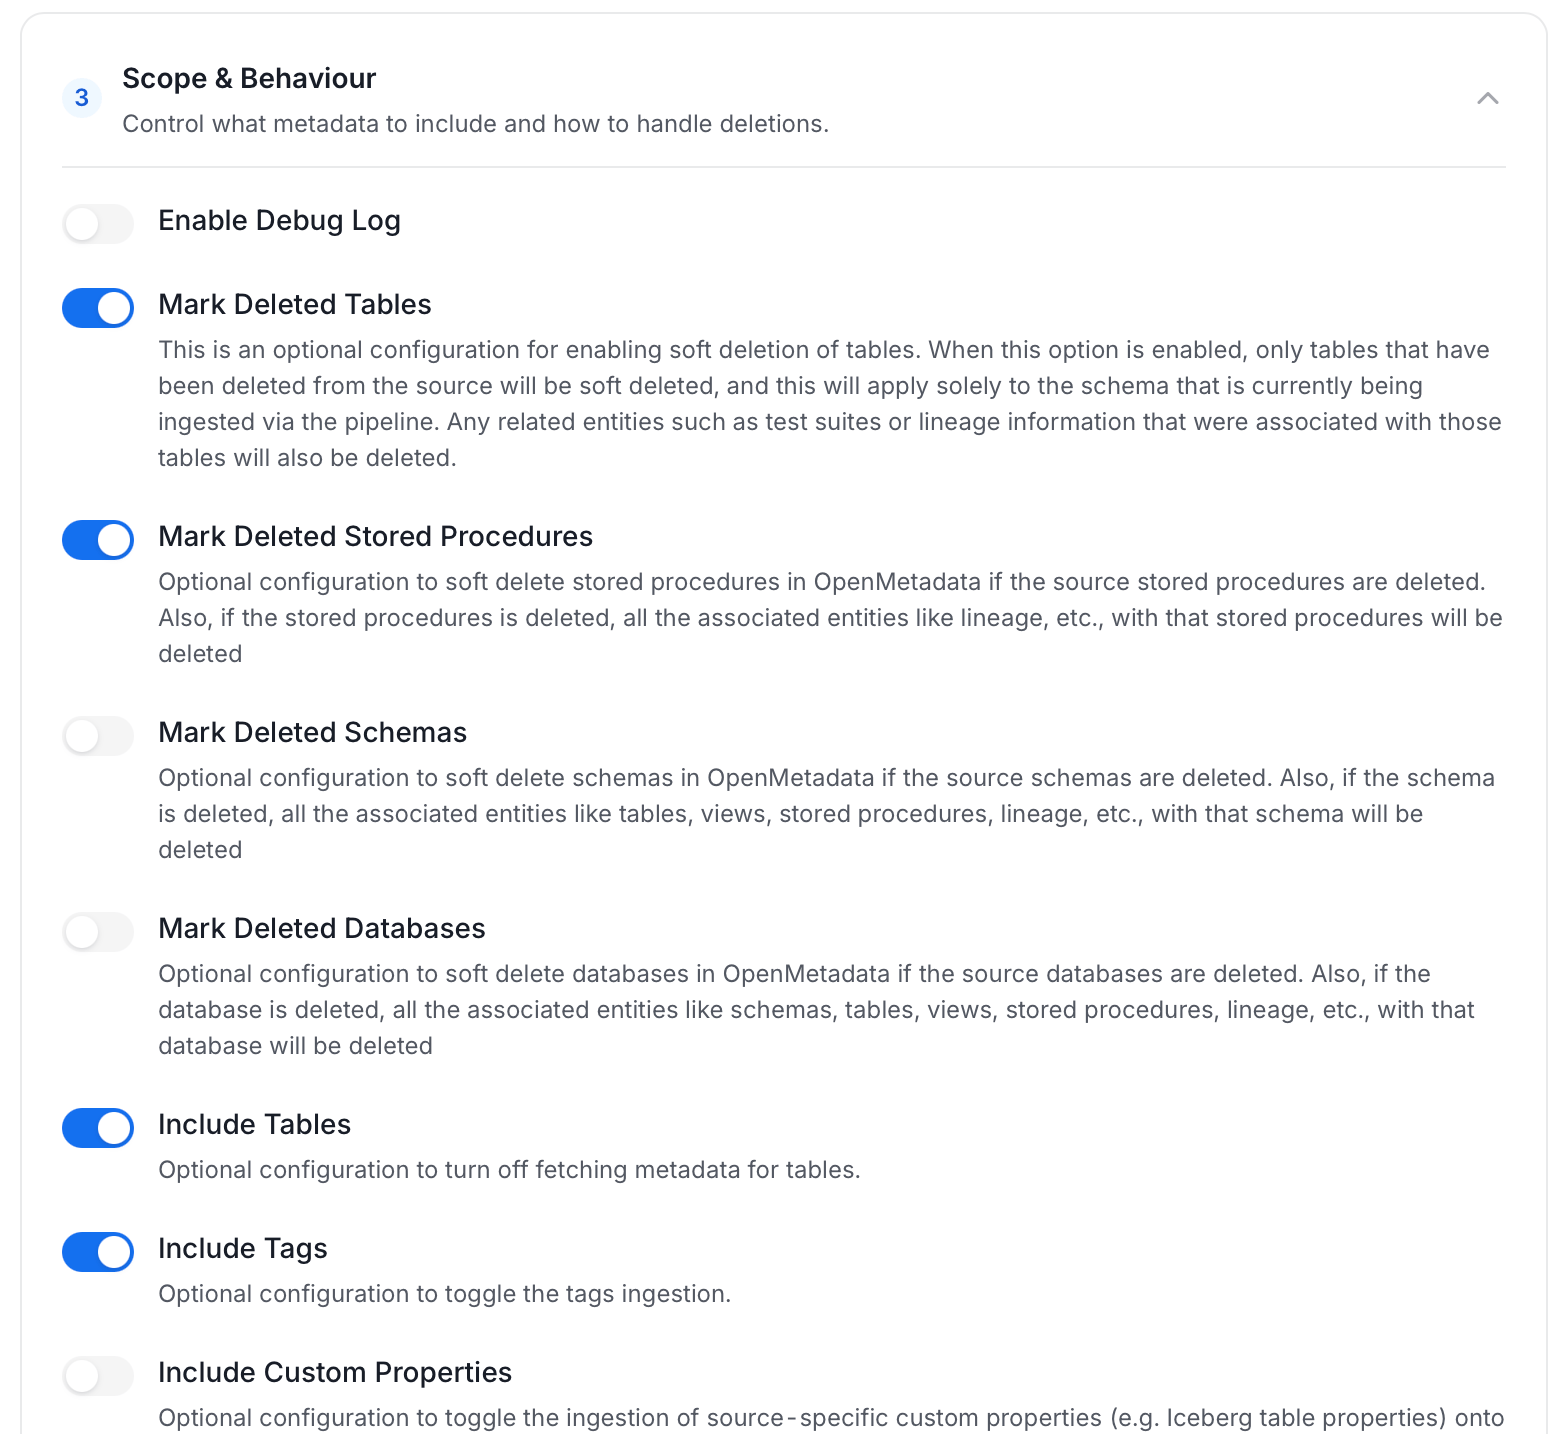
   * **Scope & Behaviour**: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:

     | Toggle | Default | Description |
     | - | - | - |
     | **Include Tables** | On | Ingest tables and their columns. Turn off to skip tables entirely, for example if this agent exists only to pull tags or stored procedures. |
     | **Include Tags** | On | Ingest tags already defined on tables/columns in the source system (for example, a classification tag applied in Snowflake) and bring them into OpenMetadata as tags on the same assets. |
     | **Include Stored Procedures** | On | Ingest stored procedures as their own assets, so they show up in the catalog and can be linked into lineage. |
     | **Include DDL Statements** | Off | Also ingest the raw `CREATE TABLE` / `CREATE VIEW` statement for each asset, so it's viewable in OpenMetadata alongside the asset's metadata. |
     | **Include Owners** | Off | When an ingested asset's owner in the source system is an email that matches an existing OpenMetadata user, assign that user as the asset's owner. Never overwrites an owner an asset already has in OpenMetadata. |
     | **Include Custom Properties** | Off | Ingest source-specific metadata that doesn't map to a standard OpenMetadata field (for example, a database-specific attribute) into custom properties on the asset, if custom properties have been defined for that entity type. |
     | **Mark Deleted Tables** | On | If a table this agent previously ingested no longer exists in the source, soft-delete it in OpenMetadata too. Only affects tables within schemas this agent actually scans. |
     | **Mark Deleted Stored Procedures** | On | Same as Mark Deleted Tables, but for stored procedures. |
     | **Mark Deleted Schemas** | Off | If an entire schema this agent previously ingested no longer exists in the source, soft-delete the schema and everything in it. |
     | **Mark Deleted Databases** | Off | If an entire database this agent previously ingested no longer exists in the source, soft-delete the database and everything in it. |
     | **Override Metadata** | Off | On: values from the source (descriptions, tags, owners, display names) always overwrite what's currently in OpenMetadata, even if someone edited it there. Off: OpenMetadata only fills in fields that are still empty, so manual edits in OpenMetadata are preserved. |
     | **Enable Debug Log** | Off | Run this ingestion at DEBUG log verbosity instead of the normal level. Turn on when troubleshooting a failing or unexpected run. Leave off otherwise, since debug logs are much larger. |
     <Note>
       Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
     </Note>

     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-scope-behaviour.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=03b790d0d7ce6a5f75f46002b06dcc05" alt="Scope & Behaviour" width="1566" height="1436" data-path="public/images/connector2.0/metadata-ingestion/Database/database-scope-behaviour.png" />

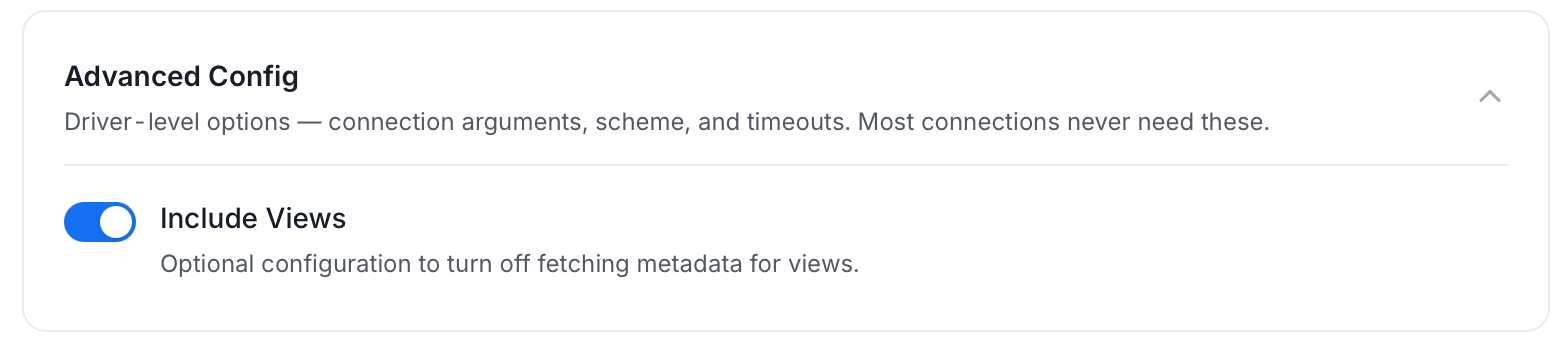
   * **Advanced Config**: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:

     | Toggle | Default | Description |
     | - | - | - |
     | **Include Views** | On | Ingest views in addition to tables. Turn off to skip views entirely. Since view lineage is derived from parsing each view's SQL definition, turning this off also stops view-based lineage from being generated for this service. |
     <img src="https://mintcdn.com/openmetadata/oUGf8BeSz2Uo7tlL/public/images/connector2.0/metadata-ingestion/Database/database-advance.png?fit=max&auto=format&n=oUGf8BeSz2Uo7tlL&q=85&s=70399f49ea960130062a9cd3c91a1840" alt="Advanced Config" width="1564" height="352" data-path="public/images/connector2.0/metadata-ingestion/Database/database-advance.png" />

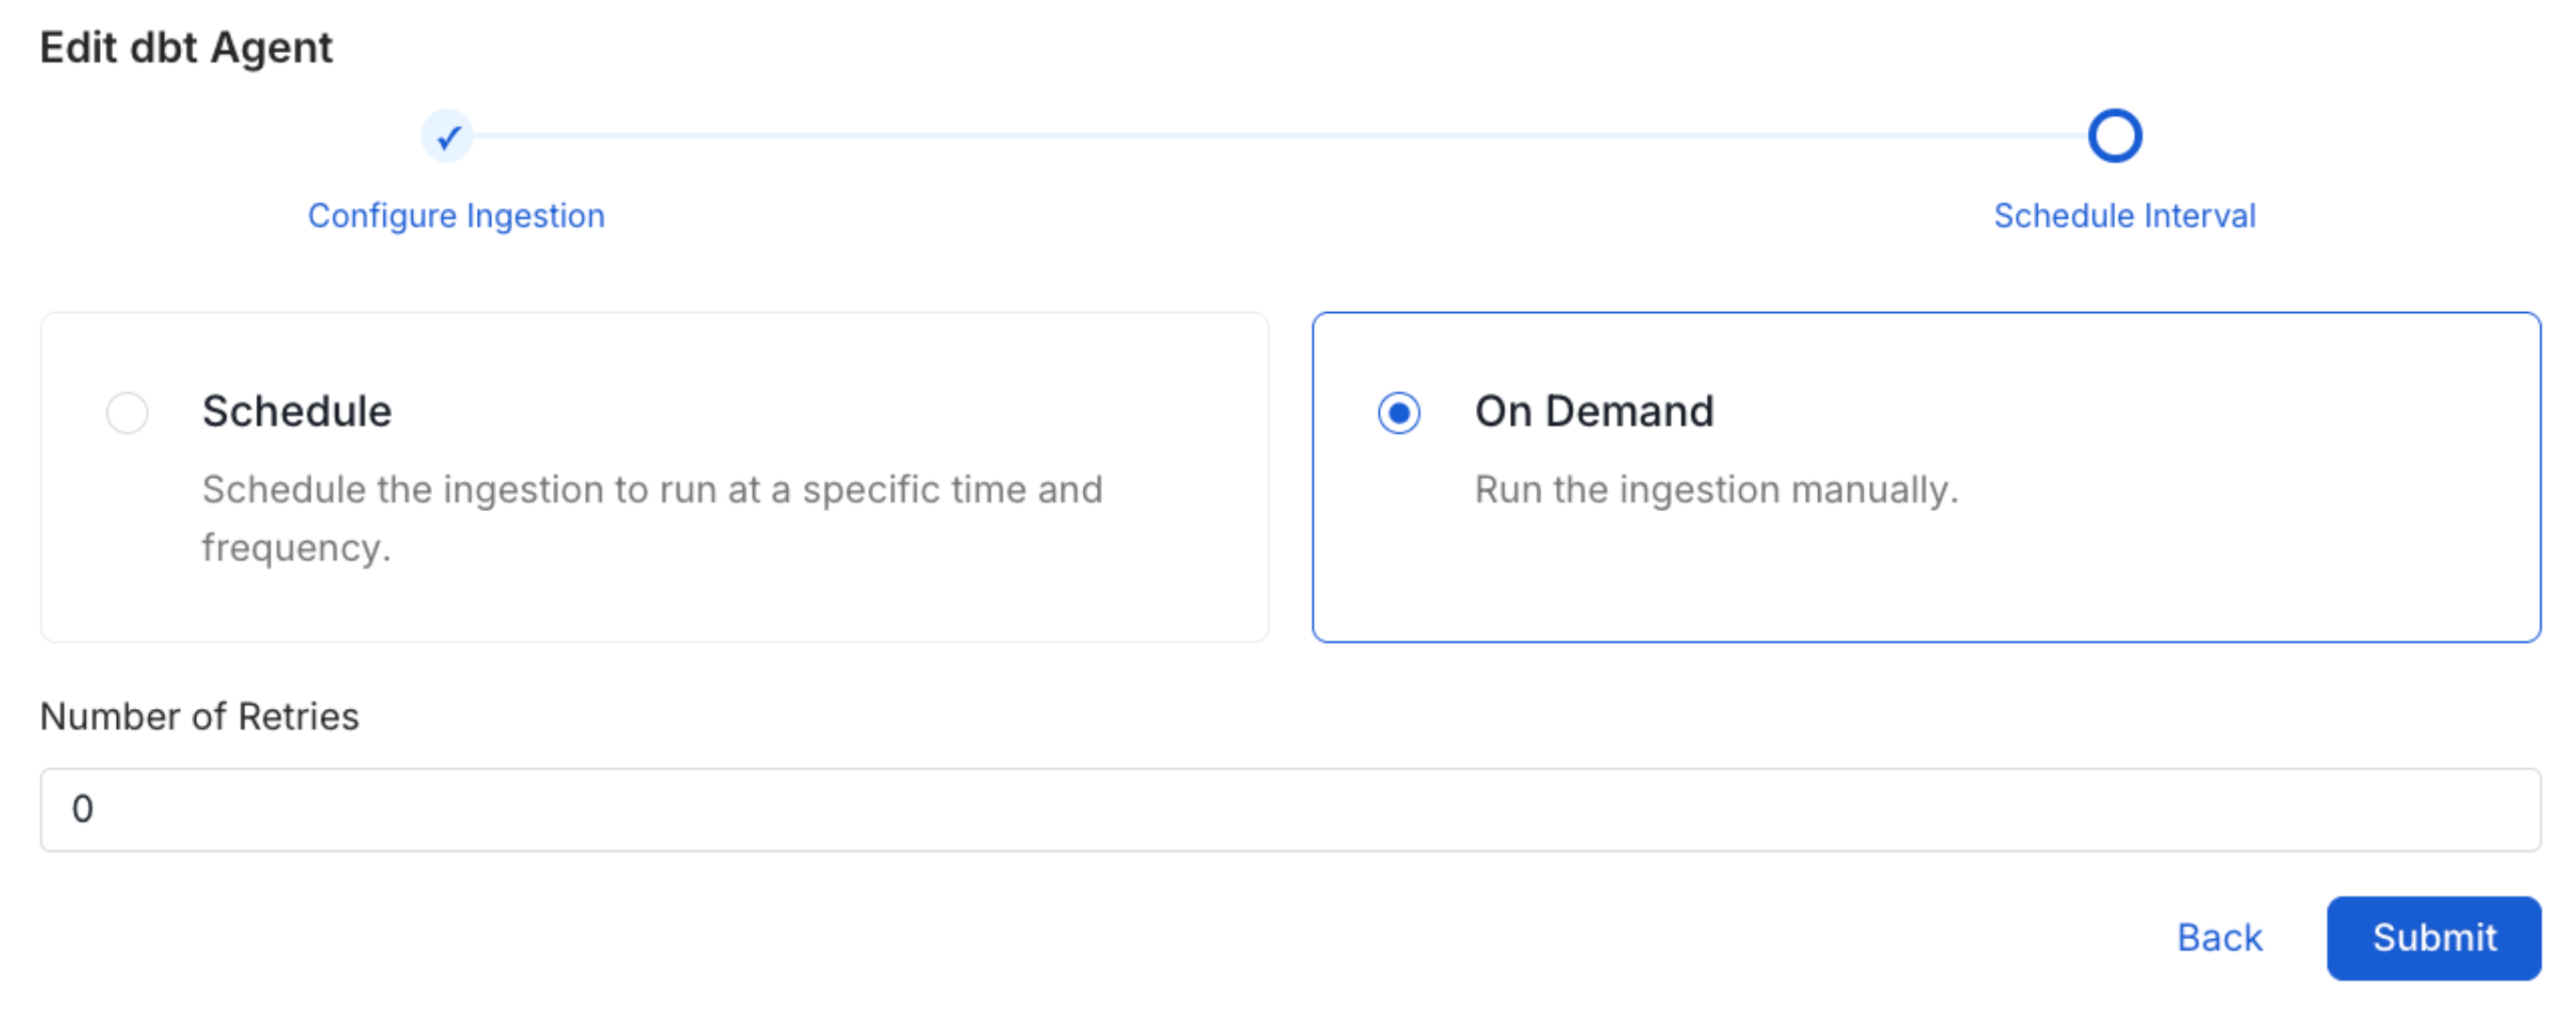
5. On the **Schedule Interval** page, set when the agent runs:

   * **Schedule**: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
   * **On-Demand**: No automatic schedule; trigger the agent manually when needed.
   <img src="https://mintcdn.com/openmetadata/j50Bw6ZBiFbbFFnF/public/images/connectors/schedule.png?fit=max&auto=format&n=j50Bw6ZBiFbbFFnF&q=85&s=24b0c2f55f803efde5fb3b3bc24ed3ae" alt="Schedule Interval" width="2733" height="1083" data-path="public/images/connectors/schedule.png" />

6. Click **Add** to deploy the agent.

## Related

<Columns cols={2}>
  <Card title="Usage Workflow" href="/v2.1.x-SNAPSHOT/connectors/ingestion/workflows/usage">
    Learn more about how to configure the Usage Workflow to ingest Query information from the UI.
  </Card>

  <Card title="Lineage Workflow" href="/v2.1.x-SNAPSHOT/connectors/ingestion/workflows/lineage">
    Learn more about how to configure the Lineage from the UI.
  </Card>

  <Card title="Profiler Workflow" href="/v2.1.x-SNAPSHOT/how-to-guides/data-quality-observability/profiler/profiler-workflow">
    Learn more about how to configure the Data Profiler from the UI.
  </Card>

  <Card title="Data Quality Workflow" href="/v2.1.x-SNAPSHOT/how-to-guides/data-quality-observability/quality/configure">
    Learn more about how to configure the Data Quality tests from the UI.
  </Card>

  <Card title="dbt Integration" href="/v2.1.x-SNAPSHOT/connectors/database/dbt">
    Learn more about how to ingest dbt models' definitions and their lineage.
  </Card>
</Columns>


This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.