
- Requirements
- How Glue Maps to OpenMetadata
- Iceberg Table Support
- Metadata Ingestion
- dbt Integration
- Troubleshooting
Requirements
The connector reads metadata from the AWS Glue Data Catalog through the AWS Glue API. Grant the following AWS Identity and Access Management (IAM) permissions to the AWS identity that the connector uses:glue:GetDatabases: Lists the Glue databases in the catalog.glue:GetTables: Lists the tables and views in each Glue database.glue:GetTable: Reads the column details of each Iceberg table. For more information, see Iceberg Table Support.
<AWS_REGION> and <ACCOUNT_ID> with your values.
DESCRIBE permission on the databases and tables to ingest. Without that grant, Glue leaves those databases and tables out of its responses instead of returning an error.
How Glue Maps to OpenMetadata
The connector doesn’t map a Glue database to an OpenMetadata database. The Glue Data Catalog becomes the OpenMetadata database, and each Glue database becomes a schema inside it.
Database Name does more than rename the database. When you set it:
- The connector creates one database with that name and stops using the Database to select catalogs, so leave that filter empty.
- Every Glue database the connector can see becomes a schema of that database, even when the Glue databases come from different catalogs. The ingestion run reports a warning when it sees more than one catalog.
- If two Glue databases from different catalogs share a name, one overwrites the other and its tables go missing.
Filter Patterns
Each filter in Step 5: Configure Ingestion Options matches the Glue name at its own level of this mapping. The following examples use include rules:
To choose which Glue databases to ingest, use the Schema filter. Use the Database filter only to limit ingestion to specific catalog IDs.
If you turn on Use FQN For Filtering, rules match the fully qualified name instead. For example, the Glue database
sales_raw in the catalog 123456789012 of a service named glue_prod has the fully qualified name glue_prod.123456789012.sales_raw.
Iceberg Table Support
The connector ingests Apache Iceberg tables registered in the Glue Data Catalog. It reads only catalog metadata through the AWS Glue API, so it doesn’t need access to the table’s data or metadata files in Amazon S3.How Iceberg Tables Are Detected
The connector treats a Glue table as an Iceberg table when itstable_type table parameter is ICEBERG. Iceberg tables registered in the Glue Data Catalog carry this parameter. OpenMetadata shows these tables with the Iceberg table type.
Current Columns Only
When an Iceberg table’s schema changes, Iceberg keeps the columns from earlier schema versions in the Glue table definition and sets theiriceberg.field.current column parameter to false. For each Iceberg table, the connector calls glue:GetTable to read these column parameters and skips the non-current columns, so OpenMetadata shows only the table’s current columns.
Limitations
- If the
glue:GetTablecall fails, for example because the permission is missing, the connector logs a warning and uses the columns fromglue:GetTablesinstead. Those columns can include non-current ones, and the ingestion run still reports success. - The
table_typecheck is case-sensitive. The connector ingests a table whose parameter isn’t exactlyICEBERGas a regular or external table. - The connector doesn’t read Iceberg metadata files, so it doesn’t ingest snapshots or partition specs.
Metadata Ingestion
To ingest metadata from Glue, you need to create a service connection. The service connects Glue with OpenMetadata. Once you create a service, OpenMetadata automatically starts ingesting metadata.Step 1: Add New Service
-
Navigate to Settings > Services.
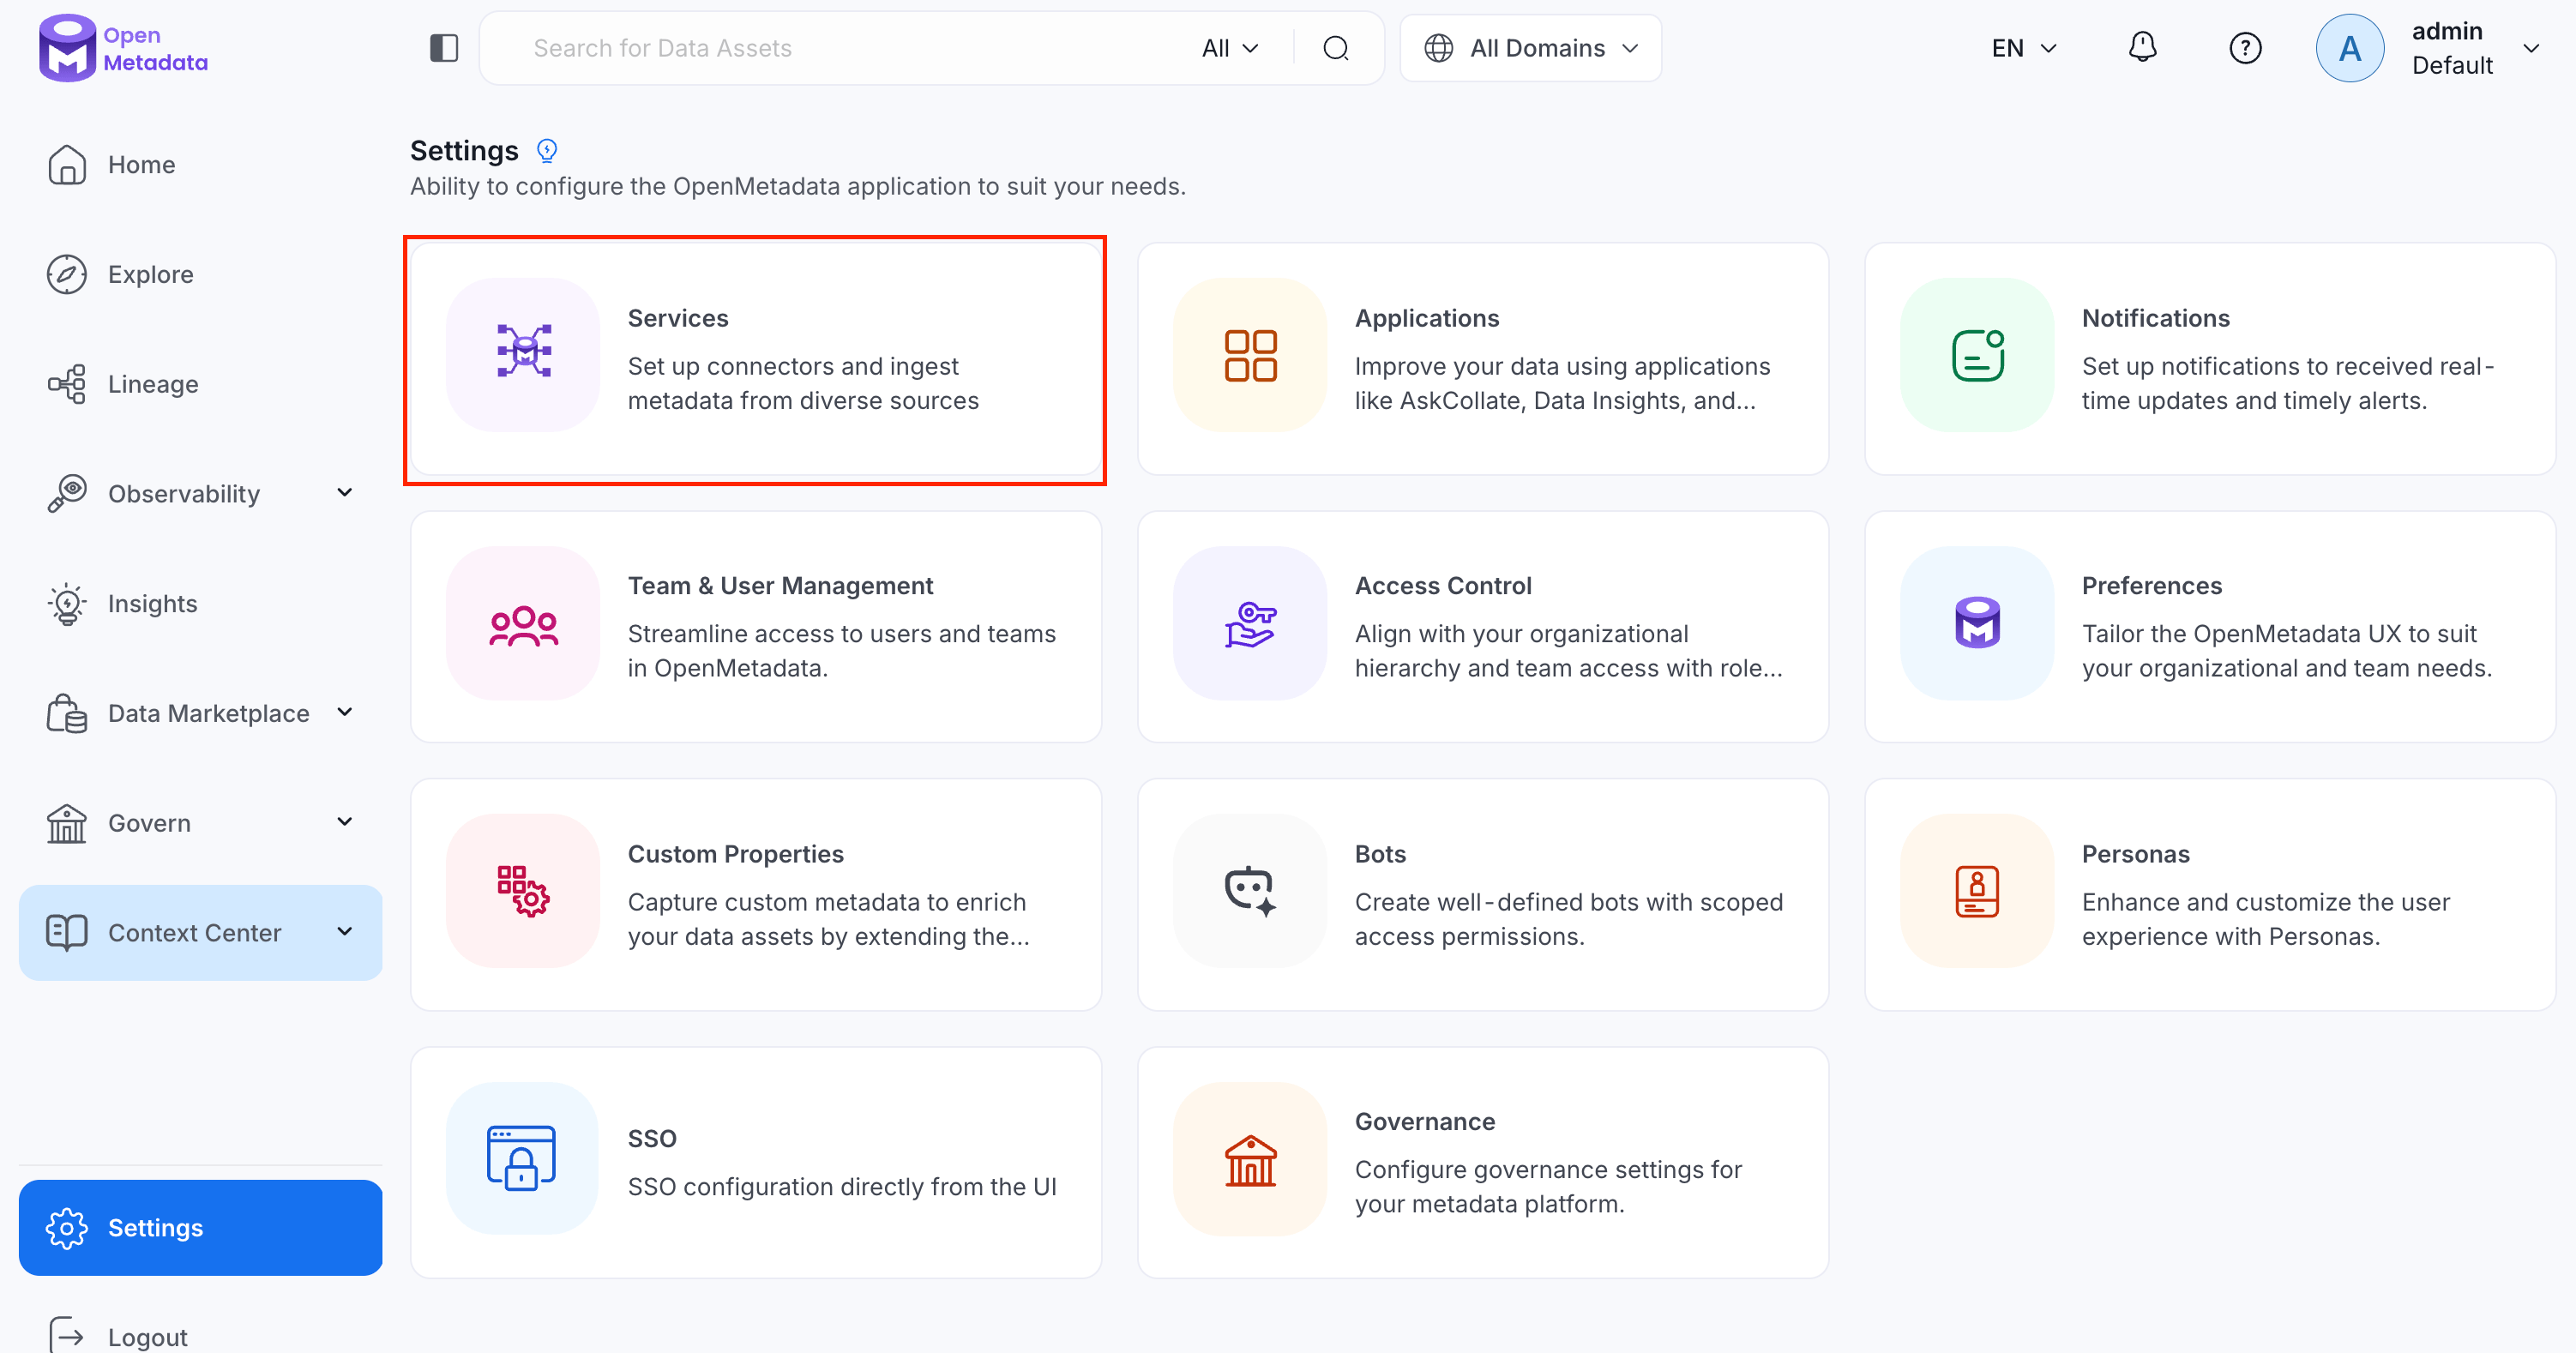
-
Click Add New Service.
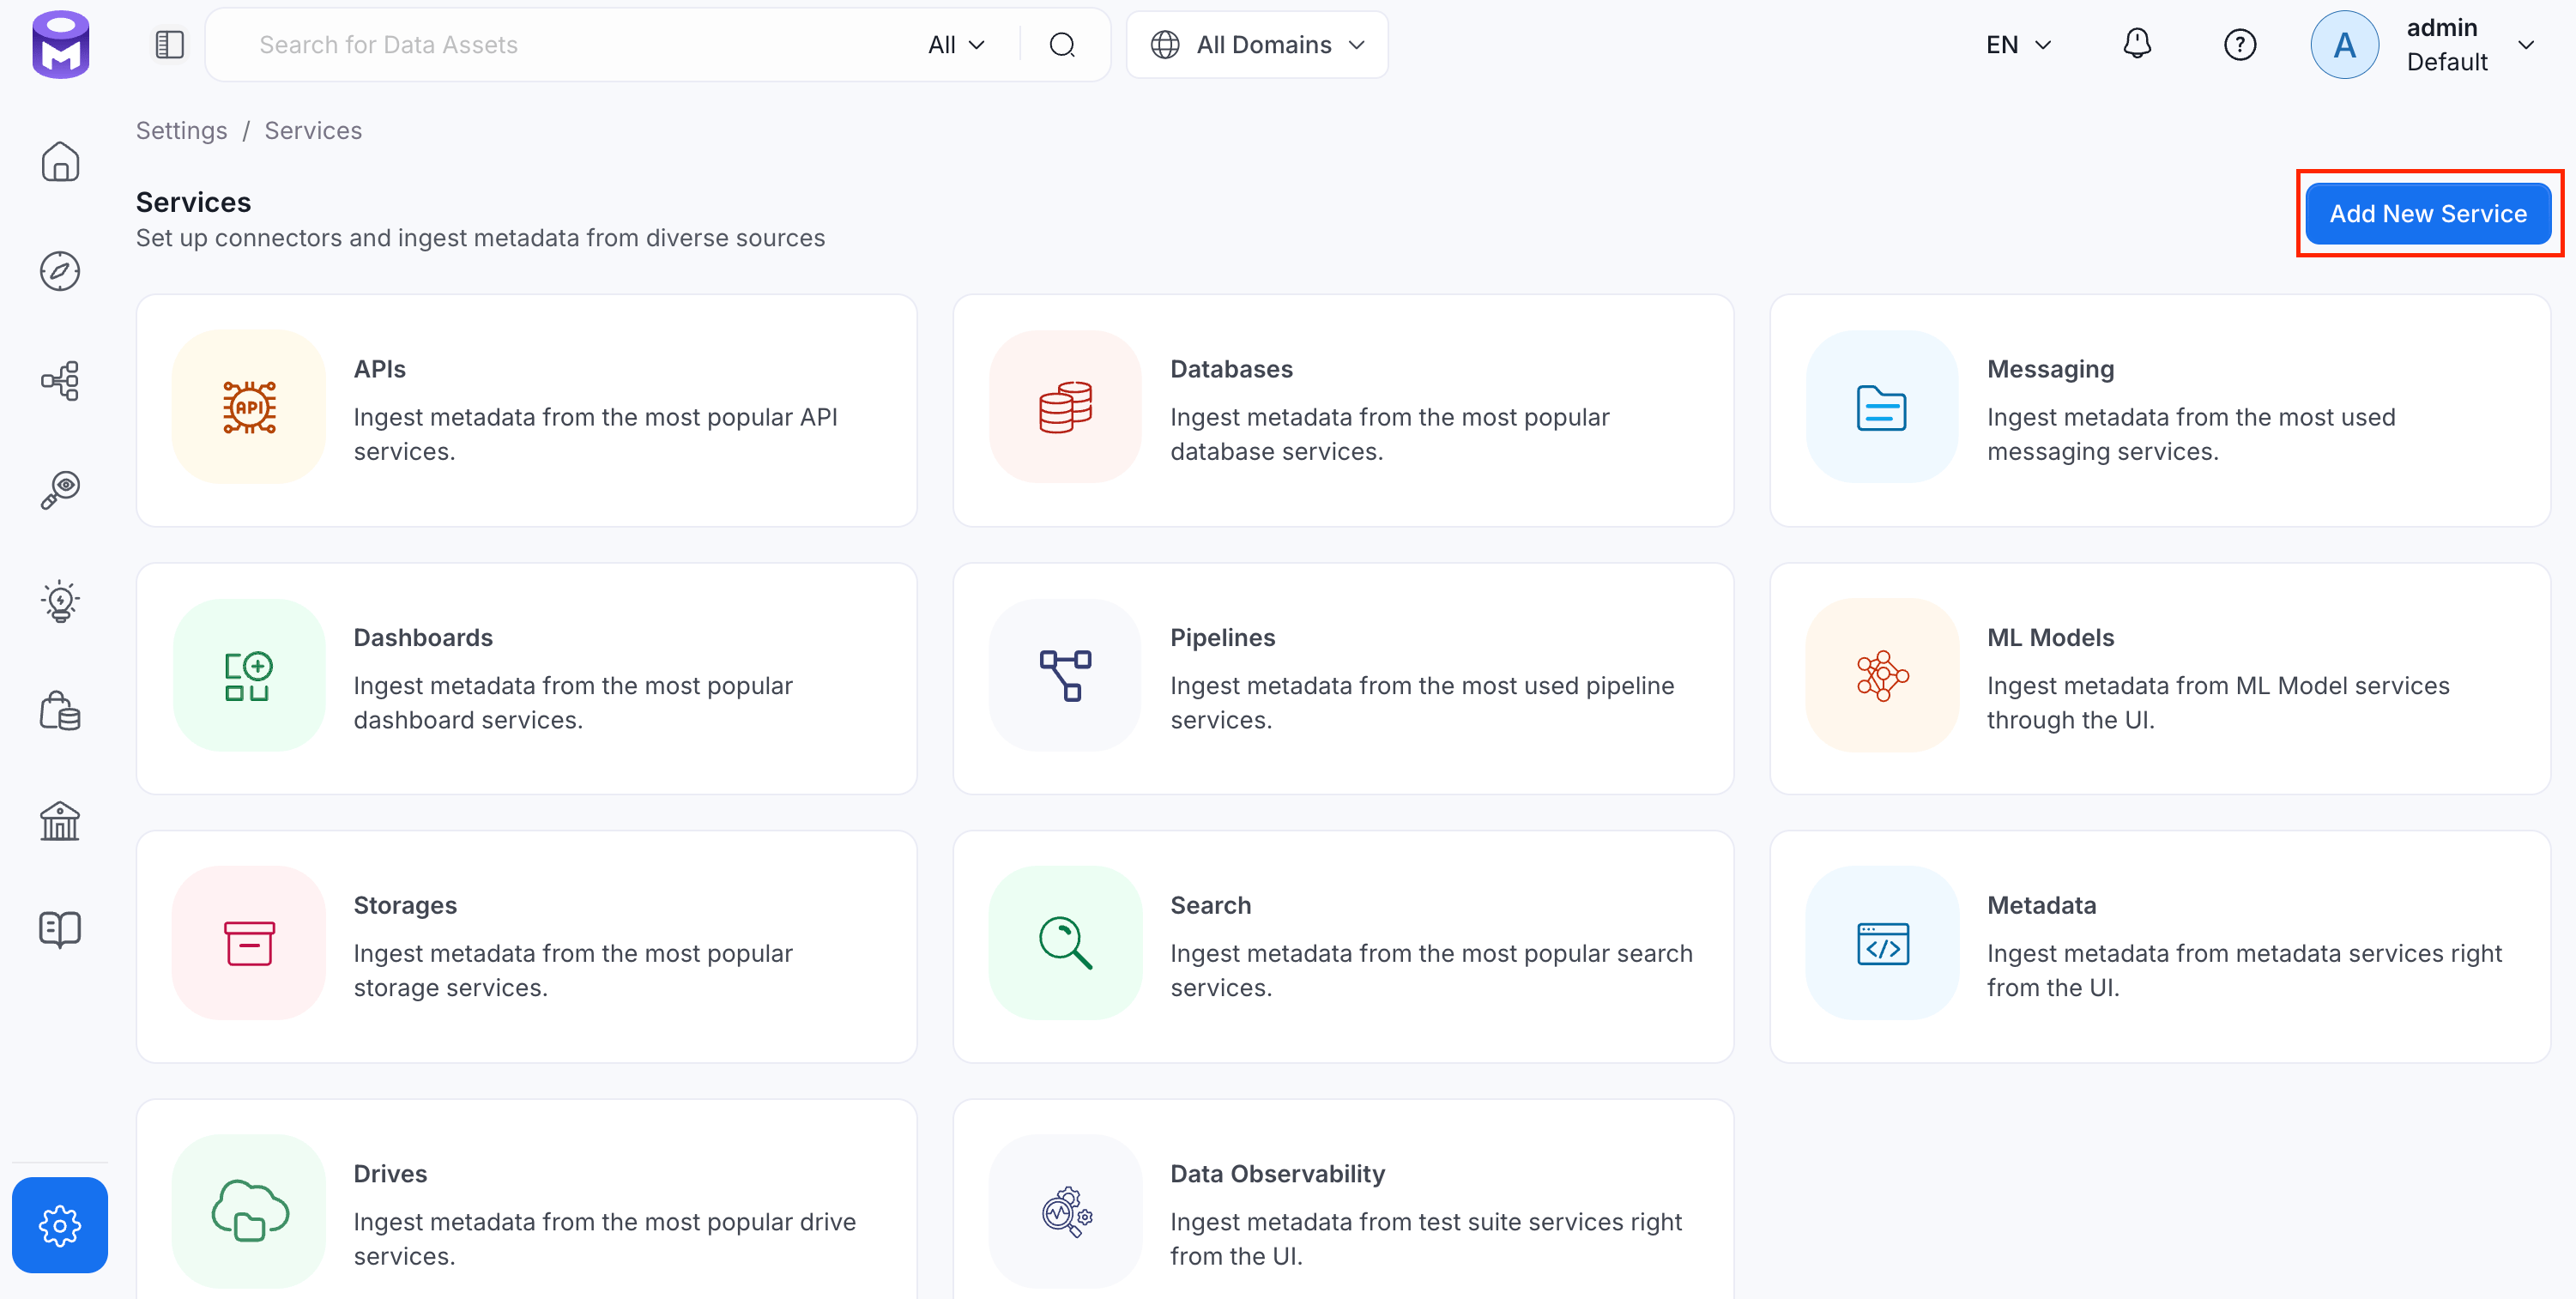
Step 2: Select a Service and Connector
From the service type dropdown, select Database Services, then click the Glue connector tile.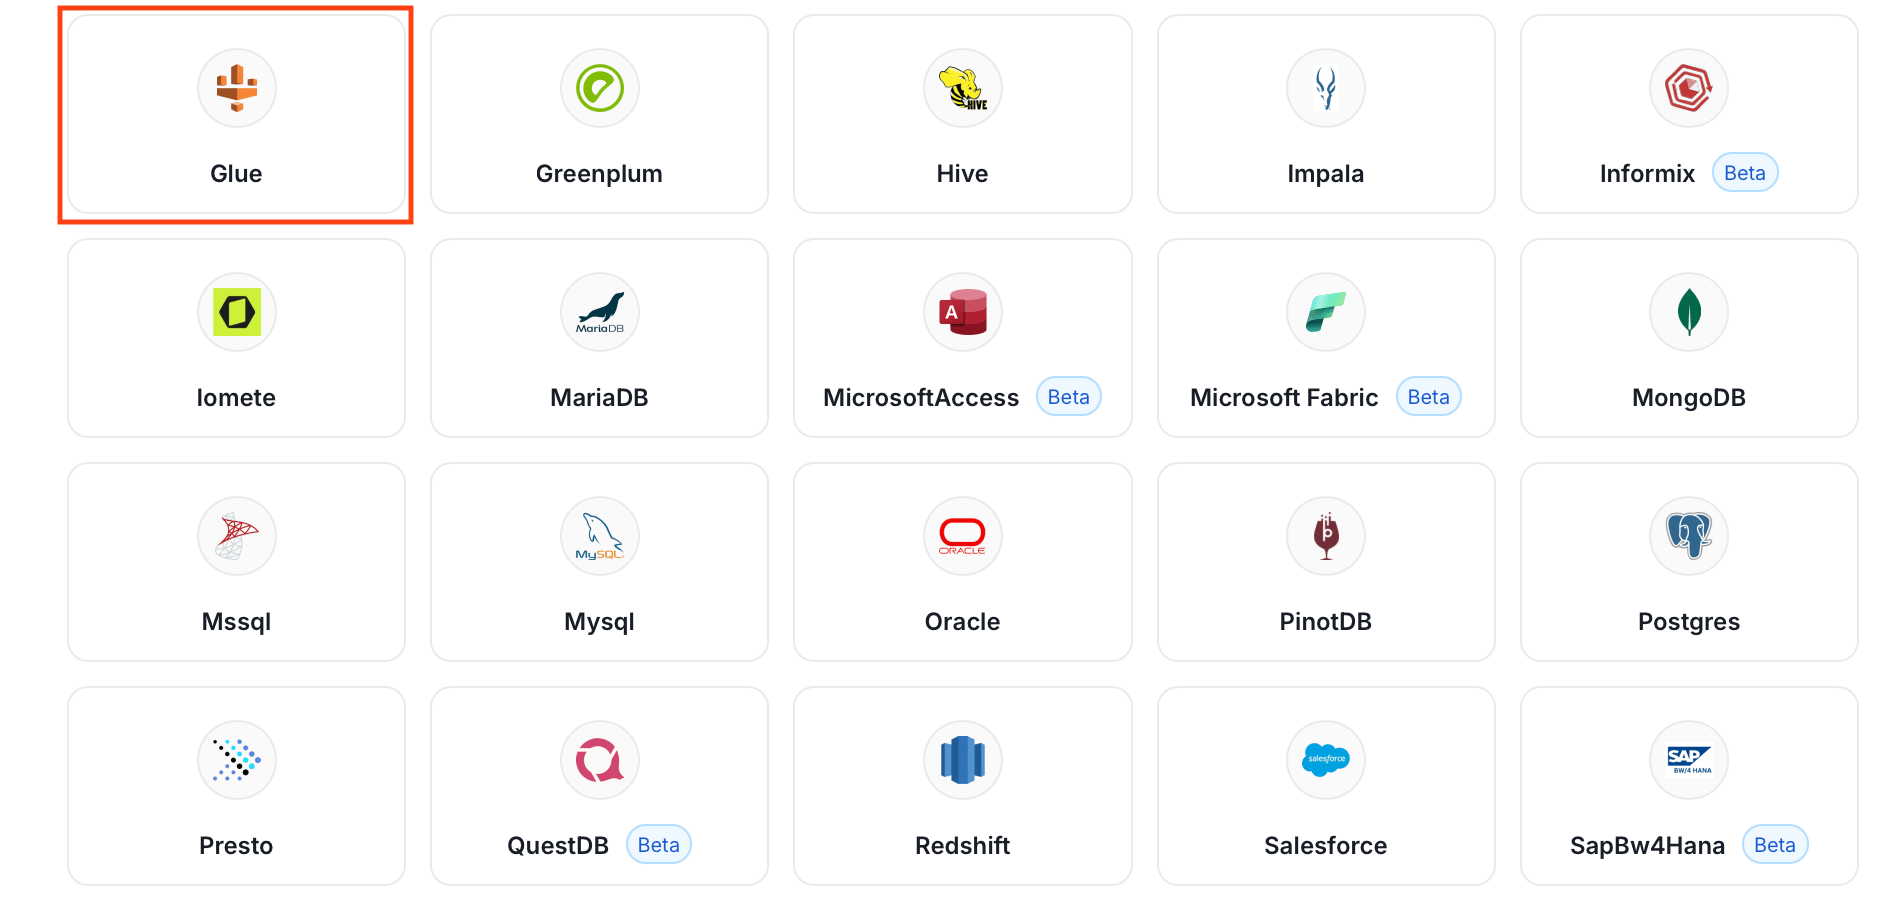
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. OpenMetadata identifies services by their service name. Enter a name that distinguishes this deployment from other Glue services you are ingesting metadata from.
- Optional: Enter a Description for the service.
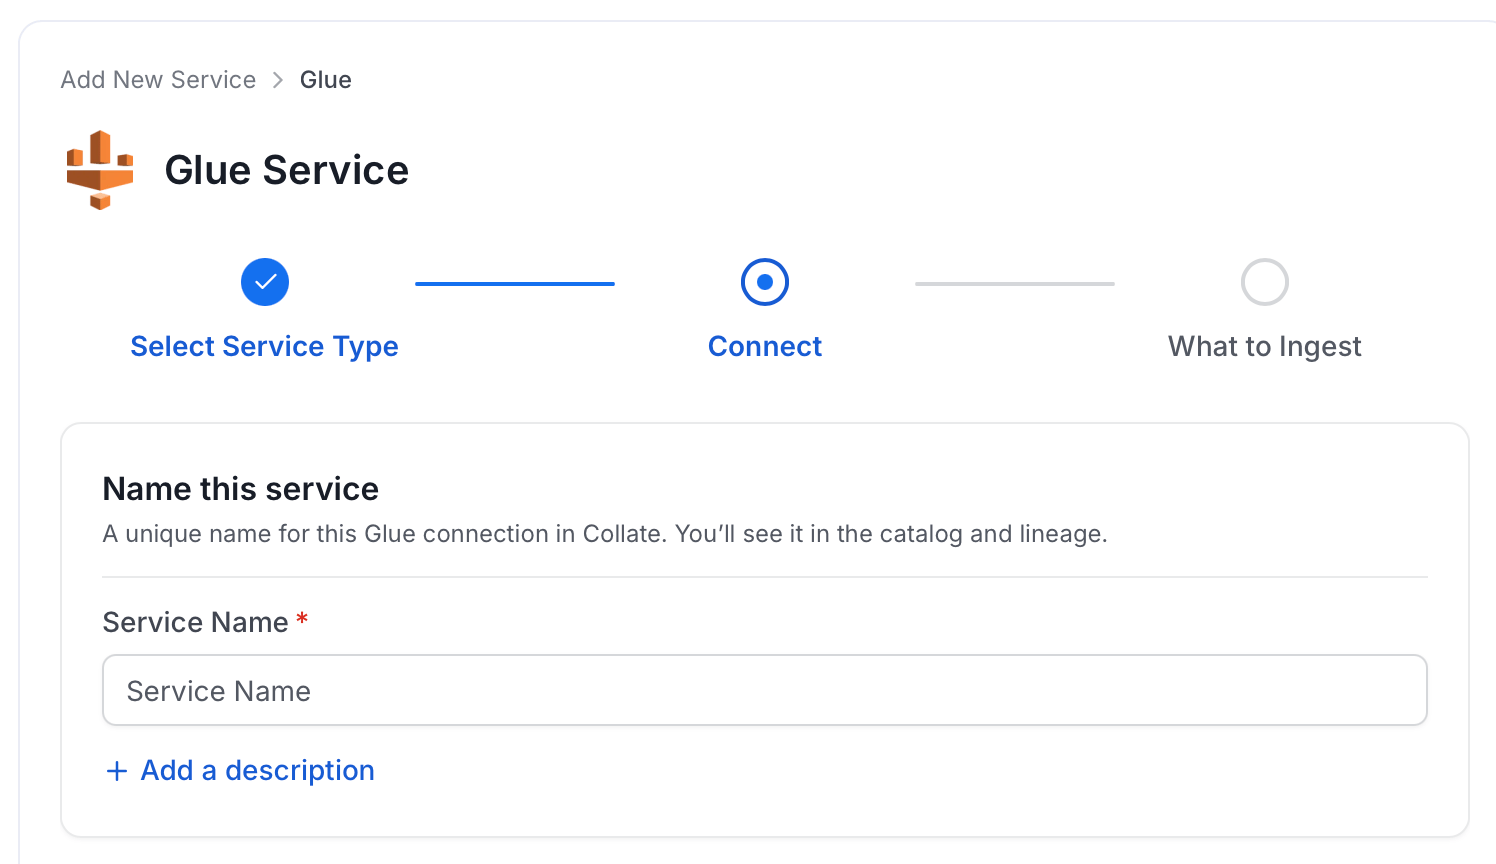
Note: The service name cannot be changed after it is set.
Step 4: Configure Connection Options
Specify your source credentials and verify the connection.Enter Connection Details
Enter the connection details for Glue. The right-hand panel in the UI displays inline help for each field.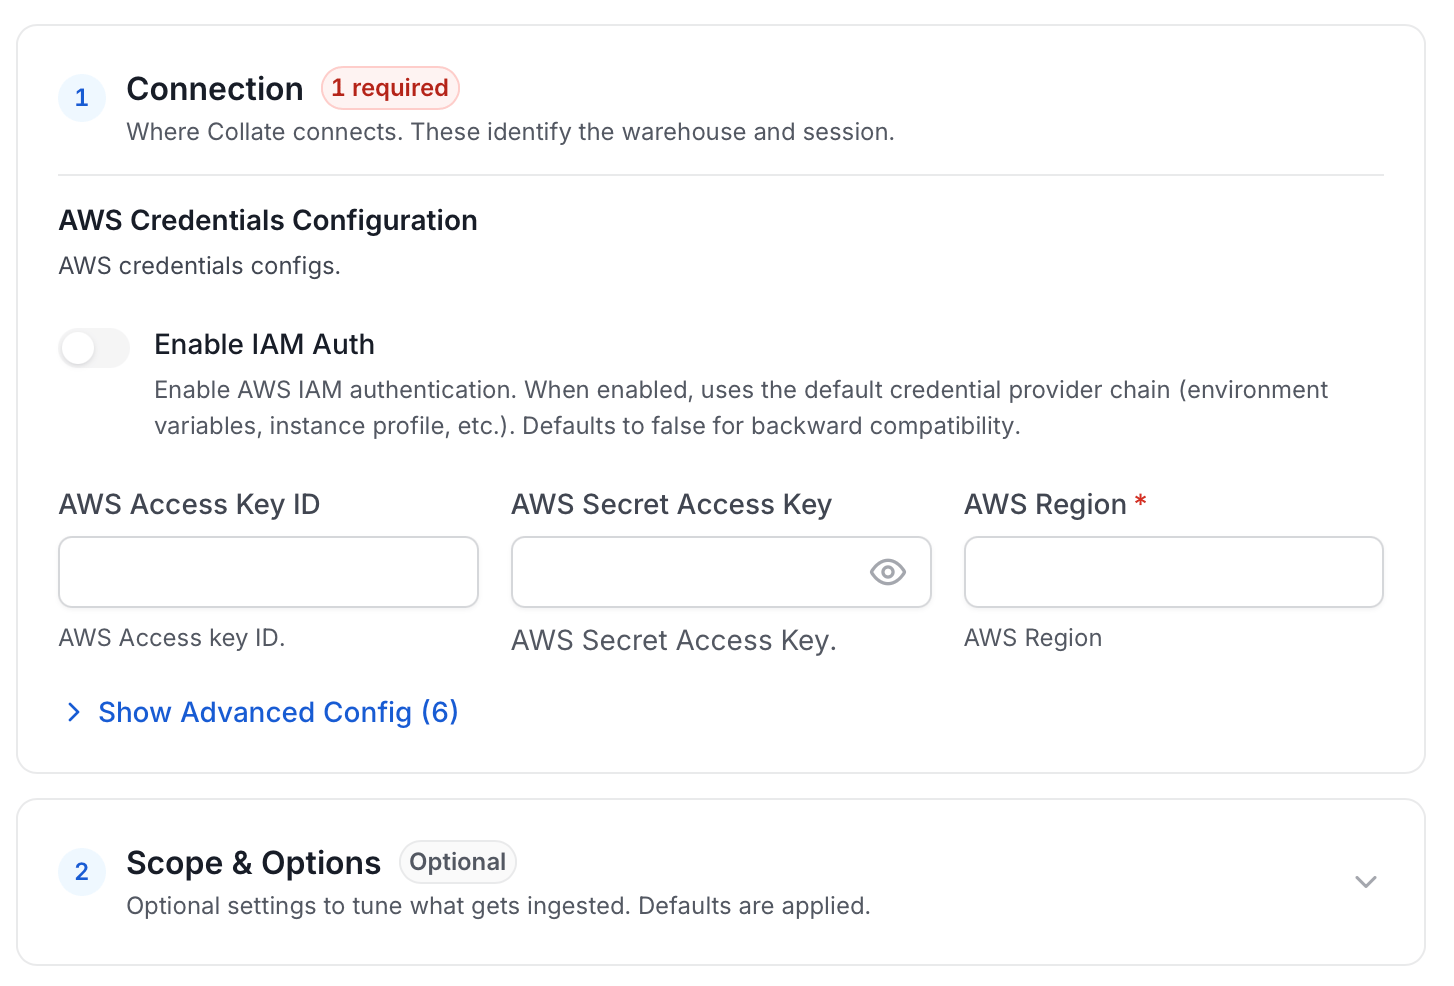
- AWS Access Key ID & AWS Secret Access Key: When you interact with AWS, you specify your AWS security credentials to verify who you are and whether you have
permission to access the resources that you are requesting. AWS uses the security credentials to authenticate and
authorize your requests (docs).
Access keys consist of two parts: An access key ID (for example,
AKIAIOSFODNN7EXAMPLE), and a secret access key (for example,wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY). You must use both the access key ID and secret access key together to authenticate your requests. You can find further information on how to manage your access keys. - AWS Region: Each AWS Region is a separate geographic area in which AWS clusters data centers (docs). As AWS can have instances in multiple regions, we need to know the region the service you want reach belongs to. Note that the AWS Region is the only required parameter when configuring a connection. When connecting to the services programmatically, there are different ways in which we can extract and use the rest of AWS configurations. You can find further information about configuring your credentials.
- AWS Session Token (optional): If you are using temporary credentials to access your services, you will need to inform the AWS Access Key ID and AWS Secrets Access Key. Also, these will include an AWS Session Token. You can find more information on Using temporary credentials with AWS resources.
- Endpoint URL (optional): To connect programmatically to an AWS service, you use an endpoint. An endpoint is the URL of the entry point for an AWS web service. The AWS SDKs and the AWS Command Line Interface (AWS CLI) automatically use the default endpoint for each service in an AWS Region. But you can specify an alternate endpoint for your API requests. Find more information on AWS service endpoints.
- Profile Name: A named profile is a collection of settings and credentials that you can apply to an AWS CLI command.
When you specify a profile to run a command, the settings and credentials are used to run that command.
Multiple named profiles can be stored in the config and credentials files.
You can inform this field if you’d like to use a profile other than
default. Find more information about Named profiles for the AWS CLI. - Assume Role Arn: Typically, you use
AssumeRolewithin your account or for cross-account access. In this field you’ll set theARN(Amazon Resource Name) of the policy of the other account. A user who wants to access a role in a different account must also have permissions that are delegated from the account administrator. The administrator must attach a policy that allows the user to callAssumeRolefor theARNof the role in the other account. This is a required field if you’d like toAssumeRole. Find more information on AssumeRole.
- Assume Role Session Name: An identifier for the assumed role session. Use the role session name to uniquely identify a session when the same role
is assumed by different principals or for different reasons.
By default, we’ll use the name
OpenMetadataSession. Find more information about the Role Session Name. - Assume Role Source Identity: The source identity specified by the principal that is calling the
AssumeRoleoperation. You can use source identity information in AWS CloudTrail logs to determine who took actions with a role. Find more information about Source Identity. - Database Name (optional): The name of a single OpenMetadata database that holds all your Glue databases. If you leave it blank, the connector creates one database per catalog and names it after the catalog ID, which is your AWS account ID. Setting this field also changes how catalogs are mapped and filtered. For more information, see How Glue Maps to OpenMetadata.
Test Connection
Once the credentials have been added, click on Test Connection and Save the changes.
Step 5: Configure Ingestion Options
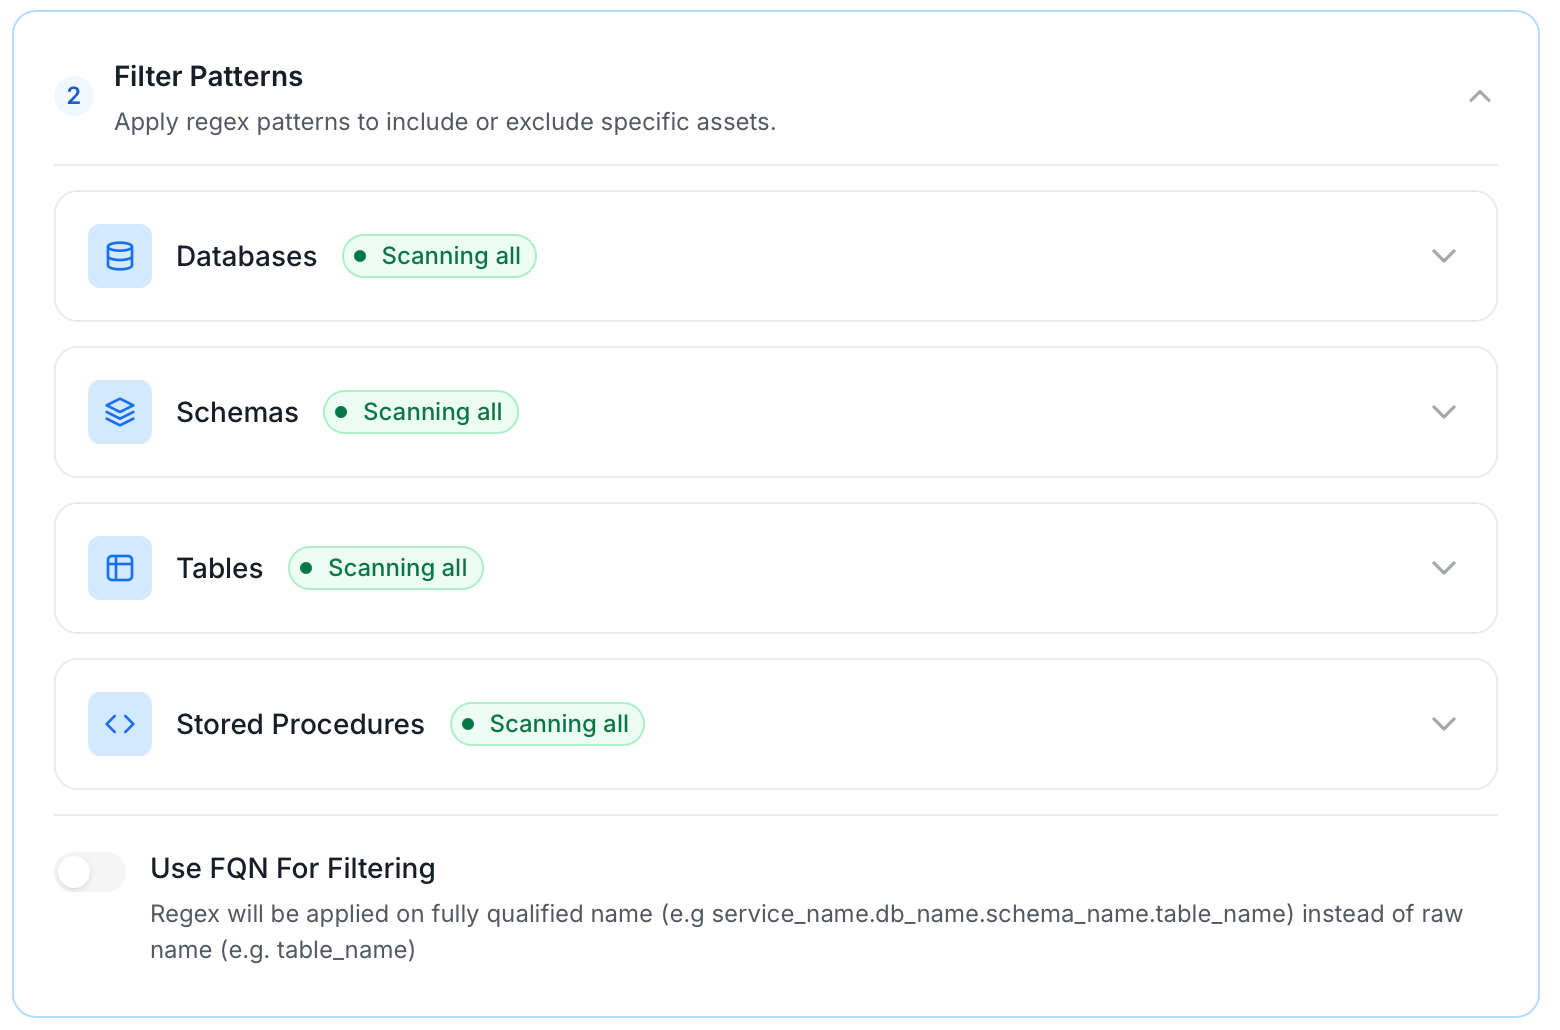
In the What to Ingest step, use filter patterns to control which assets OpenMetadata ingests from your database service. Filter patterns use regular expressions applied to asset names.How Filter Patterns Work
- Include: Add one or more comma-separated regular expressions. OpenMetadata ingests only assets whose names match at least one expression. Leave blank to include all assets.
- Exclude: Add one or more comma-separated regular expressions. OpenMetadata skips any asset whose name matches an expression. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
- Database: Controls which catalogs OpenMetadata ingests when Database Name is blank. Rules match the catalog ID, not Glue database names.
- Schema: Controls which Glue databases OpenMetadata ingests. Rules match the Glue database name.
- Table: Controls which tables and views OpenMetadata ingests. Rules match the Glue table name.
- Scan Mode: You can choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Exclude system toggle: Use this toggle to automatically filter out system-reserved names defined by the connector, for example, Exclude system databases for the Databases section.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules (available only in Only specific mode): Click + Add to define a rule. Added rules appear as chips; an asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. OpenMetadata saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
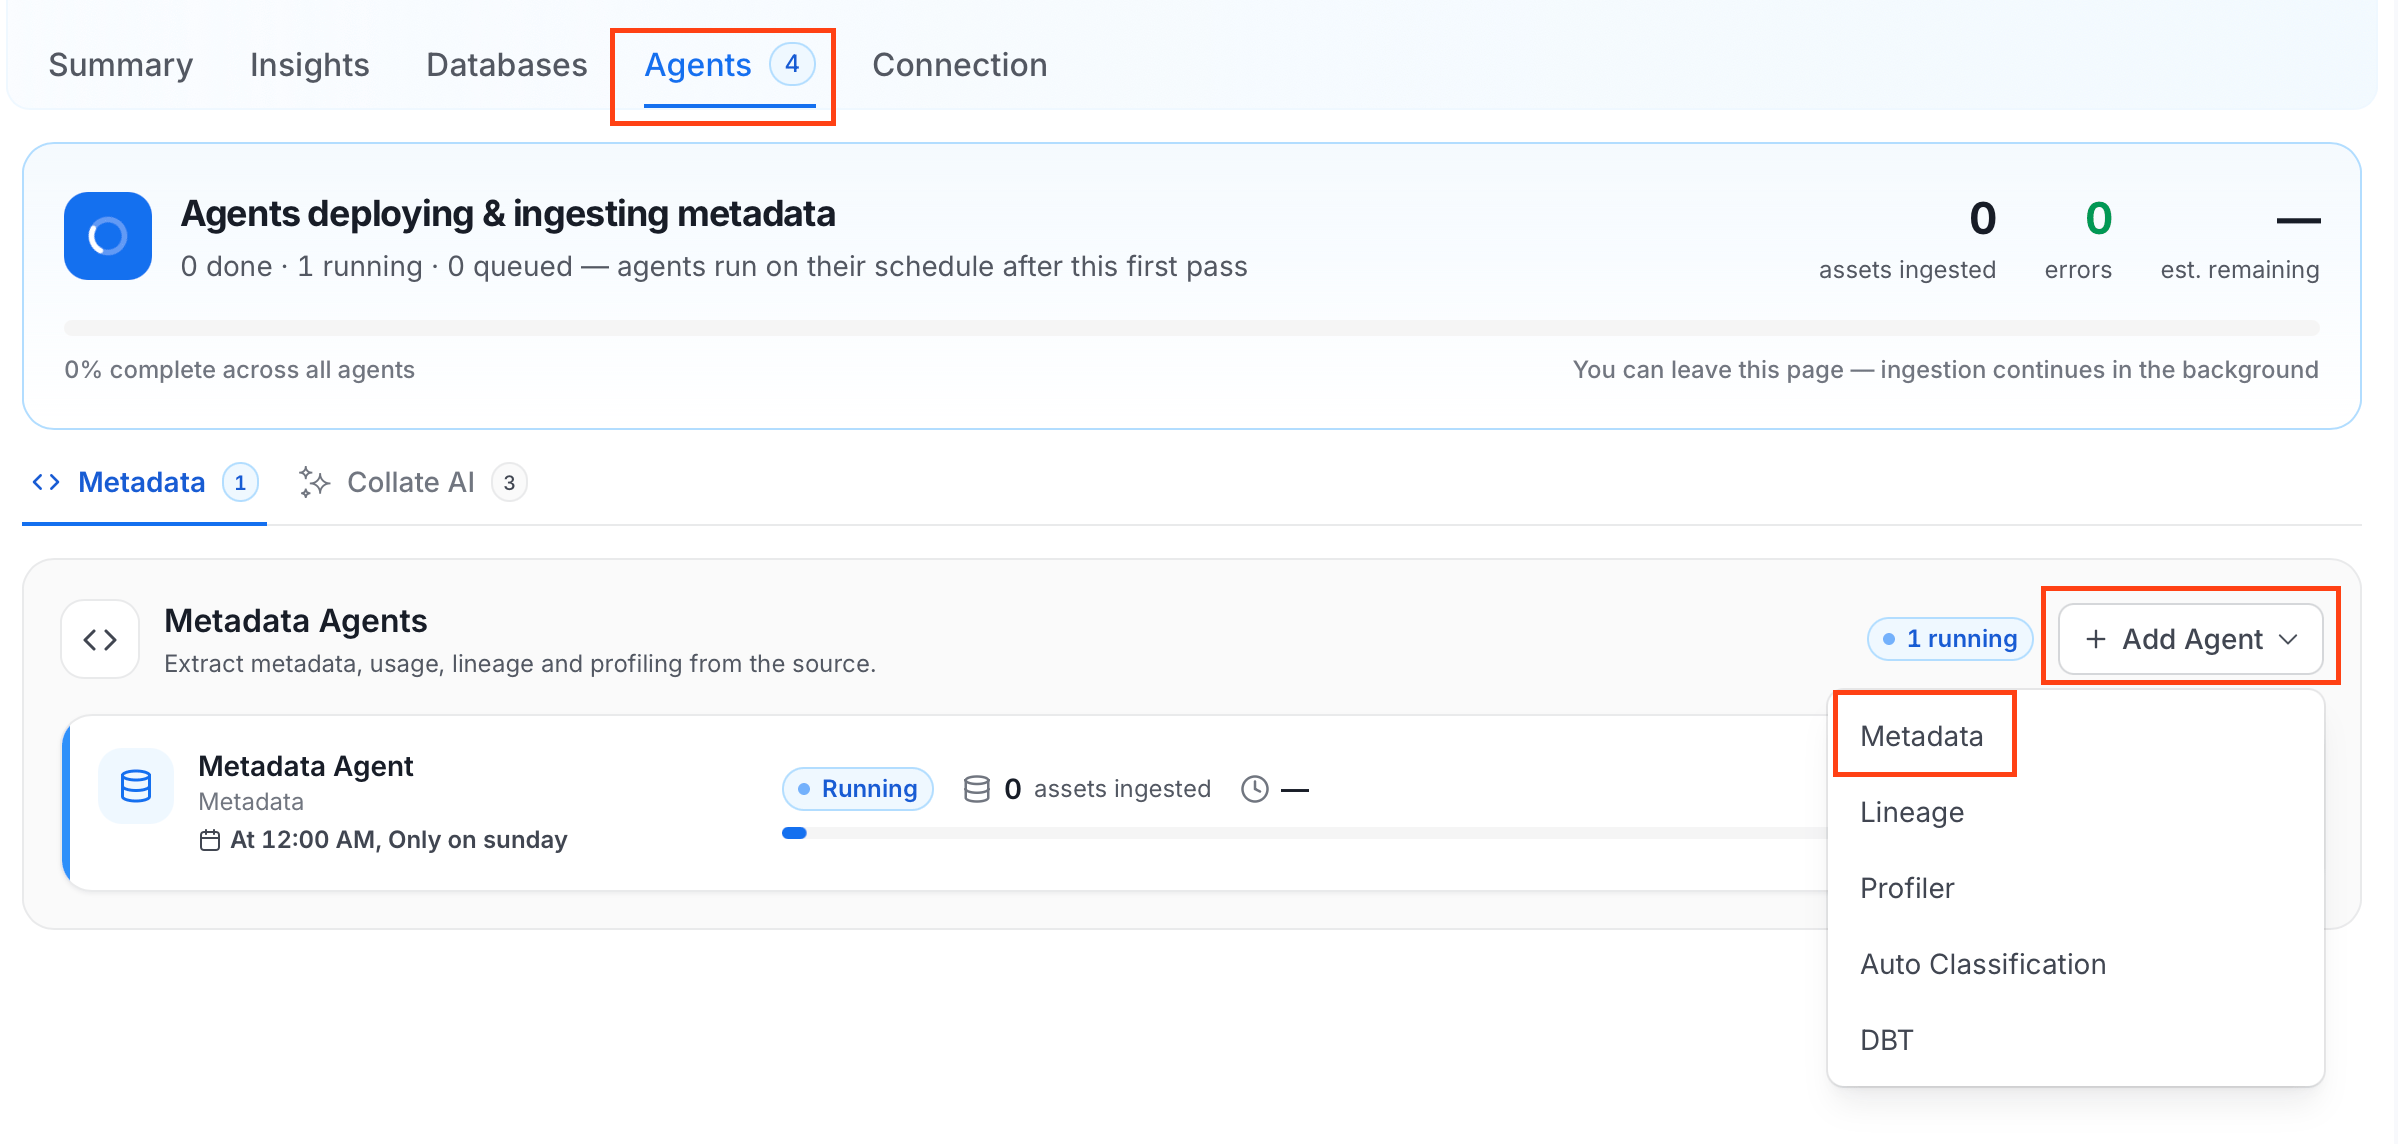
The Metadata Agent extracts schemas, tables, columns, and other structural metadata from your source and keeps your OpenMetadata catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, OpenMetadata automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:-
Navigate to Settings > Services and select the service type.
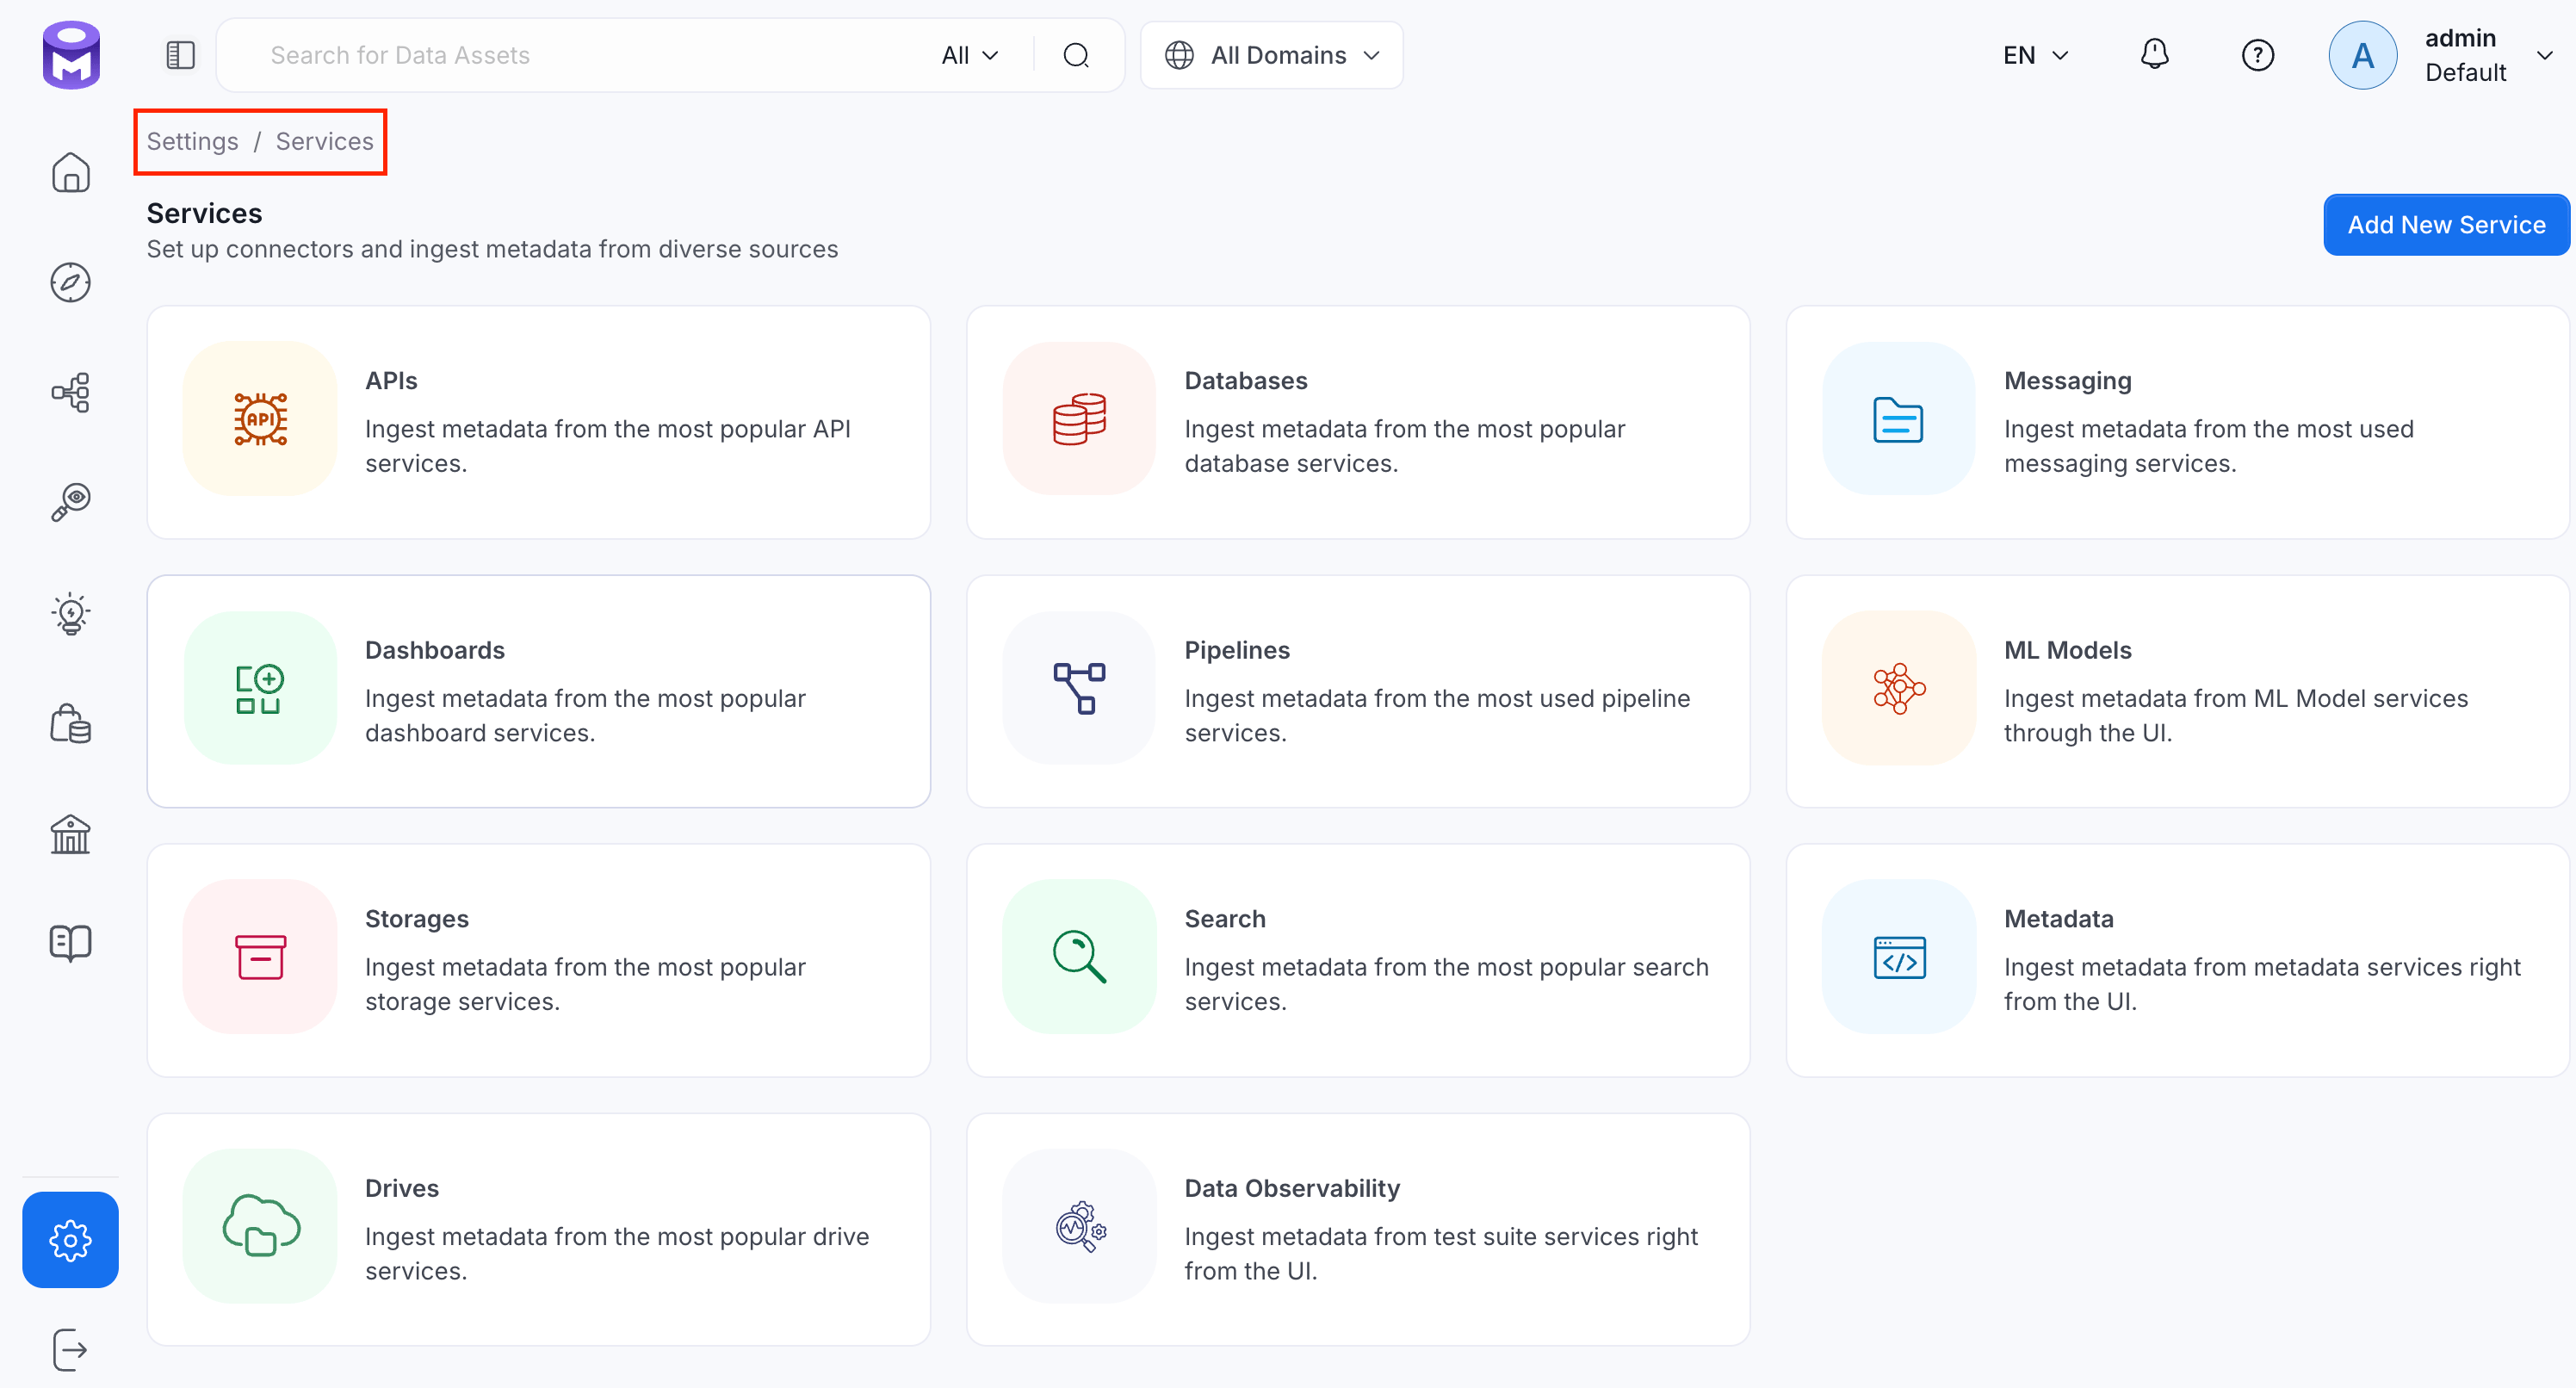
- Click the service you have added.
-
Select the Agents tab and click Add Agent > Metadata.
-
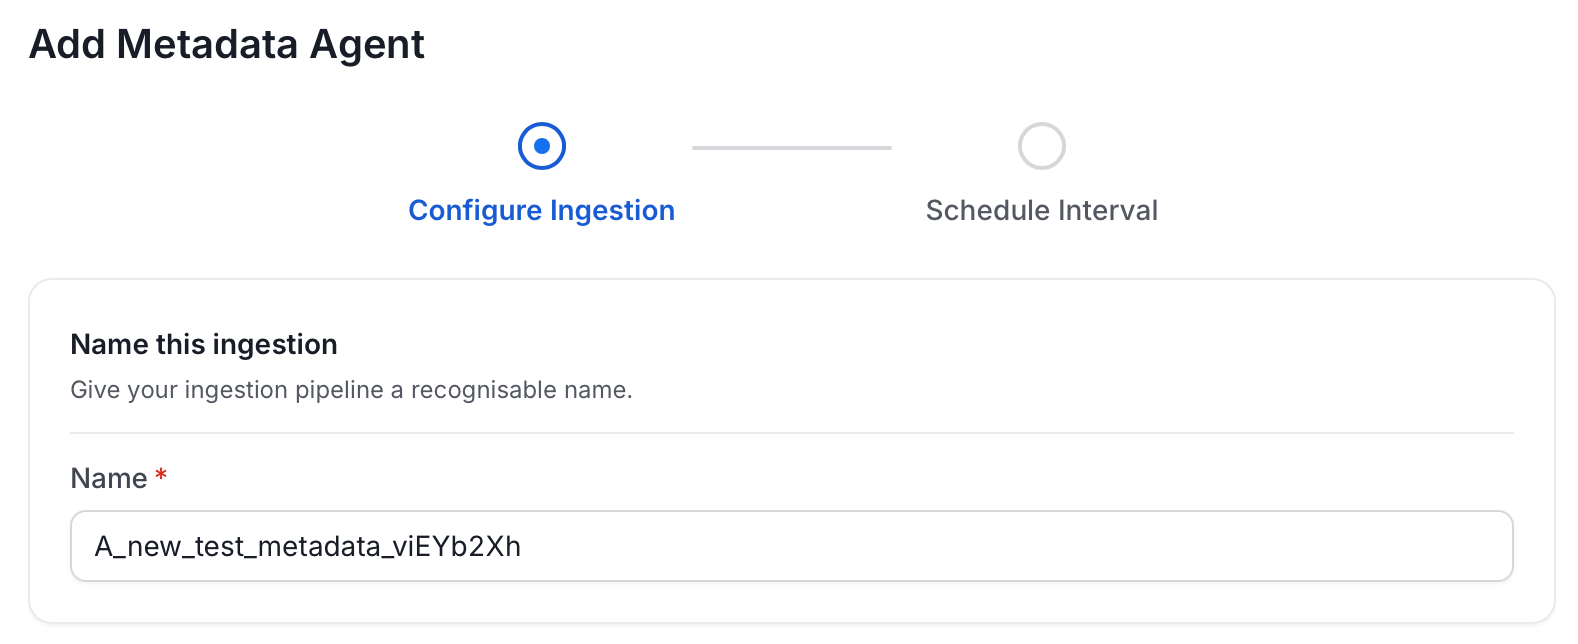
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.
-
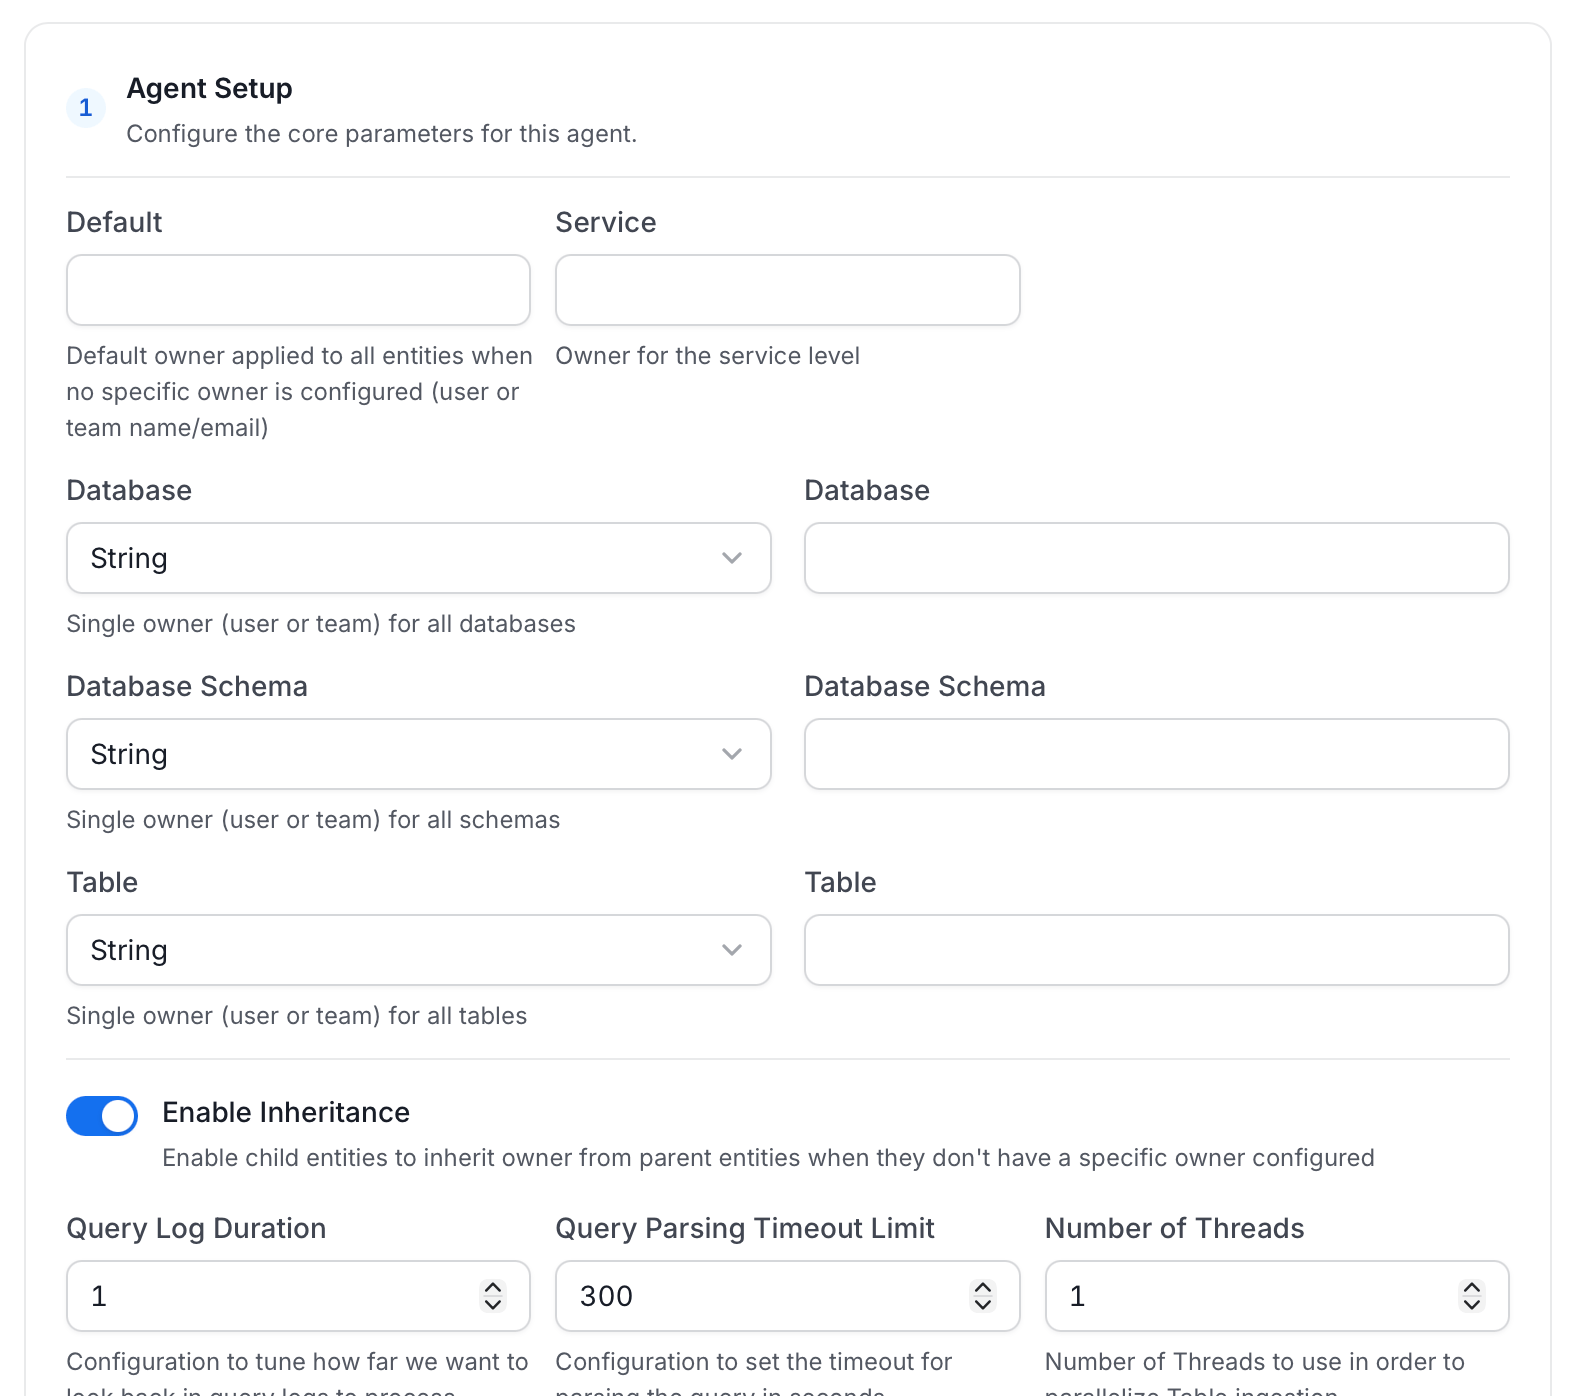
Agent Setup: Configure core parameters for metadata extraction. The following fields are available:
For more information about how the Default Owner, Service Owner, Database Owner, Database Schema Owner, Table Owner, and Enable Inheritance fields resolve an owner, see Hierarchical Owner Configuration.
-
Filter Patterns: Apply include or exclude rules to scope which databases, schemas, tables, and stored procedures this agent ingests. For more information about various filter options, see Step 6: Configure Ingestion Options.
-
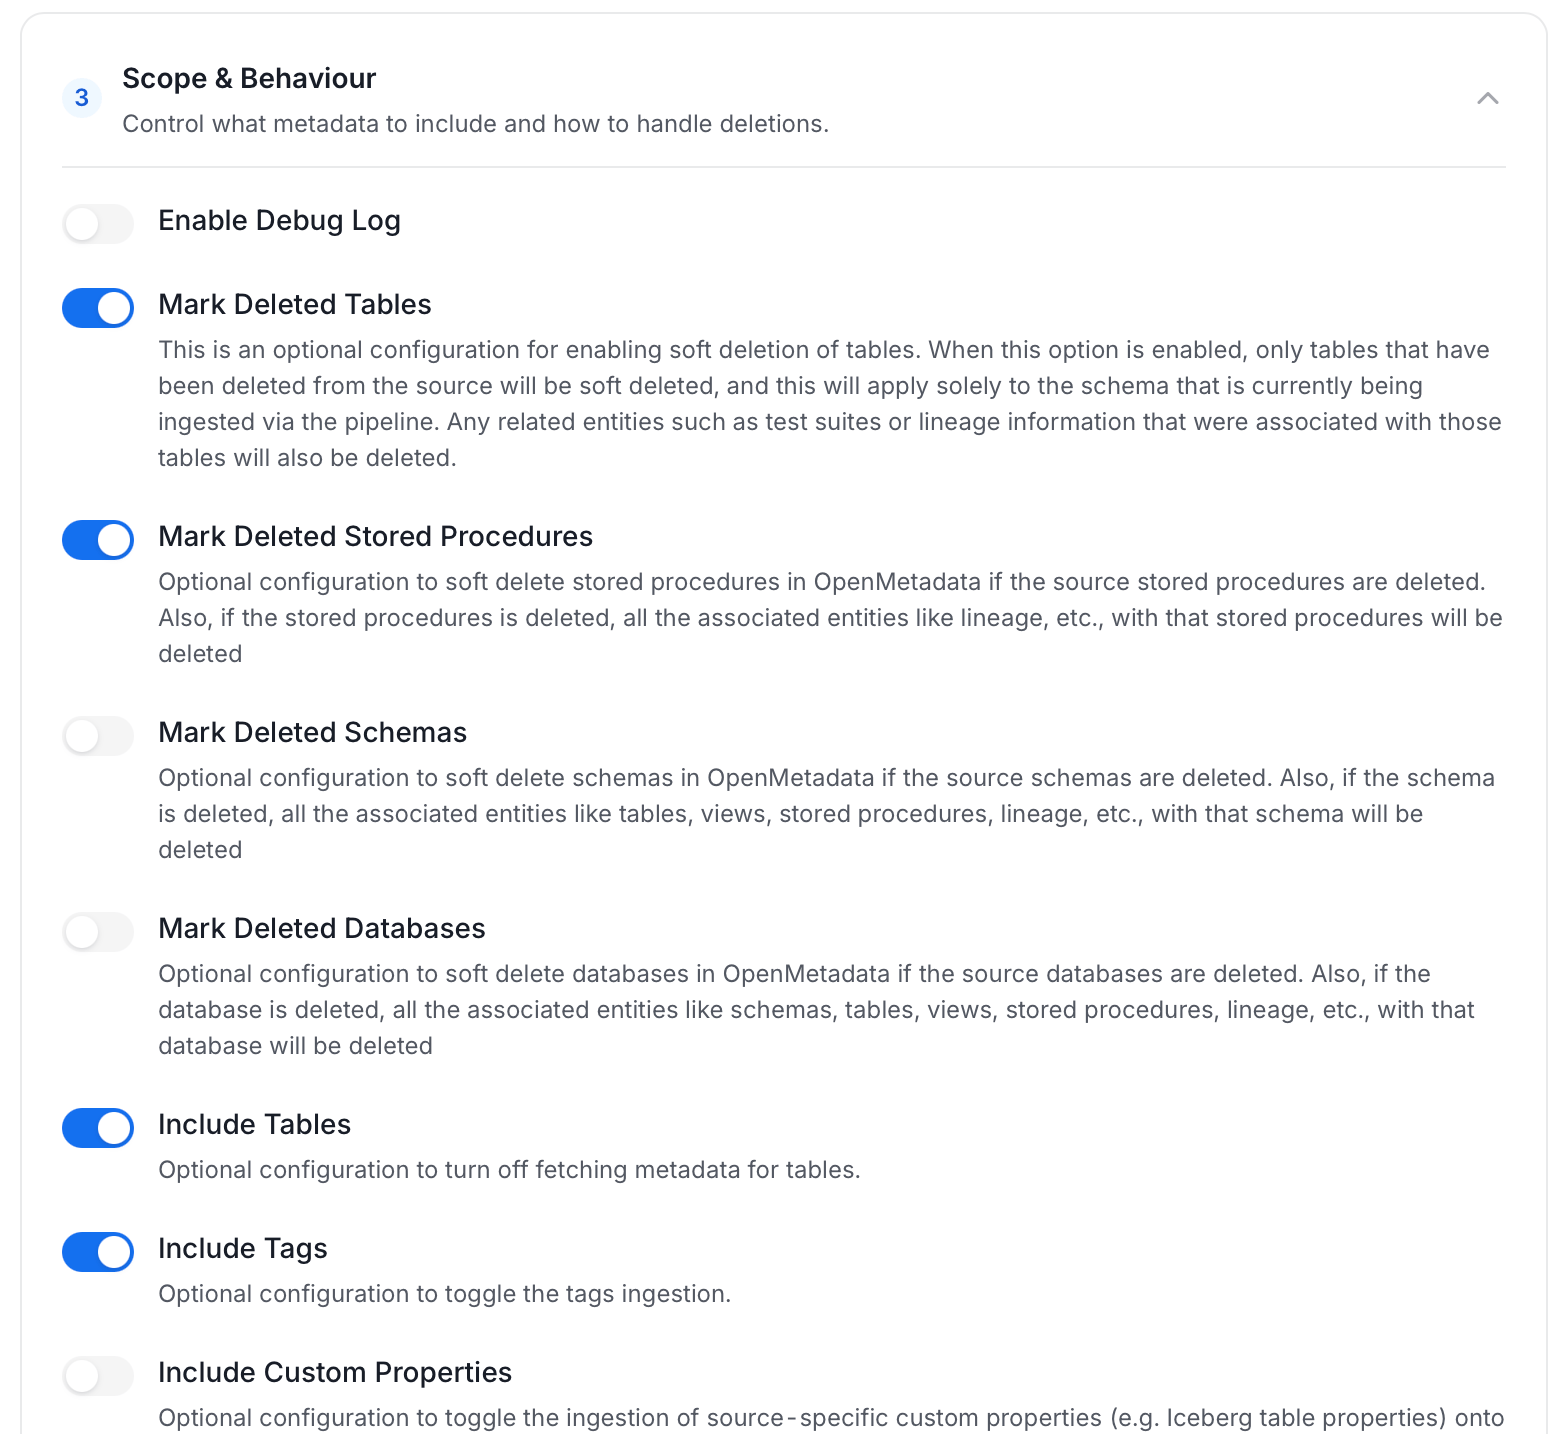
Scope & Behaviour: Control how the agent handles metadata during ingestion. Toggle each option on or off based on your needs:
Available toggles vary by connector. Stored procedure options only appear for connectors that support stored procedures.
-
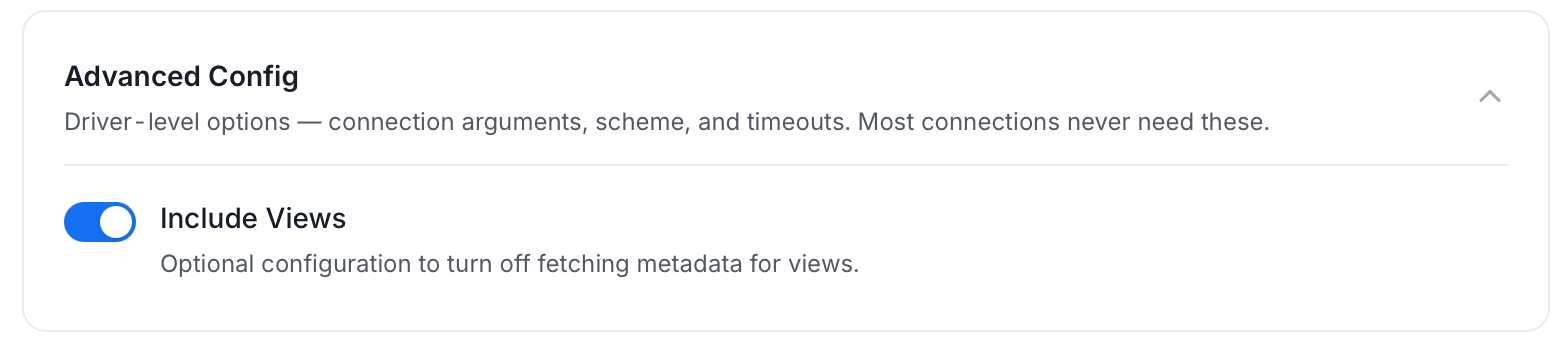
Advanced Config: Driver-level options (connection arguments, scheme, and timeouts). Most connections never need these, and they vary by connector. This section also has one ingestion-scope toggle:
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.
-
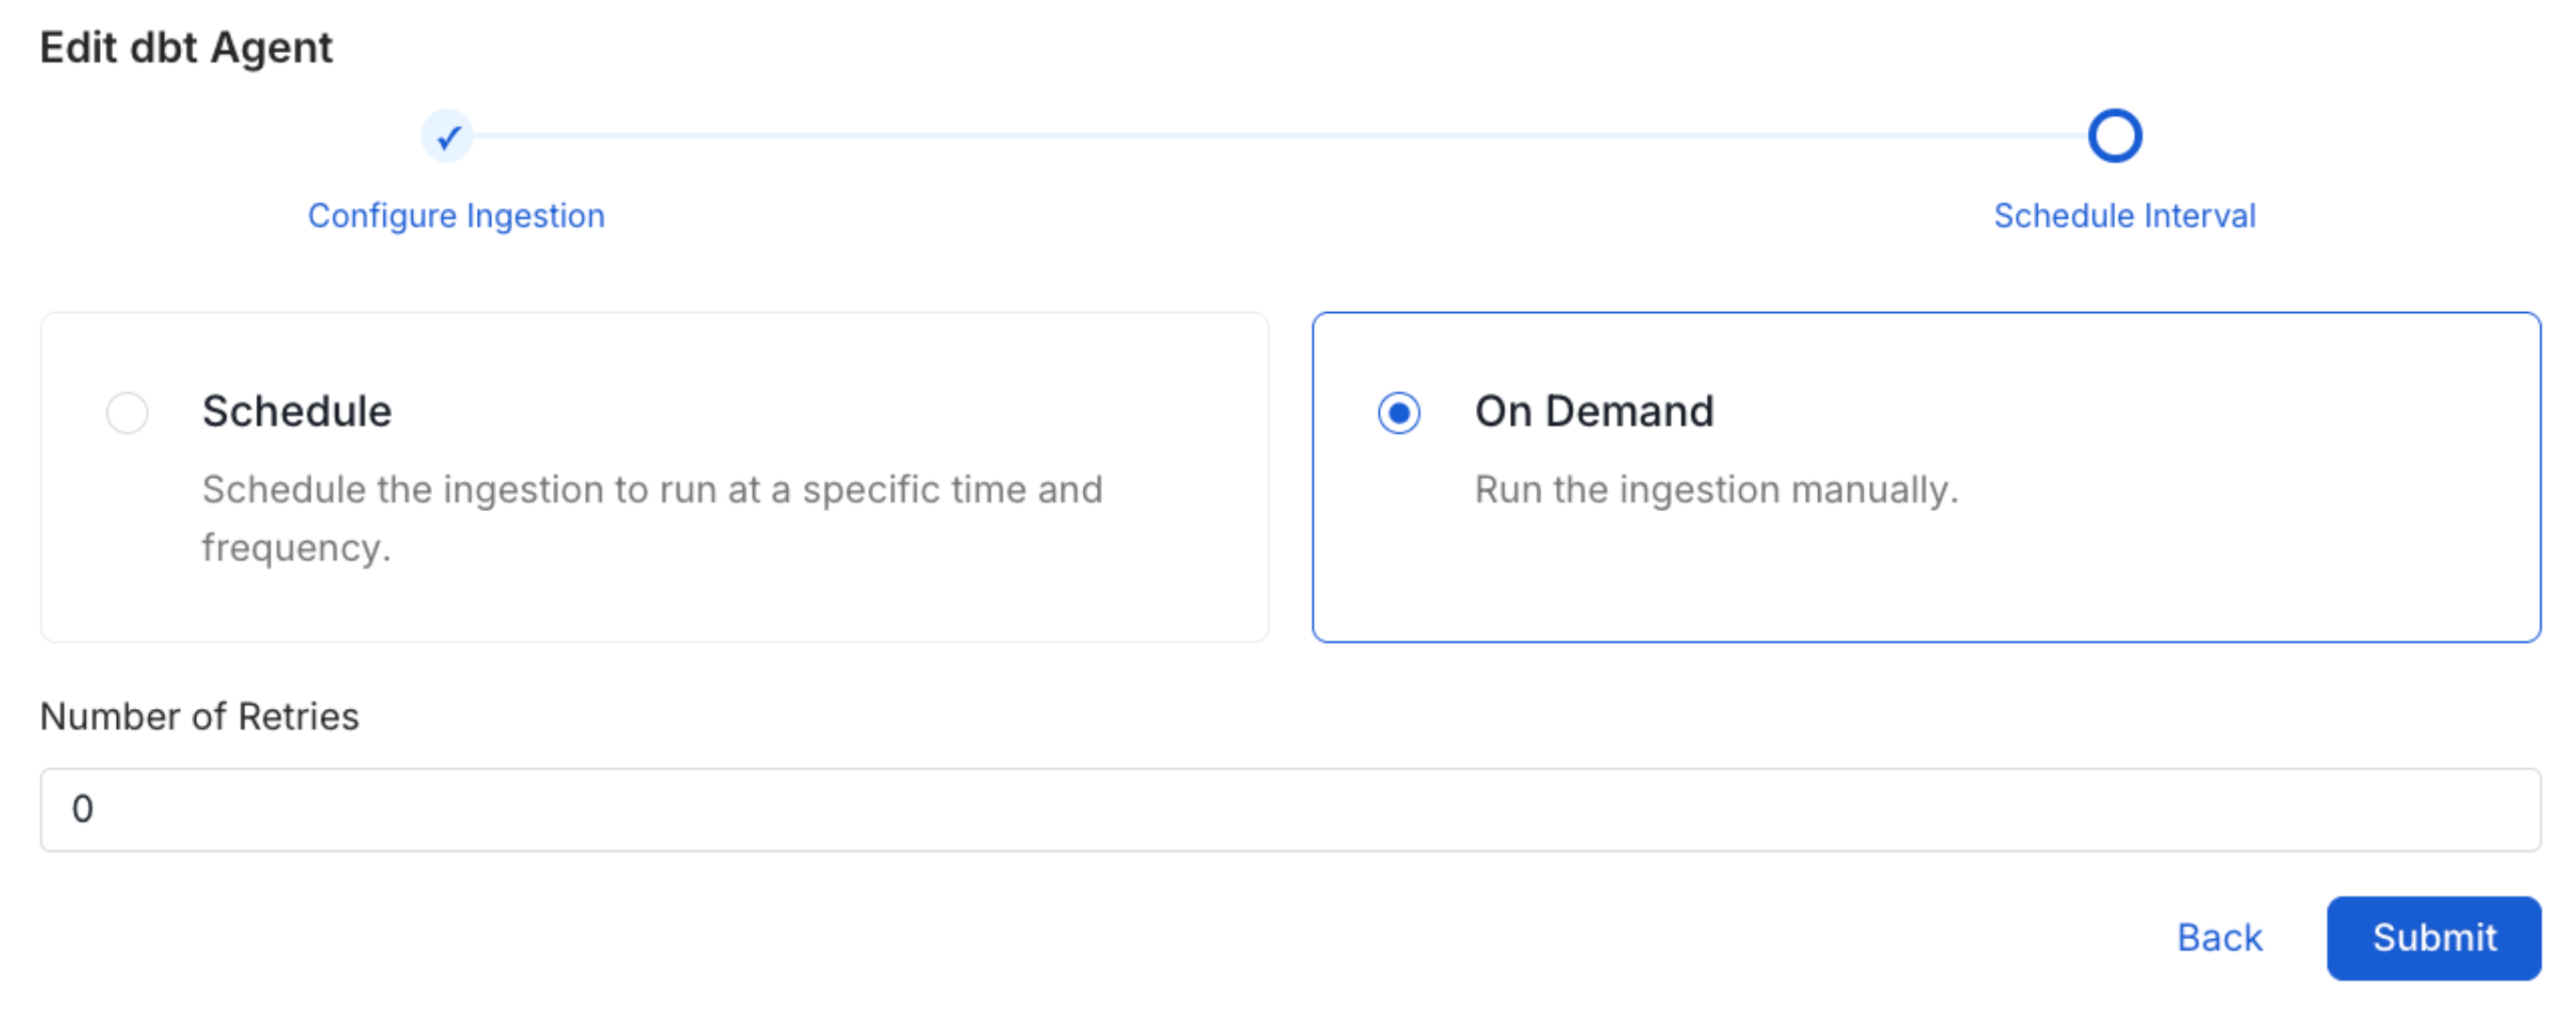
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule; trigger the agent manually when needed.
- Click Add to deploy the agent.
Related
Usage Workflow
Learn more about how to configure the Usage Workflow to ingest Query information from the UI.
Lineage Workflow
Learn more about how to configure the Lineage from the UI.
Profiler Workflow
Learn more about how to configure the Data Profiler from the UI.
Data Quality Workflow
Learn more about how to configure the Data Quality tests from the UI.
dbt Integration
Learn more about how to ingest dbt models’ definitions and their lineage.