
Requirements
OpenMetadata connects to Tableau Server or Tableau Cloud through the Tableau REST API and the Tableau Metadata API.- Tableau Server or Tableau Cloud: OpenMetadata must be able to reach it and authenticate with a username and password or a personal access token.
- Metadata API enabled: Required for lineage. Without it, metadata and run status still ingest, but OpenMetadata draws no lineage edges. For more information, see Start the Metadata API.
- Permissions: The user needs permission to list flows and flow runs, and to query the Metadata API for lineage. Users who are not administrators see only the runs of flows they can view.
- Tableau Prep Conductor: Flows can run manually without Data Management, but scheduled flow runs need Tableau Prep Conductor.
- Site administrator for extract refresh status: Tableau answers extract refresh job queries only for server and site administrators. Other users still get extract refresh pipelines for the refresh tasks they own, but without run status.
Lineage
The connector reads lineage from the Tableau Metadata API:- Input to output lineage: Each table or published data source a flow reads is linked to the tables or published data sources it writes, with the flow shown on the lineage edge.
- Flow to flow lineage: A flow is linked to the flows that consume its output. Only direct consumers are linked.
- Extract refresh lineage: An extract refresh pipeline is linked to the published data source or workbook data model it refreshes.
Note: Column-level lineage is not available for Tableau Pipeline.
Metadata Ingestion
To ingest metadata from Tableau Pipeline, you need to create a service connection. The service connects Tableau Pipeline with OpenMetadata. After you create the service and deploy the metadata agent, OpenMetadata starts ingesting metadata.Step 1: Add New Service
-
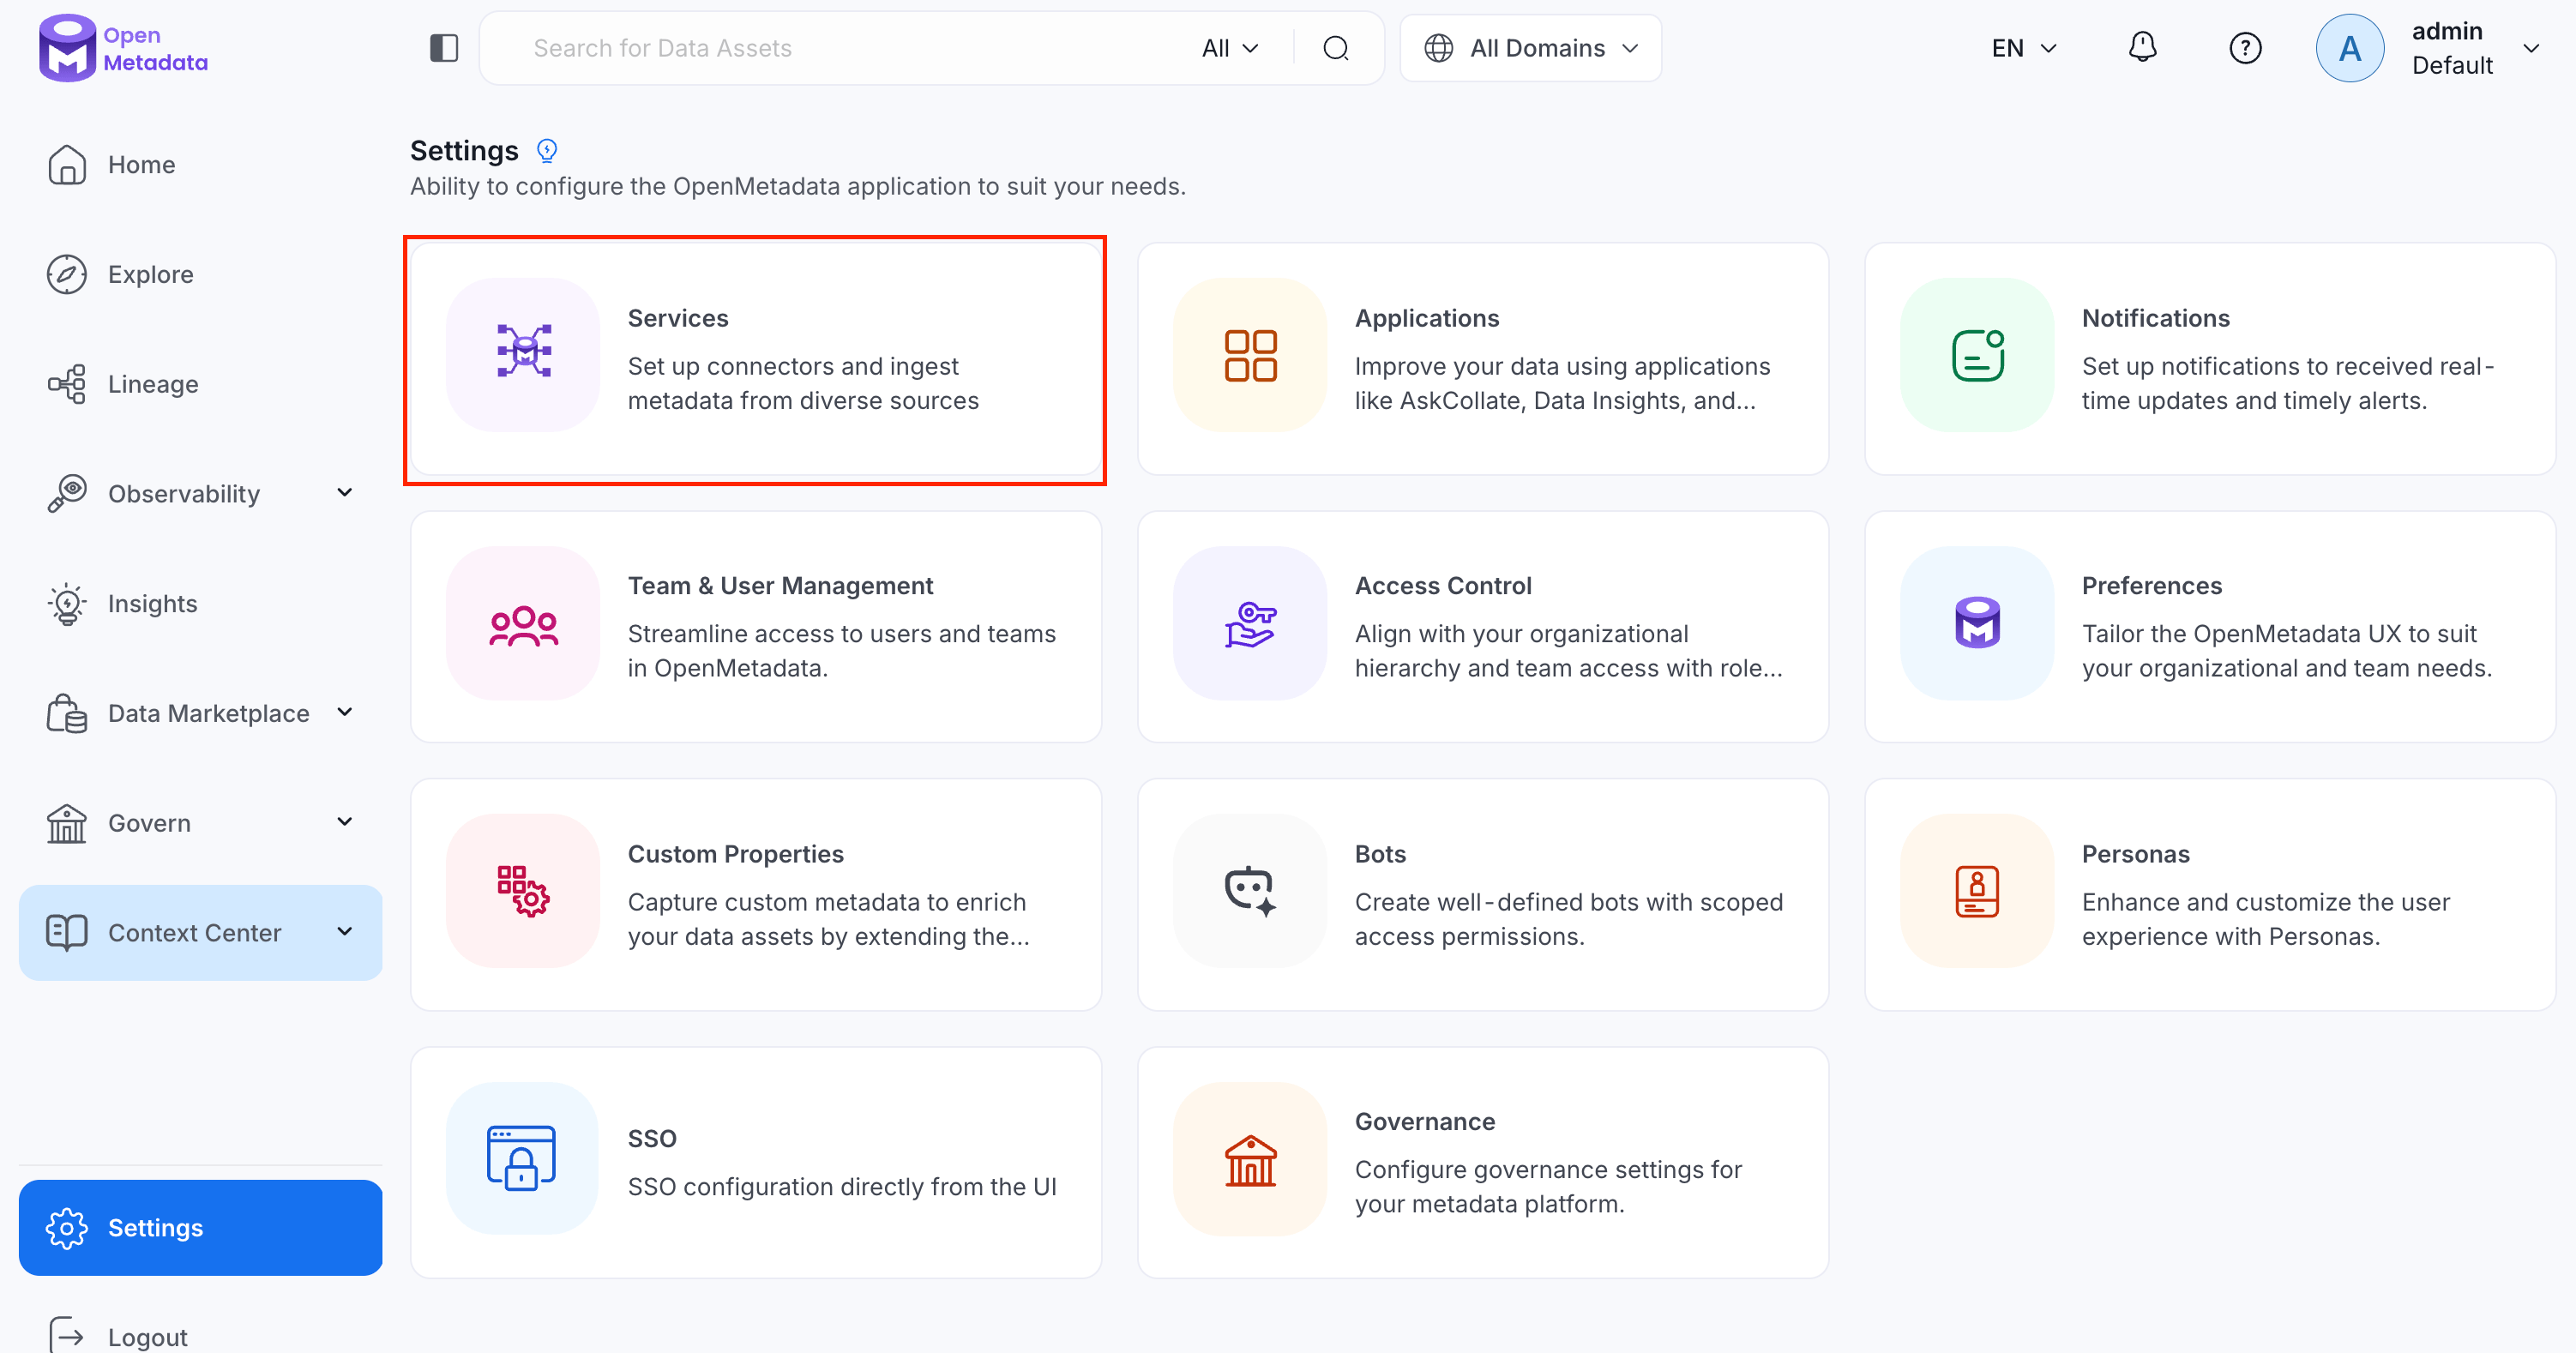
Navigate to Settings > Services.
-
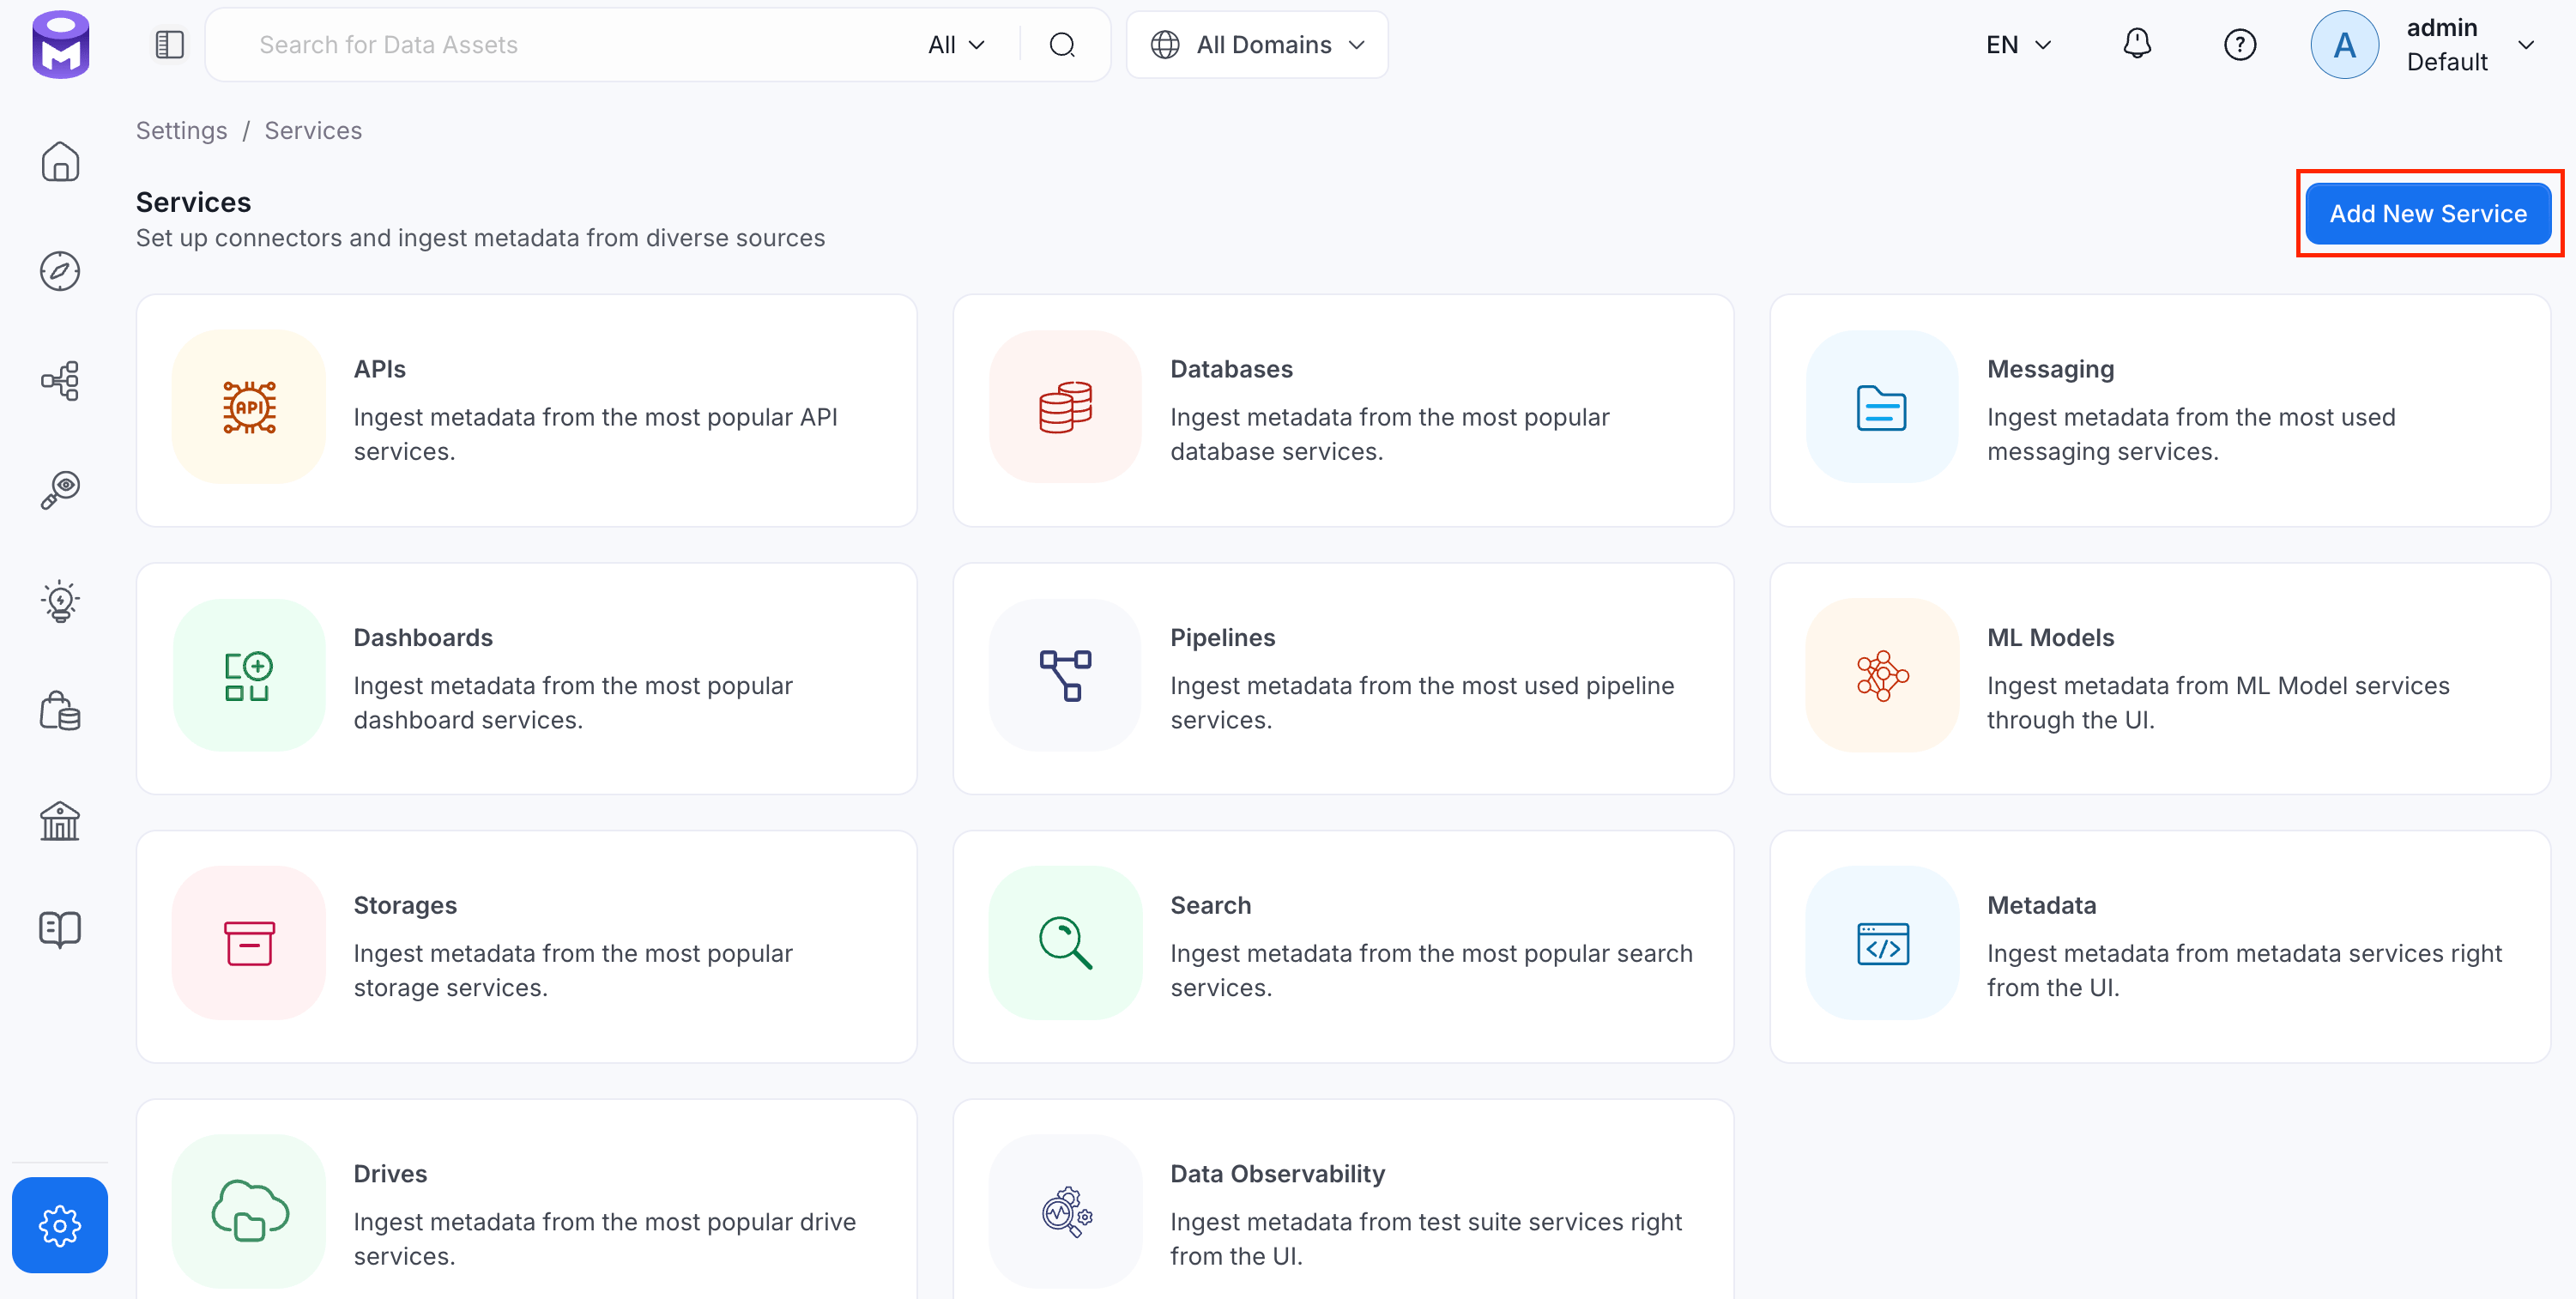
Click Add New Service.
Step 2: Select a Service and Connector
From the service type dropdown, select Pipeline Services, then click the Tableau Pipeline connector tile.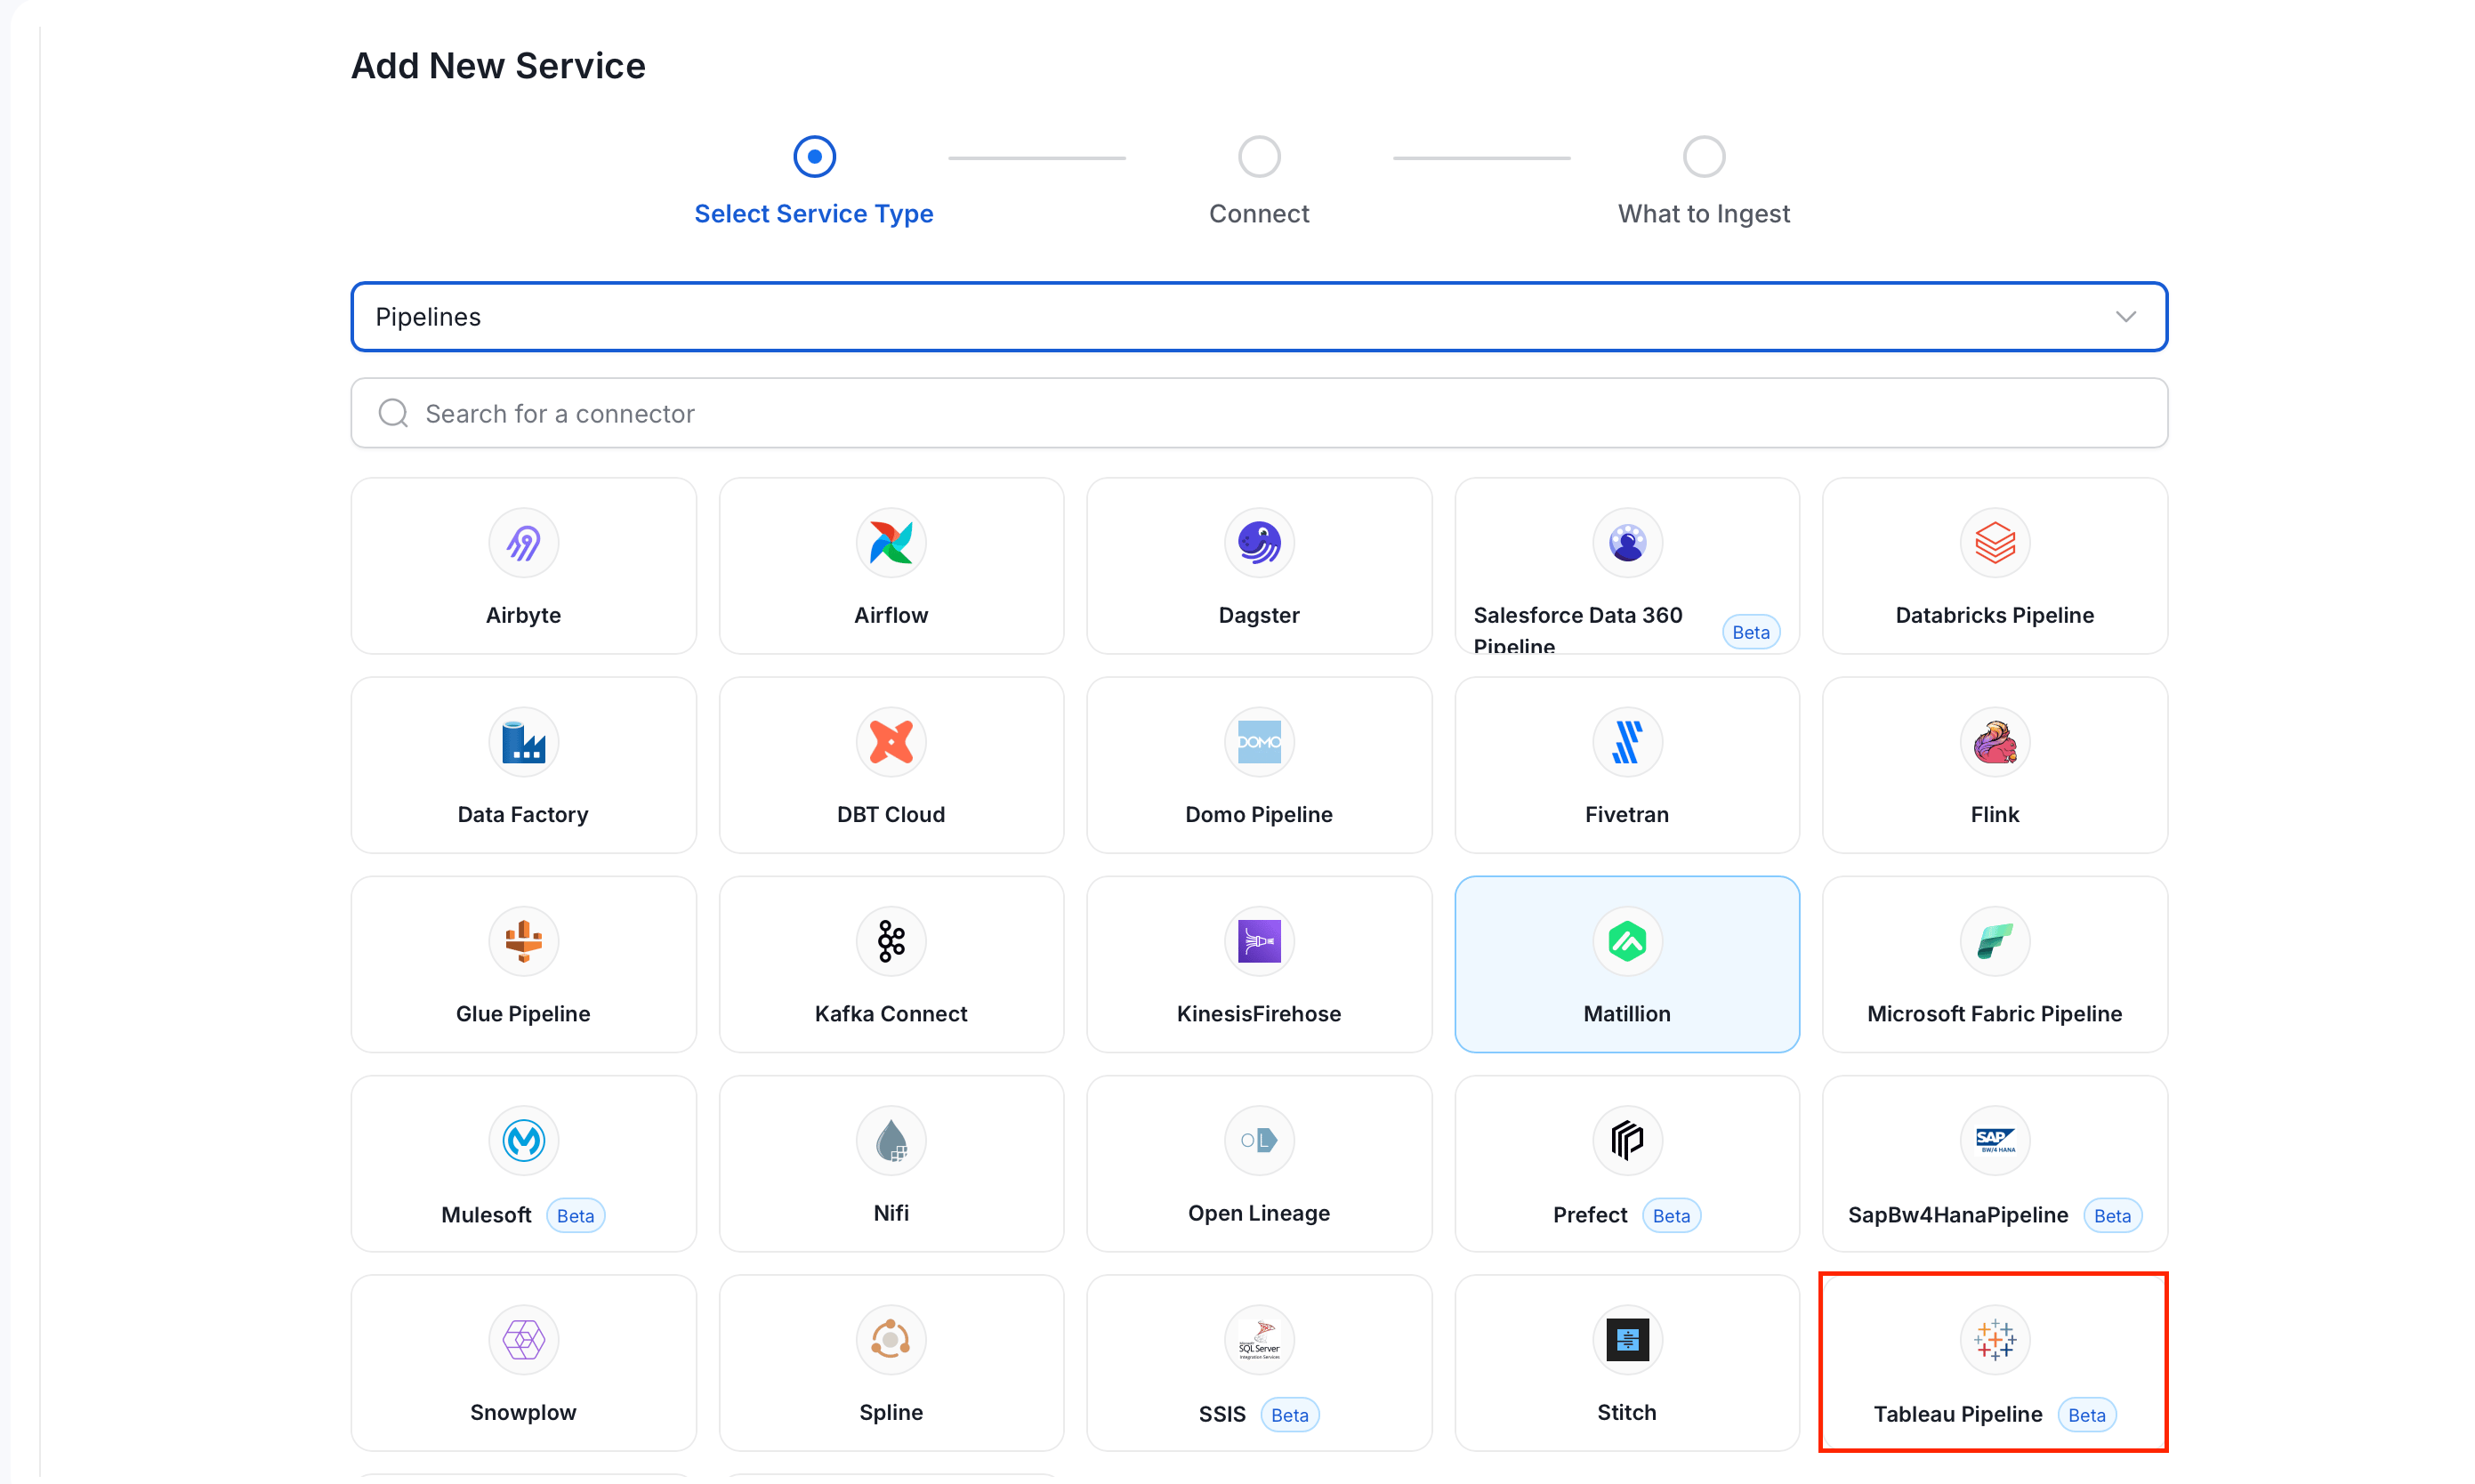
Step 3: Add Service Name and Description
- Enter a unique, descriptive Service Name. OpenMetadata identifies services by their service name. Enter a name that distinguishes this deployment from other Tableau Pipeline services you’re ingesting metadata from.
- Optional: Enter a Description for the service.
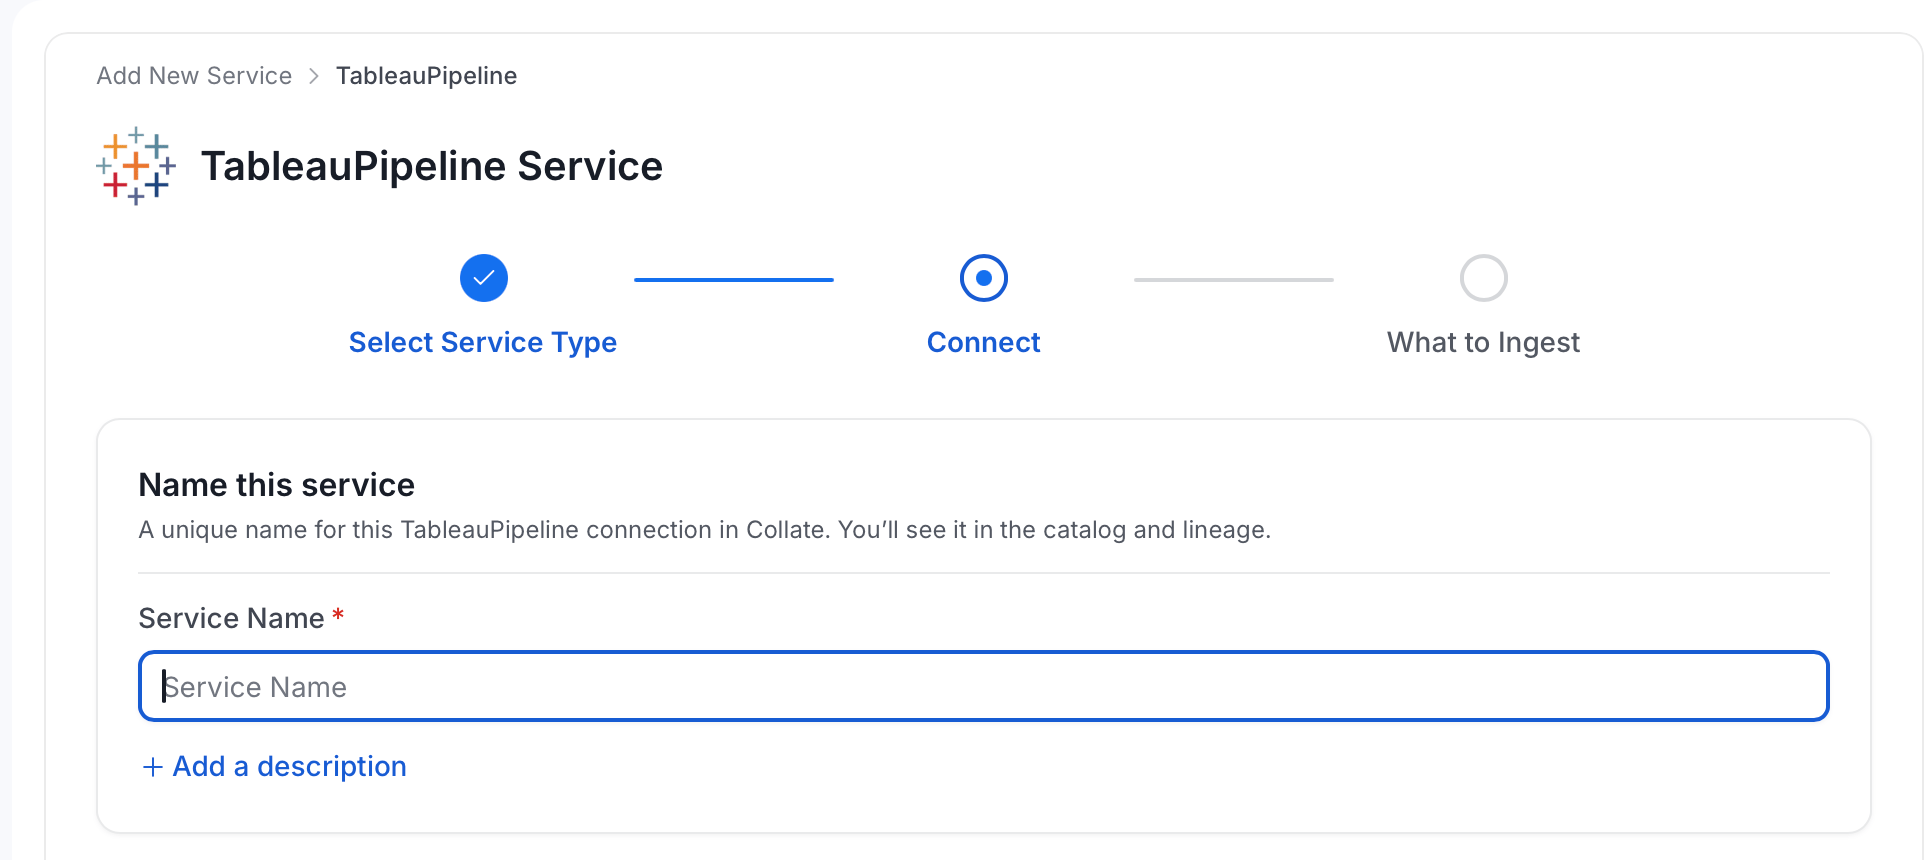
The service name can’t be changed after it’s set.
Step 4: Configure Connection Options
Specify your source credentials and verify the connection.Enter Connection Details
Enter the connection details for Tableau Pipeline. The inline help panel in the UI describes each field. The form groups fields into Connection, Authentication, Scope & Options, and Advanced Config sections.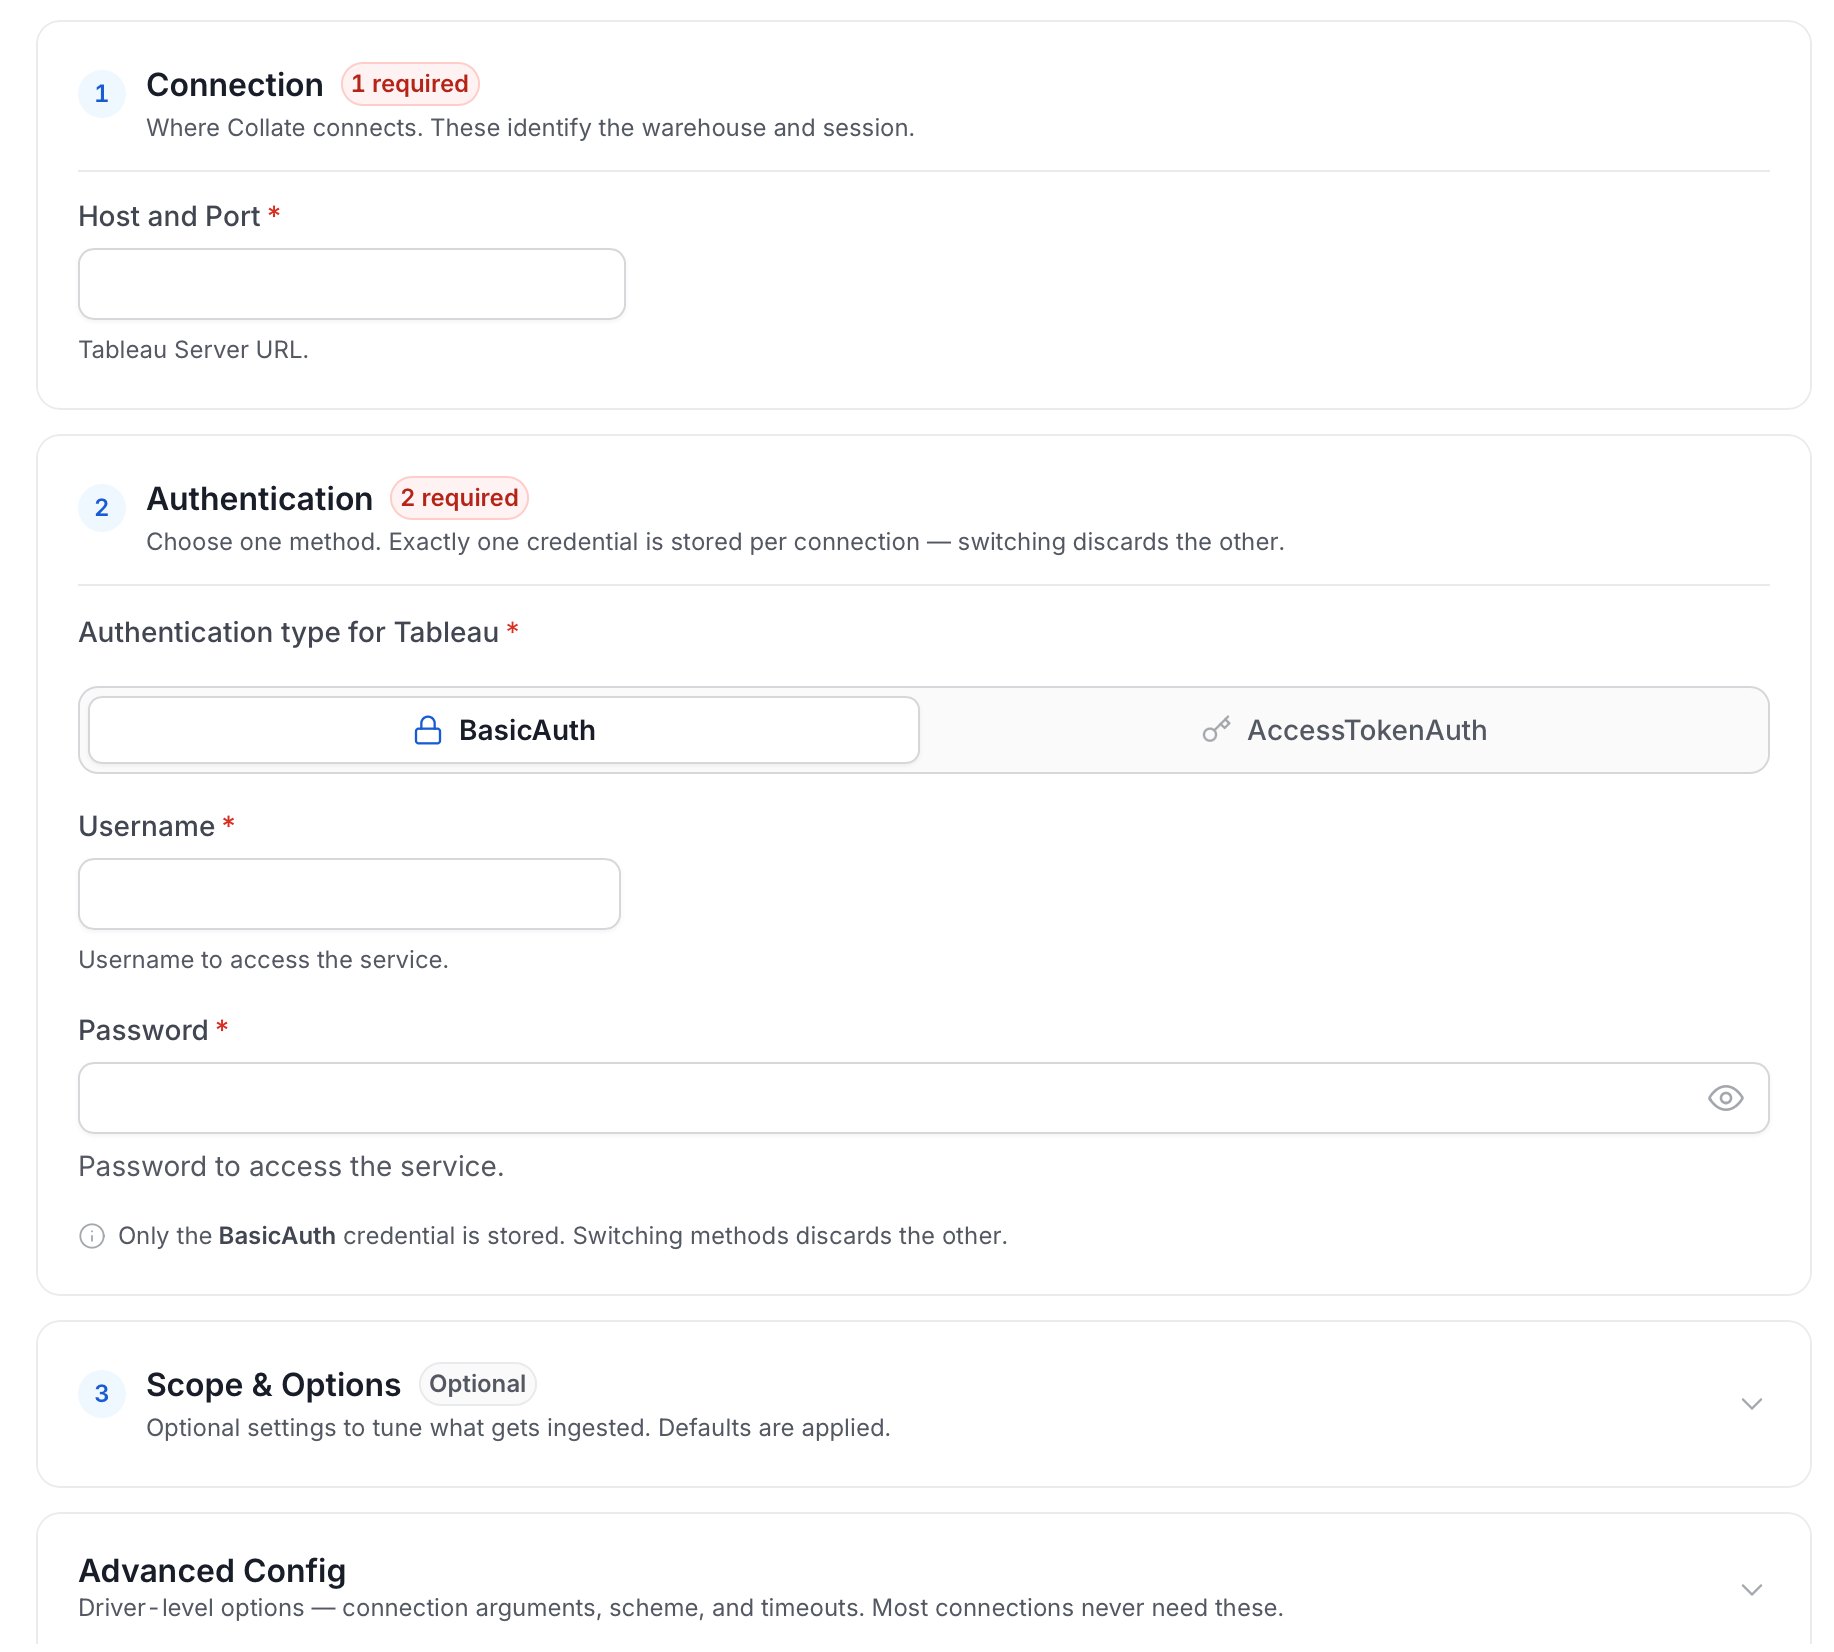
- Host and Port (required): Tableau Server URL.
- Authentication type for Tableau (required): Choose one method. OpenMetadata stores only the credential for the method you select, and switching methods discards the other.
- BasicAuth: Enter the Username and Password used to sign in to Tableau.
- AccessTokenAuth: Enter the Personal Access Token Name and Personal Access Token Secret. For more information, see Personal Access Tokens.
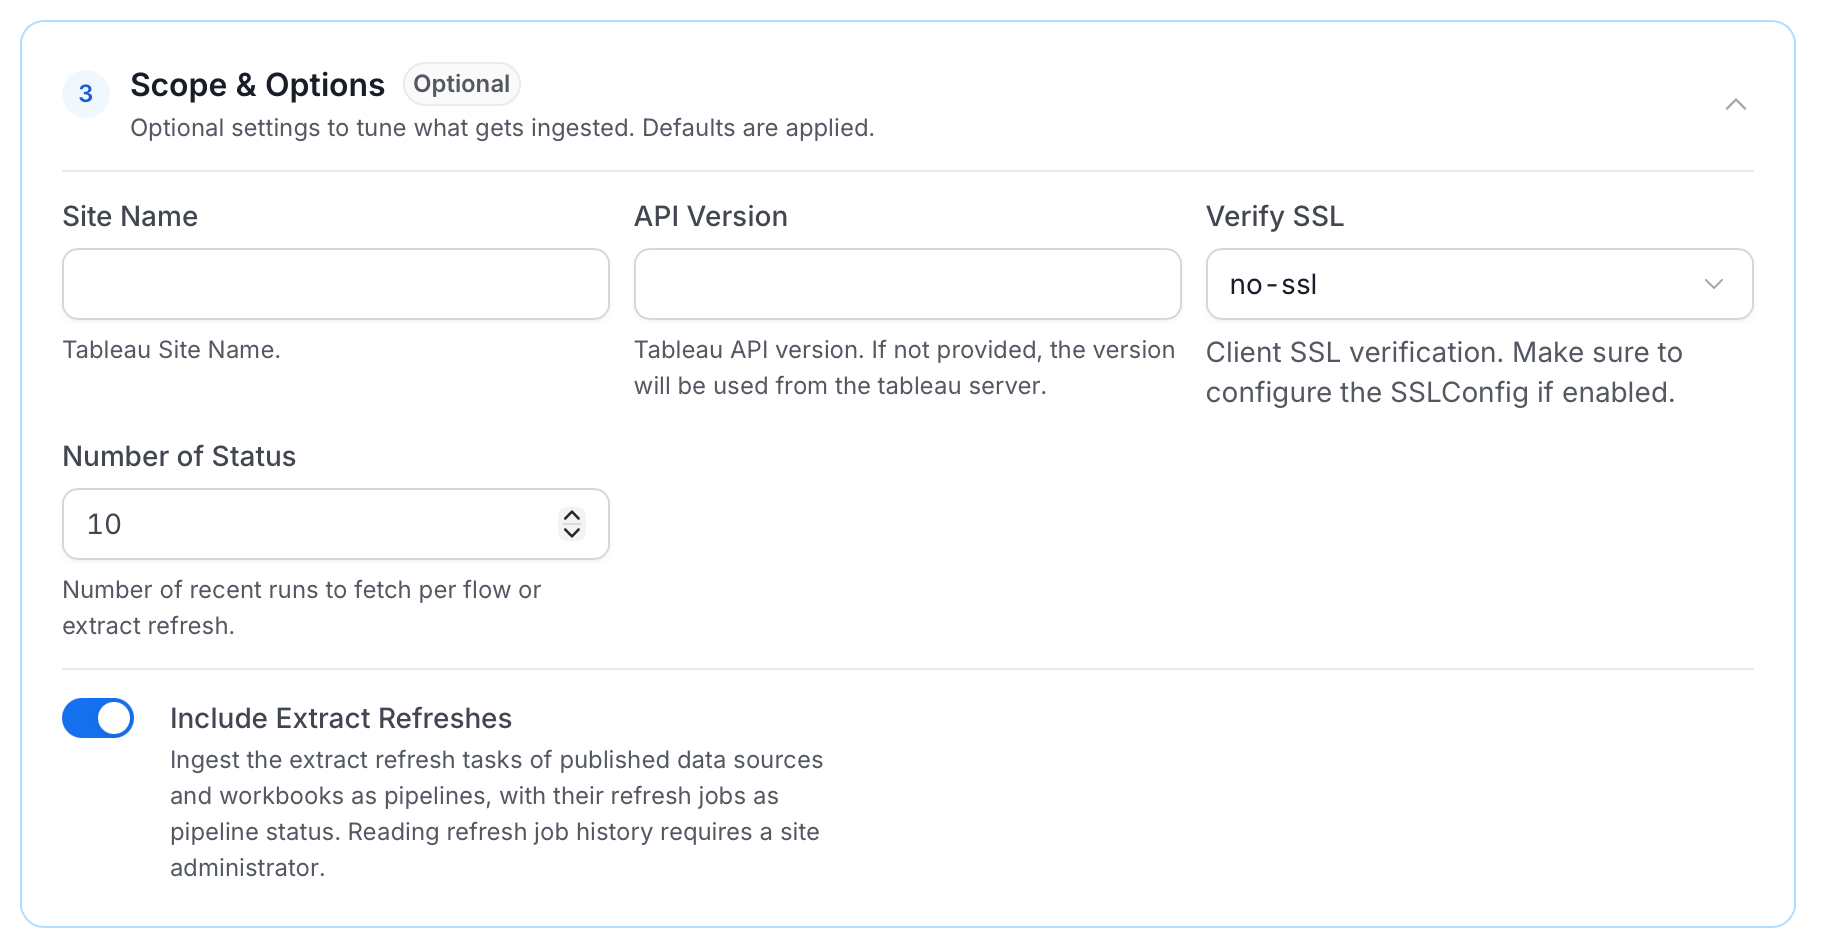
- Site Name (optional): The Tableau site to ingest. Leave blank for the default site.
- API Version (optional): Tableau REST API version. If not provided, OpenMetadata uses the version reported by the Tableau server.
- Verify SSL (optional): Client SSL verification mode. The default is
no-ssl. Configure SSL Config under Advanced Config when you select a mode that validates certificates. - Number of Status (optional, default
10, from1to100): Number of recent runs to fetch per flow or extract refresh. - Include Extract Refreshes (optional, on by default): Ingest the extract refresh tasks of published data sources and workbooks as pipelines, with their refresh jobs as pipeline status. Reading refresh job history requires a site administrator.
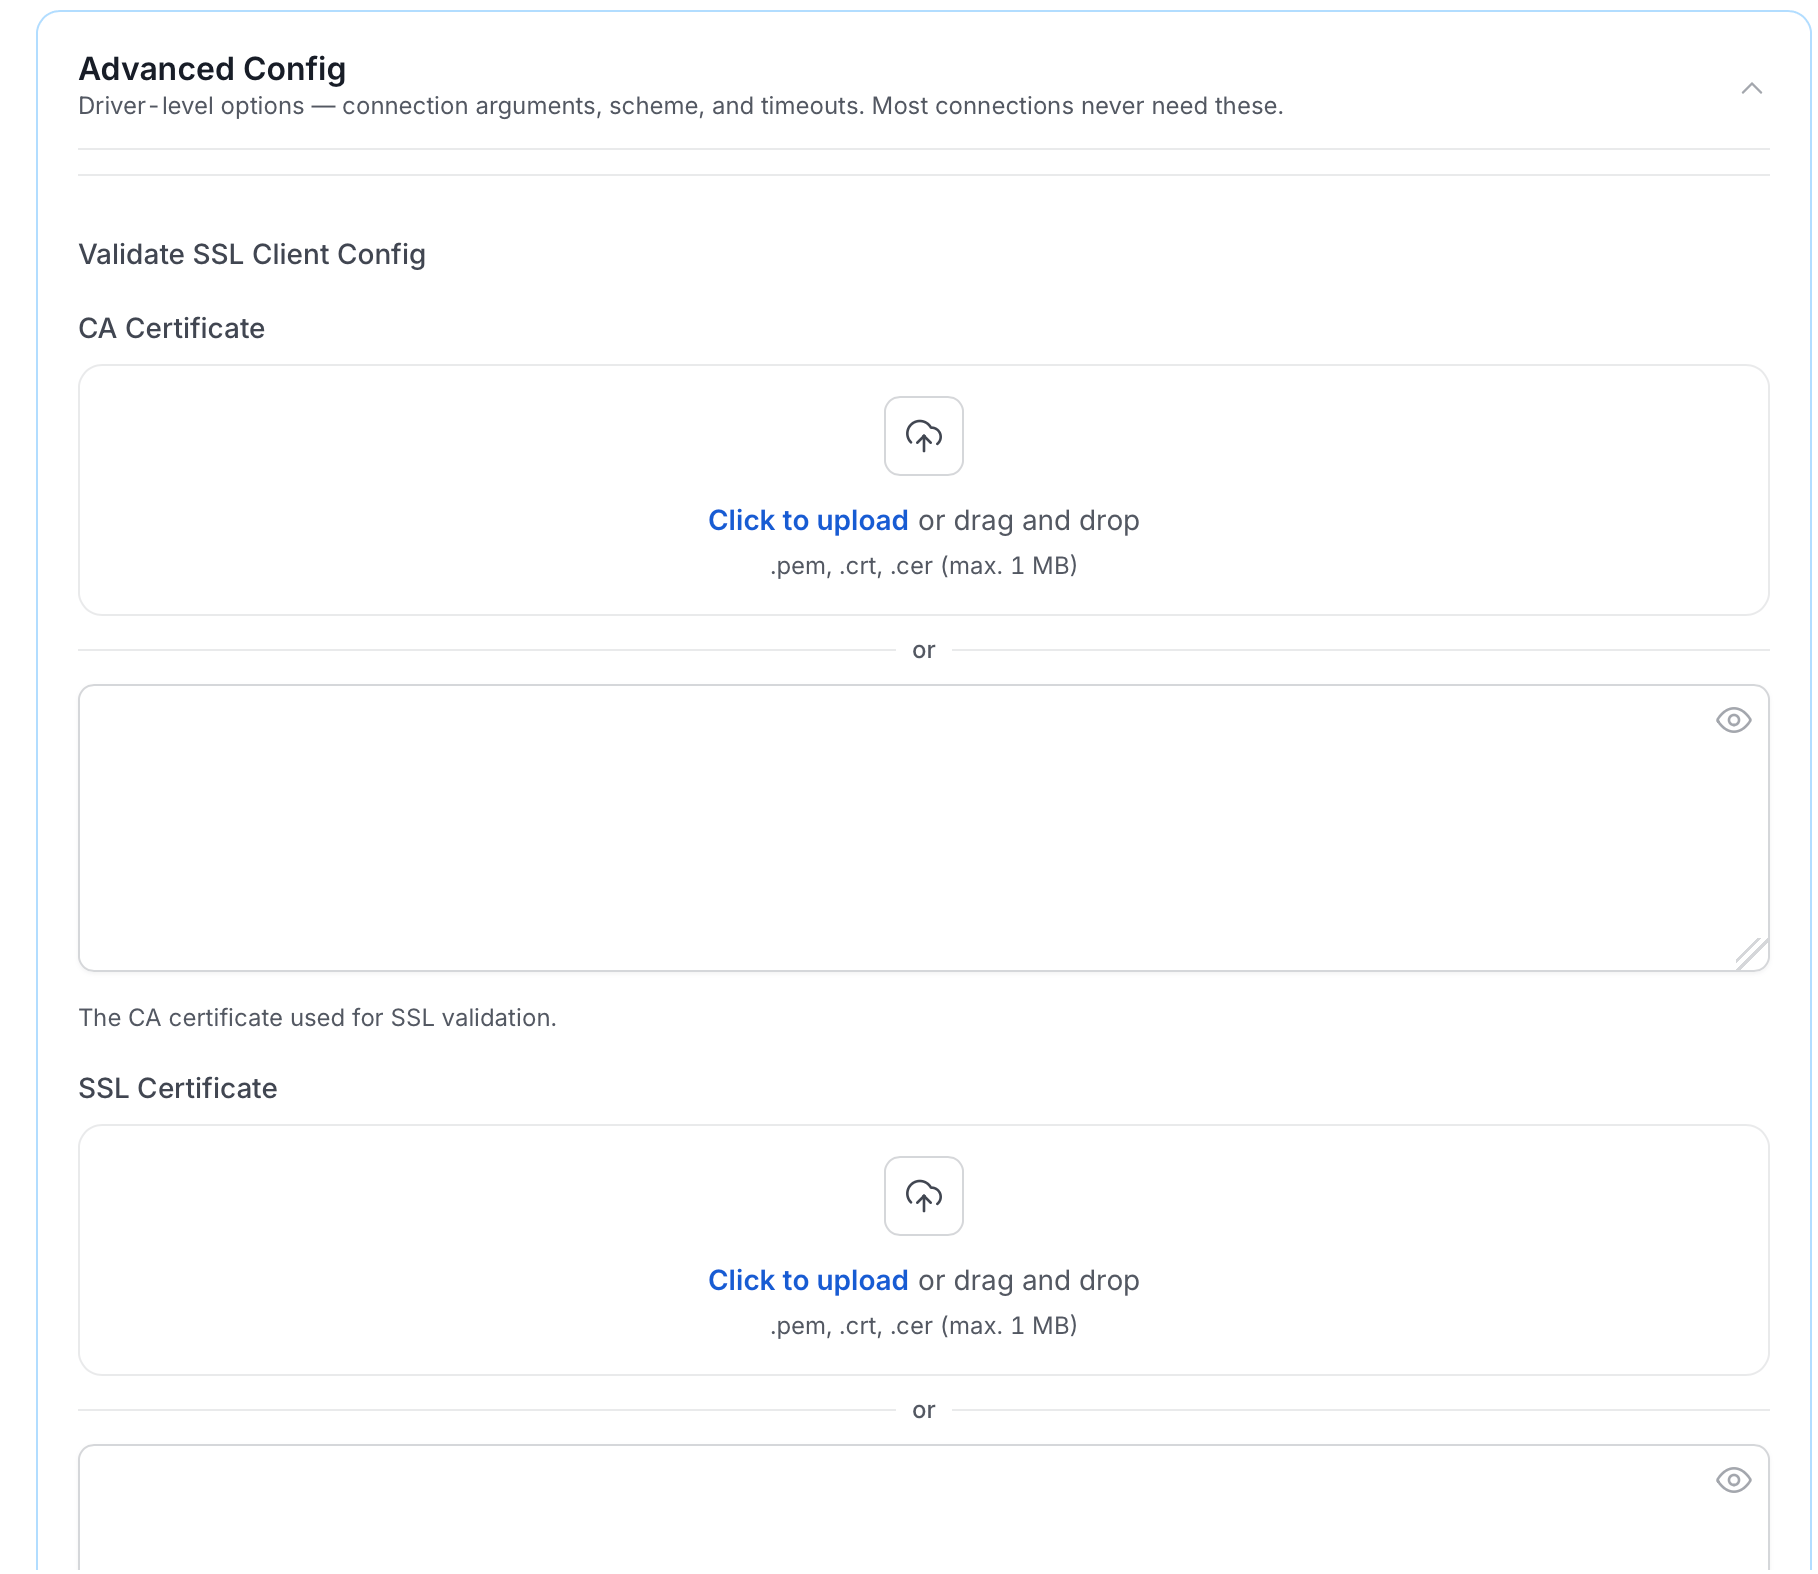
- CA Certificate: The CA certificate used for SSL validation. Upload a
.pem,.crt, or.cerfile (maximum 1 MB), or paste the contents. - SSL Certificate: The client certificate, for mutual TLS.
- SSL Key: The private key for the client certificate, for mutual TLS.
Test Connection
After you add the credentials, click Test Connection, then click Save.
Step 5: Configure Ingestion Options
In the What to Ingest step, use filter patterns to control which assets OpenMetadata ingests from your Tableau Pipeline service. Filter patterns use regular expressions applied to pipeline names.How Filter Patterns Work
- Include: Add one or more comma-separated regular expressions. OpenMetadata ingests only assets whose names match at least one expression. Leave blank to include all assets.
- Exclude: Add one or more comma-separated regular expressions. OpenMetadata skips any asset whose name matches an expression. Leave blank to exclude nothing.
- contains: matches any name containing the value. For example,
salesmatchesmy_sales_dataandsales_2024. - starts with: matches names beginning with the value. For example,
prod_matchesprod_dbandprod_schema. - ends with: matches names ending with the value. For example,
_rawmatchesevents_rawandlogs_raw. - is exactly: matches the exact name only. For example,
analyticsmatches onlyanalytics. - matches regex: matches names using a regular expression. For example,
^prod_.*_v\d+$matchesprod_events_v1.
Filter Options
The Pipeline section includes the following filter options:- Pipeline: Controls which Prep flows and extract refresh pipelines OpenMetadata ingests from Tableau.
- Scan Mode: Choose between the following scan modes:
- Scan all: Ingests every asset of that type the connector can access. This is the default.
- Only specific: Enables include rules so only assets matching at least one rule are ingested.
- Always exclude: Add permanent exclusion rules (shown in red). Assets matching these rules are never ingested, regardless of include rules.
- Preview: Shows a real-time summary of what will be in scope based on your current rules.
- Include rules (available only in Only specific mode): Click + Add to define a rule. Added rules appear as chips. An asset is included if it matches any rule.
Step 6: Create & Deploy
Click Create & Deploy to deploy the agent and start the first metadata ingestion run. OpenMetadata saves the service configuration and immediately begins pulling metadata from the source. To monitor ingestion progress or view the service you just added, go to Settings > Services and select your service.Configure Metadata Agent and Schedule Ingestion
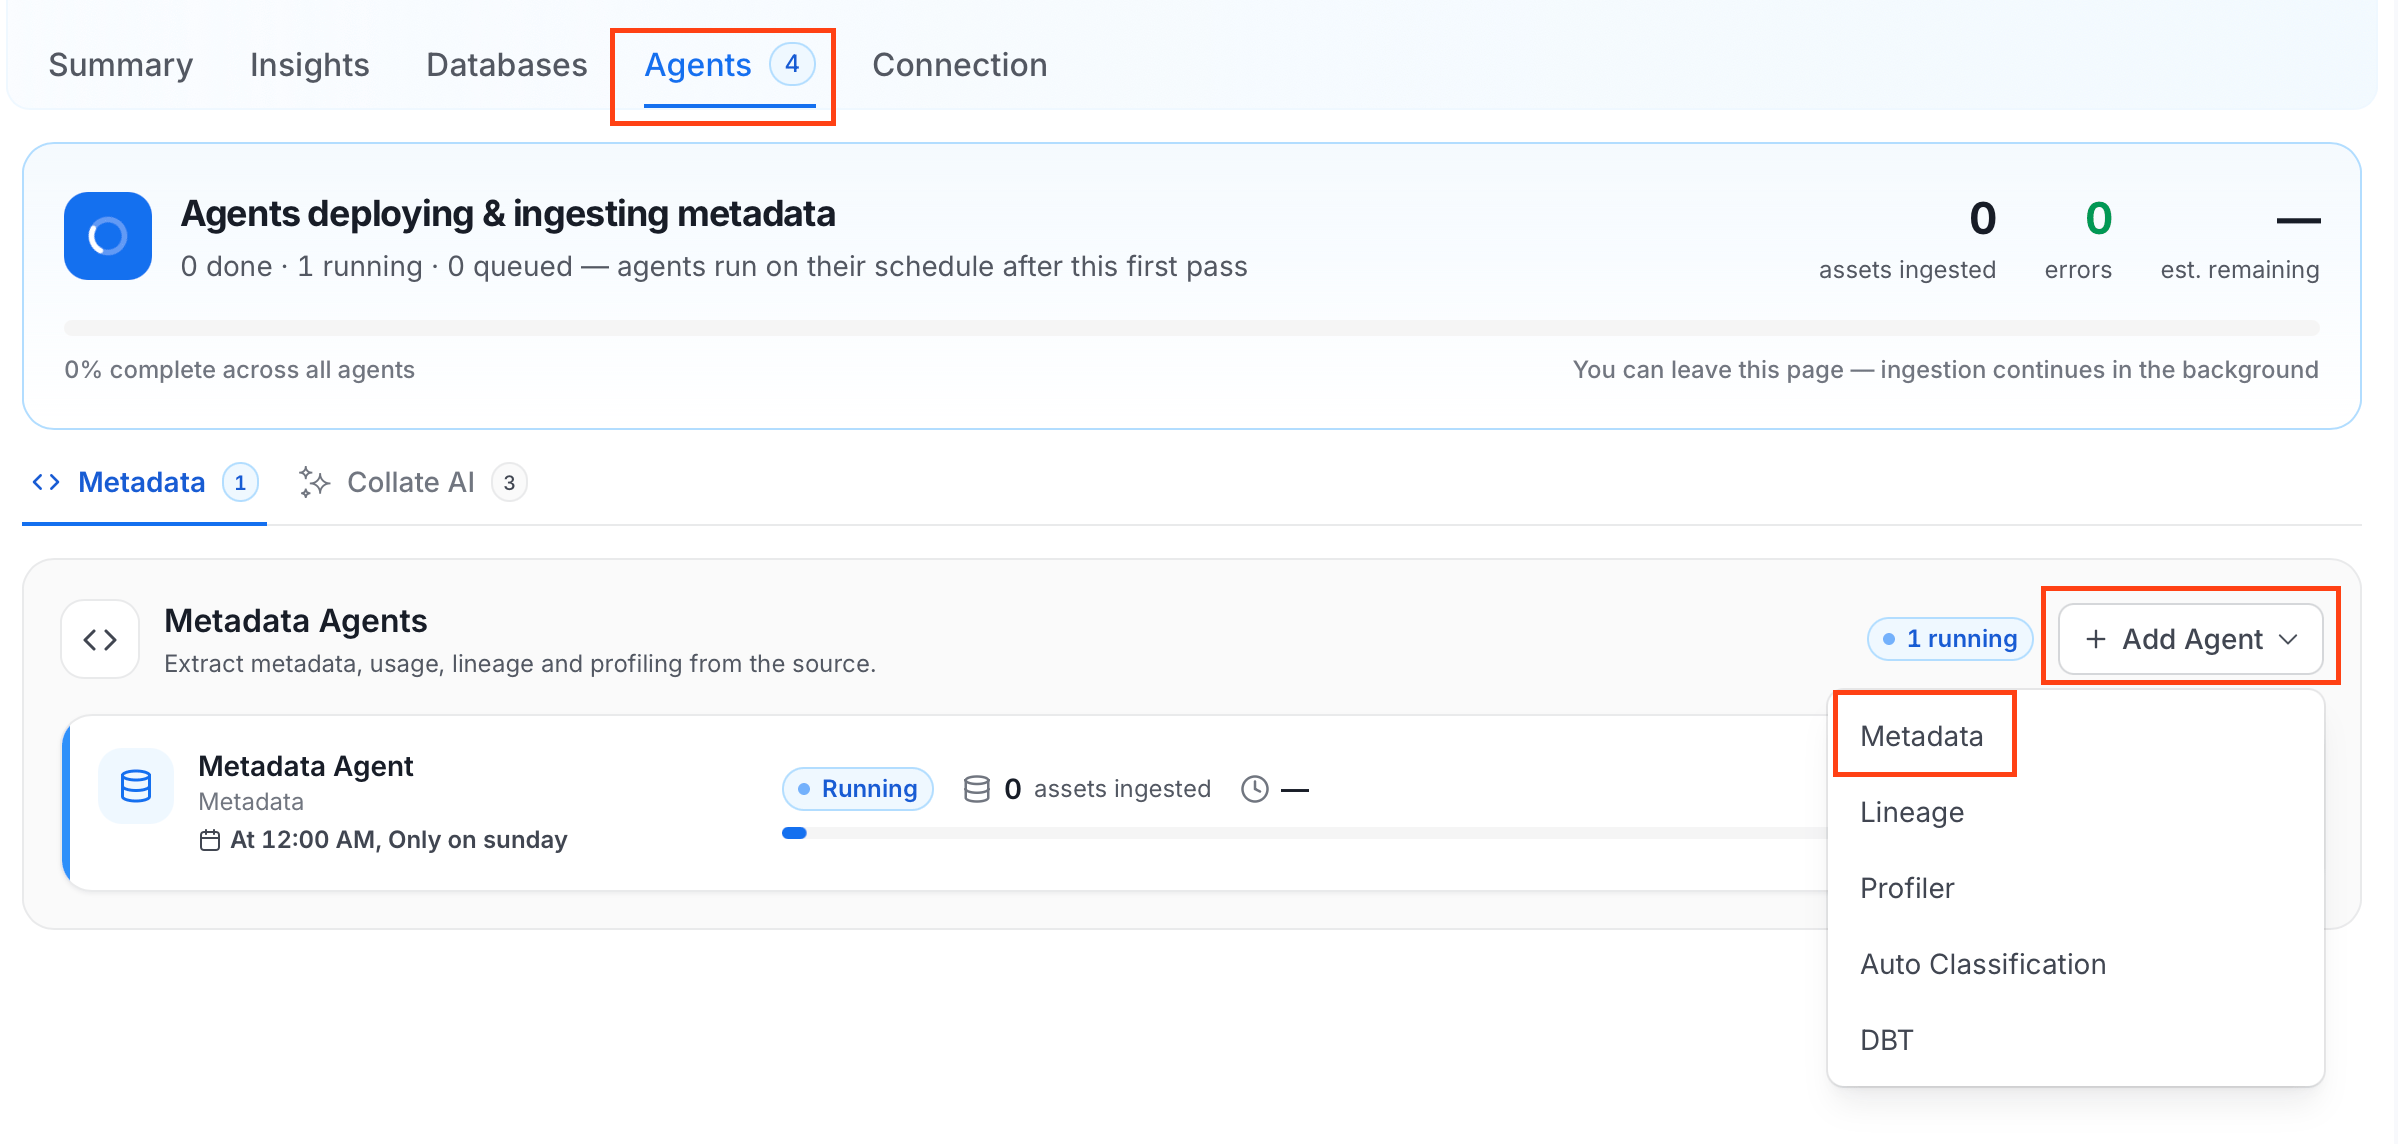
The Metadata Agent extracts pipelines, tasks, and other structural metadata from your source and keeps your OpenMetadata catalog in sync. It powers discovery, lineage, and governance across your data assets. When you click Create & Deploy, OpenMetadata automatically deploys a Metadata Agent for this service and triggers the first ingestion run. View its status and run history from the Agents tab on the service detail page. To configure the additional Metadata Agent and schedule ingestion, follow these steps:-
Navigate to Settings > Services and select the service type.
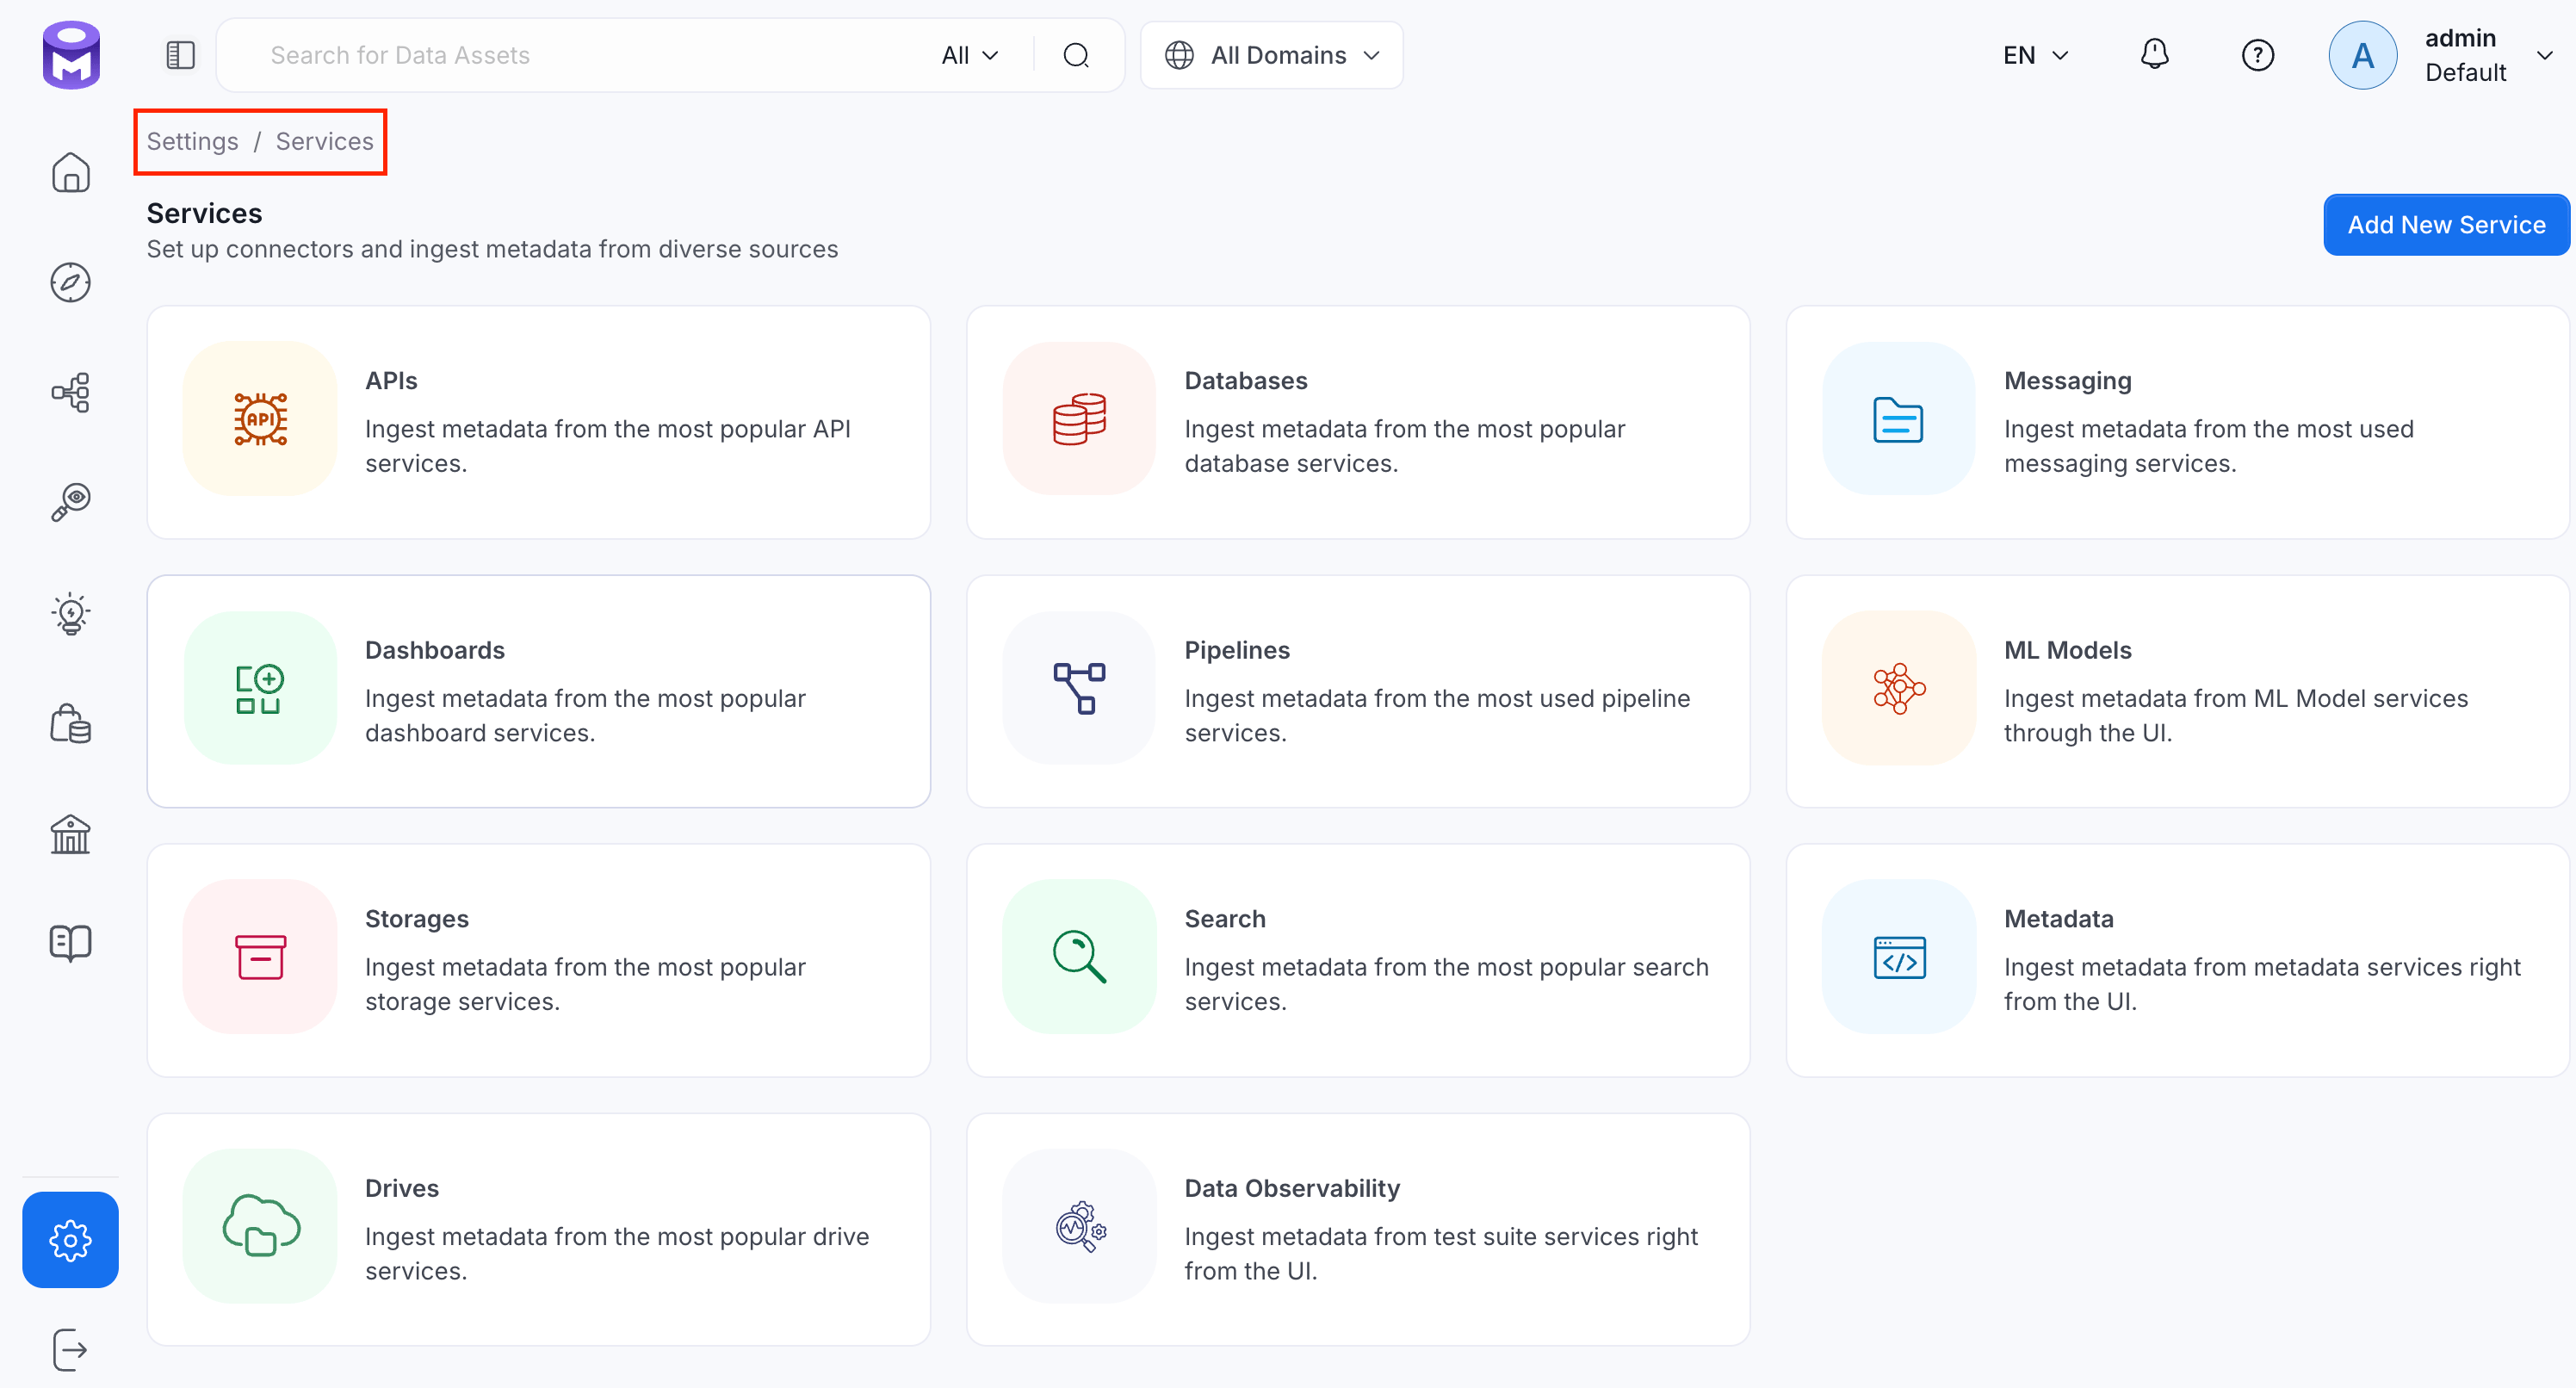
- Click the service you have added.
-
Select the Agents tab and click Add Agent > Metadata.
-
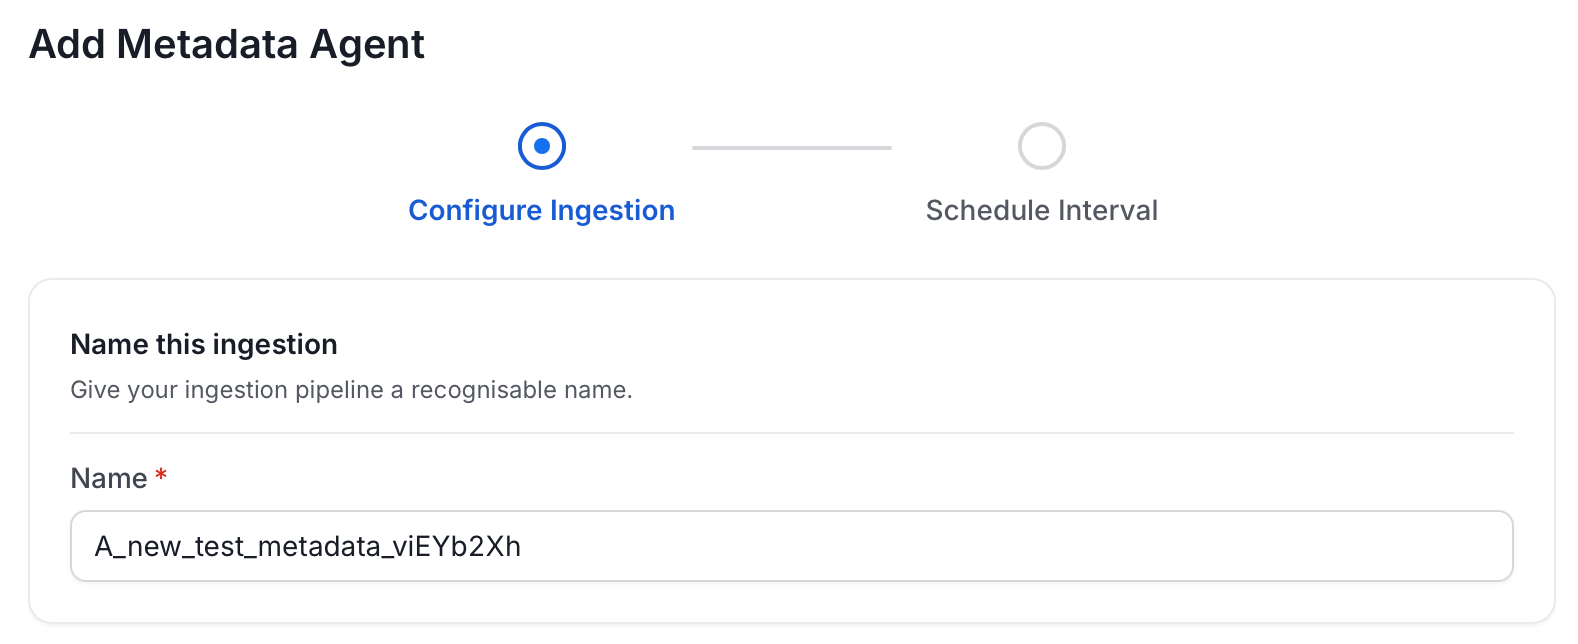
On the Configure Ingestion page, do the following and click Next.
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.
-
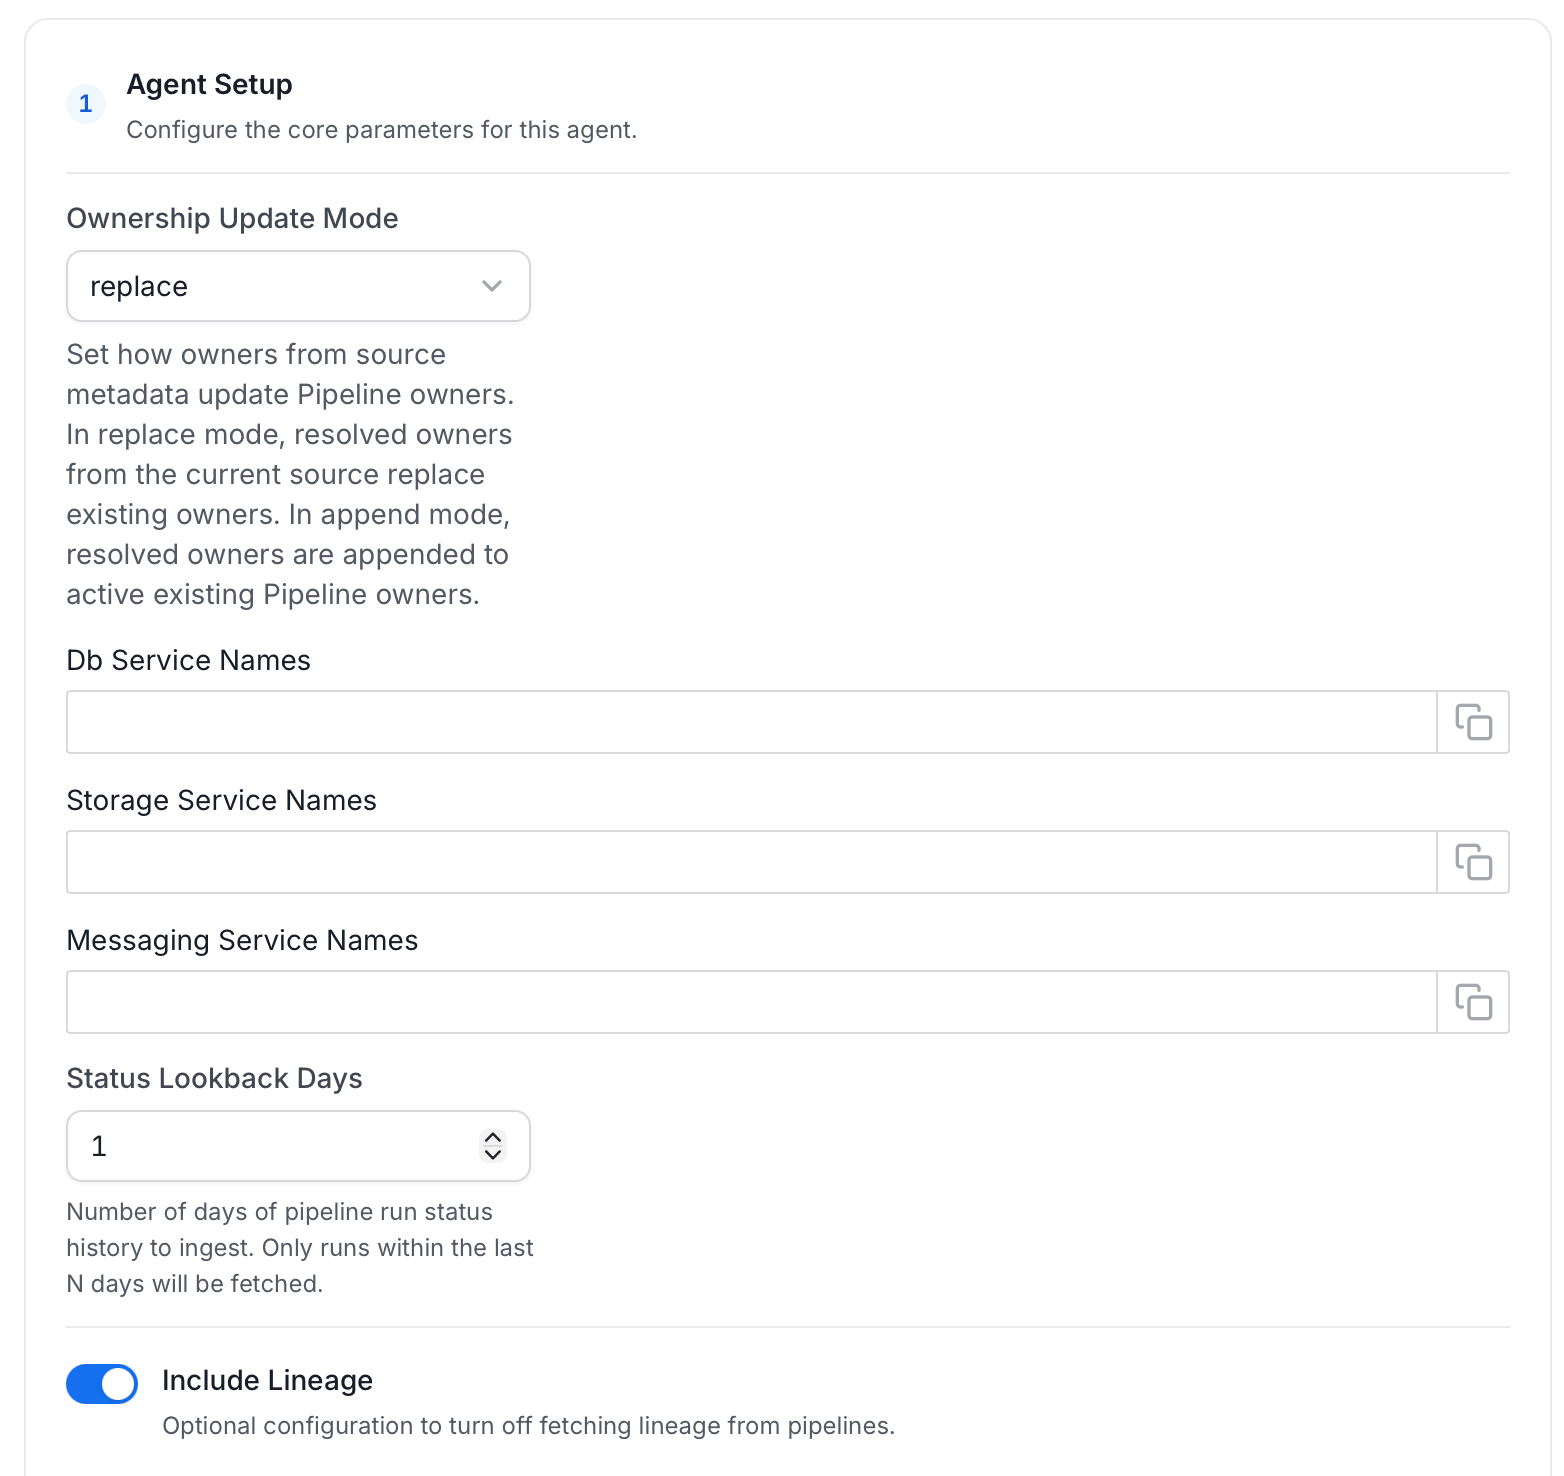
Agent Setup: Configure the core parameters for this agent. The following fields are available:
-
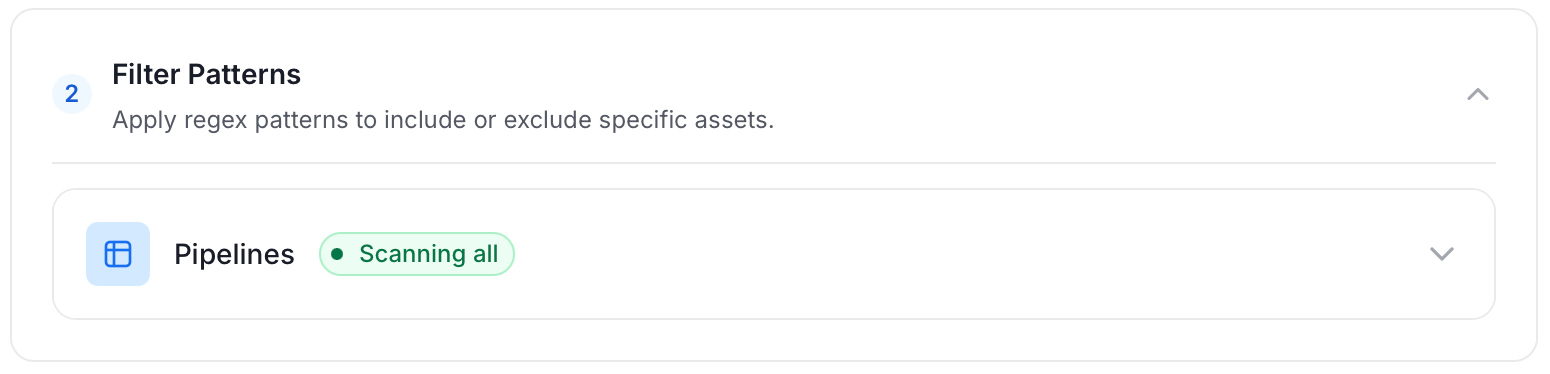
Filter Patterns: Apply include or exclude rules to scope which pipelines this agent ingests. These follow the same filter options described in Step 5: Configure Ingestion Options.
-
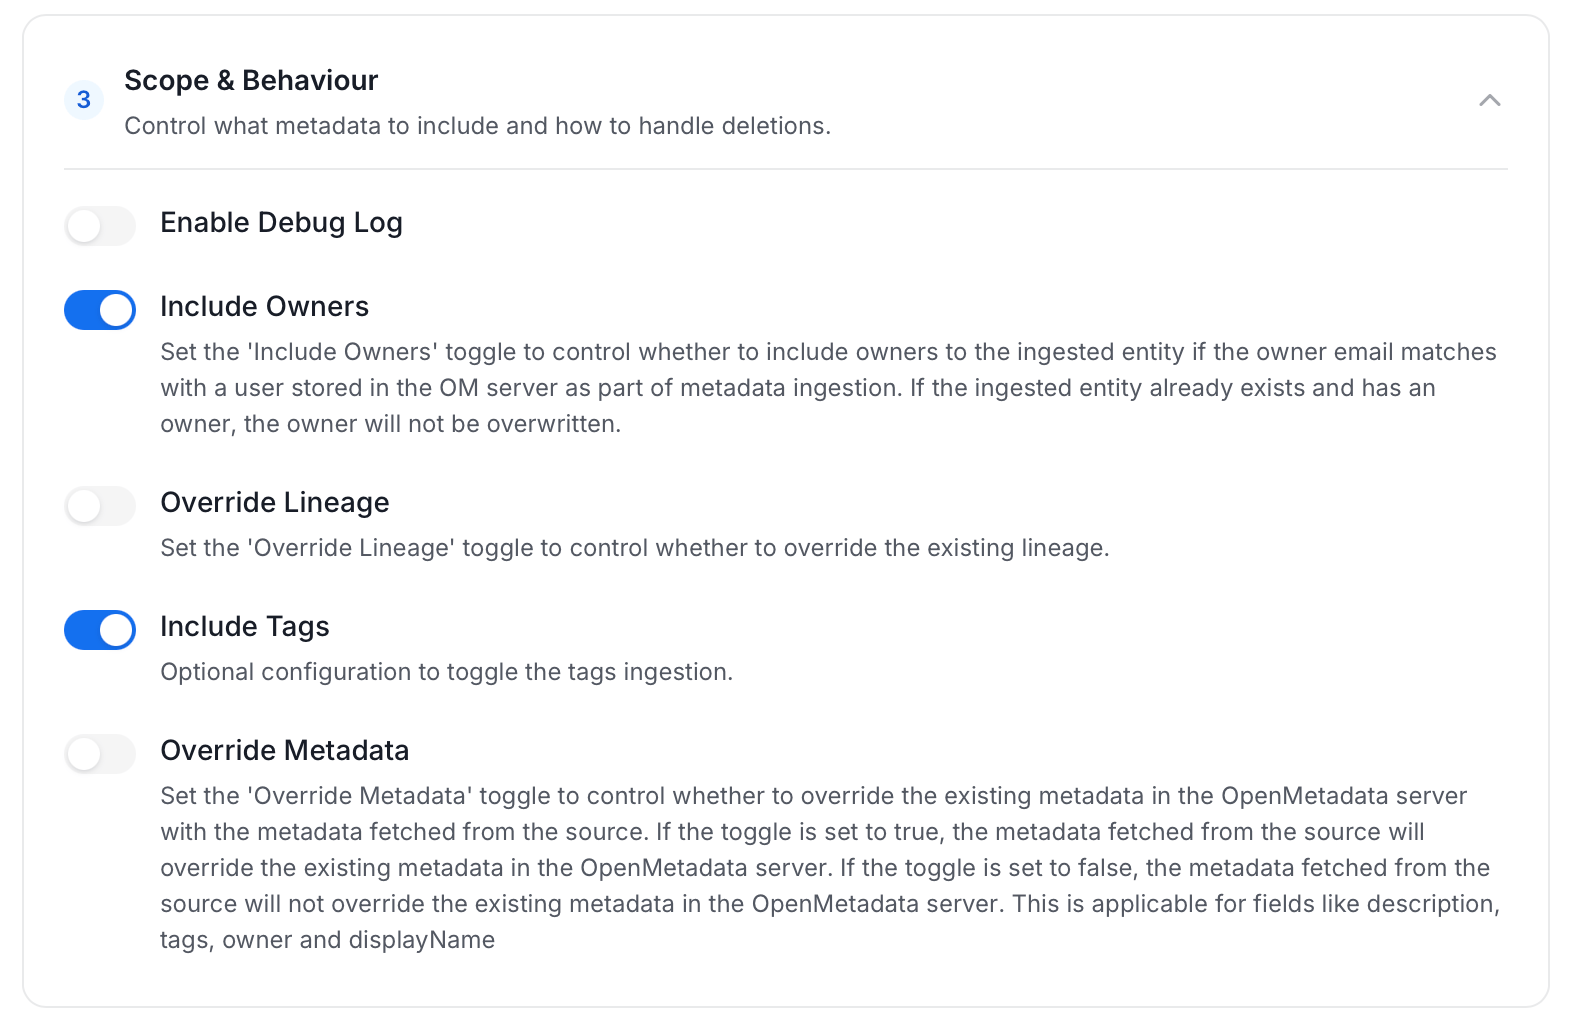
Scope & Behaviour: Control what metadata to include and how to handle deletions. Toggle each option on or off based on your needs:
-
Name this Ingestion: Enter a unique recognizable name for this ingestion pipeline.
-
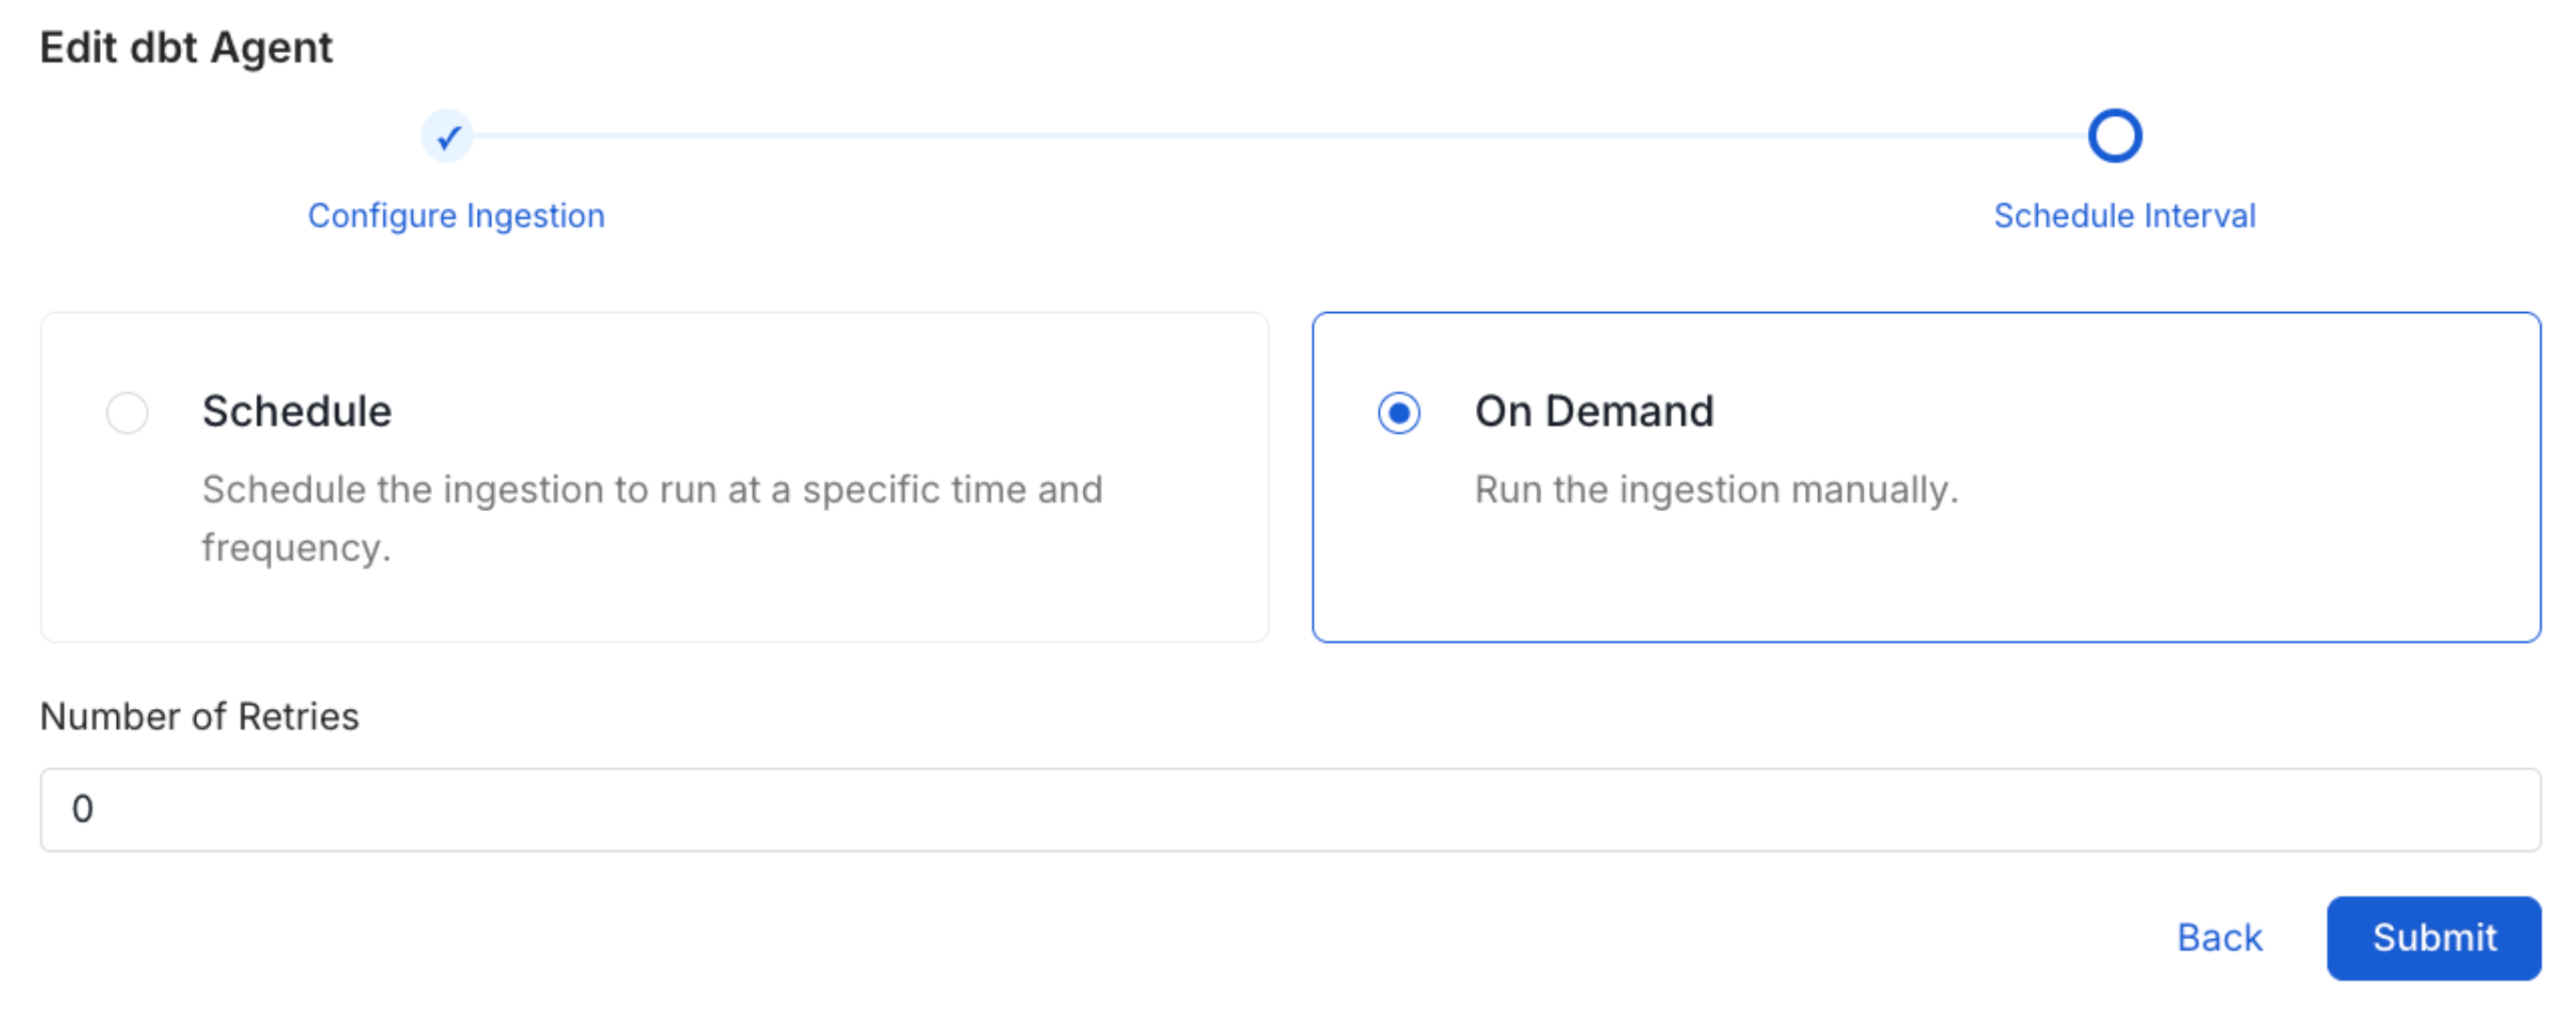
On the Schedule Interval page, set when the agent runs:
- Schedule: Choose a preset interval (Hourly, Daily, Weekly, Monthly) or enter a custom cron expression.
- On-Demand: No automatic schedule; trigger the agent manually when needed.
- Click Add to deploy the agent.
Related
Usage Workflow
Learn more about how to configure the Usage Workflow to ingest Query information from the UI.
Lineage Workflow
Learn more about how to configure the Lineage from the UI.
Profiler Workflow
Learn more about how to configure the Data Profiler from the UI.
Data Quality Workflow
Learn more about how to configure the Data Quality tests from the UI.
dbt Integration
Learn more about how to ingest dbt models’ definitions and their lineage.