
Querying with SPARQL
SPARQL is to a graph what SQL is to tables. If you can write aSELECT with joins, you can write SPARQL — the shape is SELECT ?vars WHERE { pattern } where the pattern is a set of subject–predicate–object triples that share variables.
Where to Run Queries
Ontology-scoped SPARQL reads one version of that ontology: the active release by default, or the working draft (
scope=draft) for users with edit permission. It works with RDF storage off and cannot reach other assets or external datasets. Catalog-wide SPARQL in the Playground runs against the triple store and is admin-only. The MCP tool is the exception. Non-administrators who hold ExecuteSparqlQuery can run it through a restricted profile. The profile allows only SELECT queries with JSON output and no inference. It rejects FROM, GRAPH, SERVICE, and CALL, and it bounds result size and runtime. For more information, see AI Agents.
Named Graphs
Always scope instance-data queries to the knowledge graph. Ontology and shapes triples live elsewhere, so an unscoped?s ?p ?o returns schema noise.
Prefixes
The console pre-populates these; include them in API calls yourself.The Vocabulary You Will Use Most
Entity IRIs followhttps://open-metadata.org/entity/{entityType}/{uuid}.
Limits
Every read runs behind an admission guard:
Writes (
INSERT, DELETE, DROP, LOAD, CLEAR, CREATE) are rejected on the read endpoints. POST /api/v1/rdf/sparql/update exists for admins, but see the warning below.
Federation (SERVICE clauses to external endpoints) is disabled by default. When federation is enabled, target URIs must appear verbatim in an allowlist, and trailing slashes matter. A SERVICE clause hidden inside EXISTS is refused too.
Ontology-scoped queries run in an isolated process with their own memory limit. If an ontology is too large to load, the query fails with an error that says so.
Cookbook
Discovery
Governance
Lineage
prov:wasDerivedFrom+ is a property path — SPARQL’s transitive traversal operator. It is the single feature that makes graph queries worth the switch, and it has no clean SQL equivalent. If you enable the transitive lineage closure inference rule, the closure is materialized and you can drop the +.The Ontology, Applied
Structure
Calling the API
json (default), xml, csv, tsv for SELECT/ASK; turtle, jsonld, ntriples, rdfxml for CONSTRUCT/DESCRIBE.
RDF 1.2 Support
SPARQL queries can use RDF 1.2 features. Both the admin endpoint and the MCPsparql_query tool accept them. Non-administrators keep the restricted profile: SELECT queries with JSON output, and no GRAPH clause.
- SPARQL 1.2 syntax:
VERSION "1.2", theTRIPLE()andLANGDIR()functions, and<<( s p o )>>triple-term patterns. - Triple terms: a triple term can bind to a result variable, including
rdf:reifiesstatements and blank nodes nested inside a triple. - Directional literals: language-tagged strings with a base direction, such as
"قطة"@ar--rtl.
Results in JSON
JSON results follow the SPARQL 1.2 Query Results JSON format:- A triple binding has
typeset totriple. Itsvalueis an object with recursivesubject,predicate, andobjectterms, instead of a string. - A directional literal carries an
its:dirfield set toltrorrtl, next toxml:lang. - Existing bindings for IRIs, literals, and blank nodes are unchanged.
<<( <subject> <predicate> "قطة"@ar--rtl )>>.
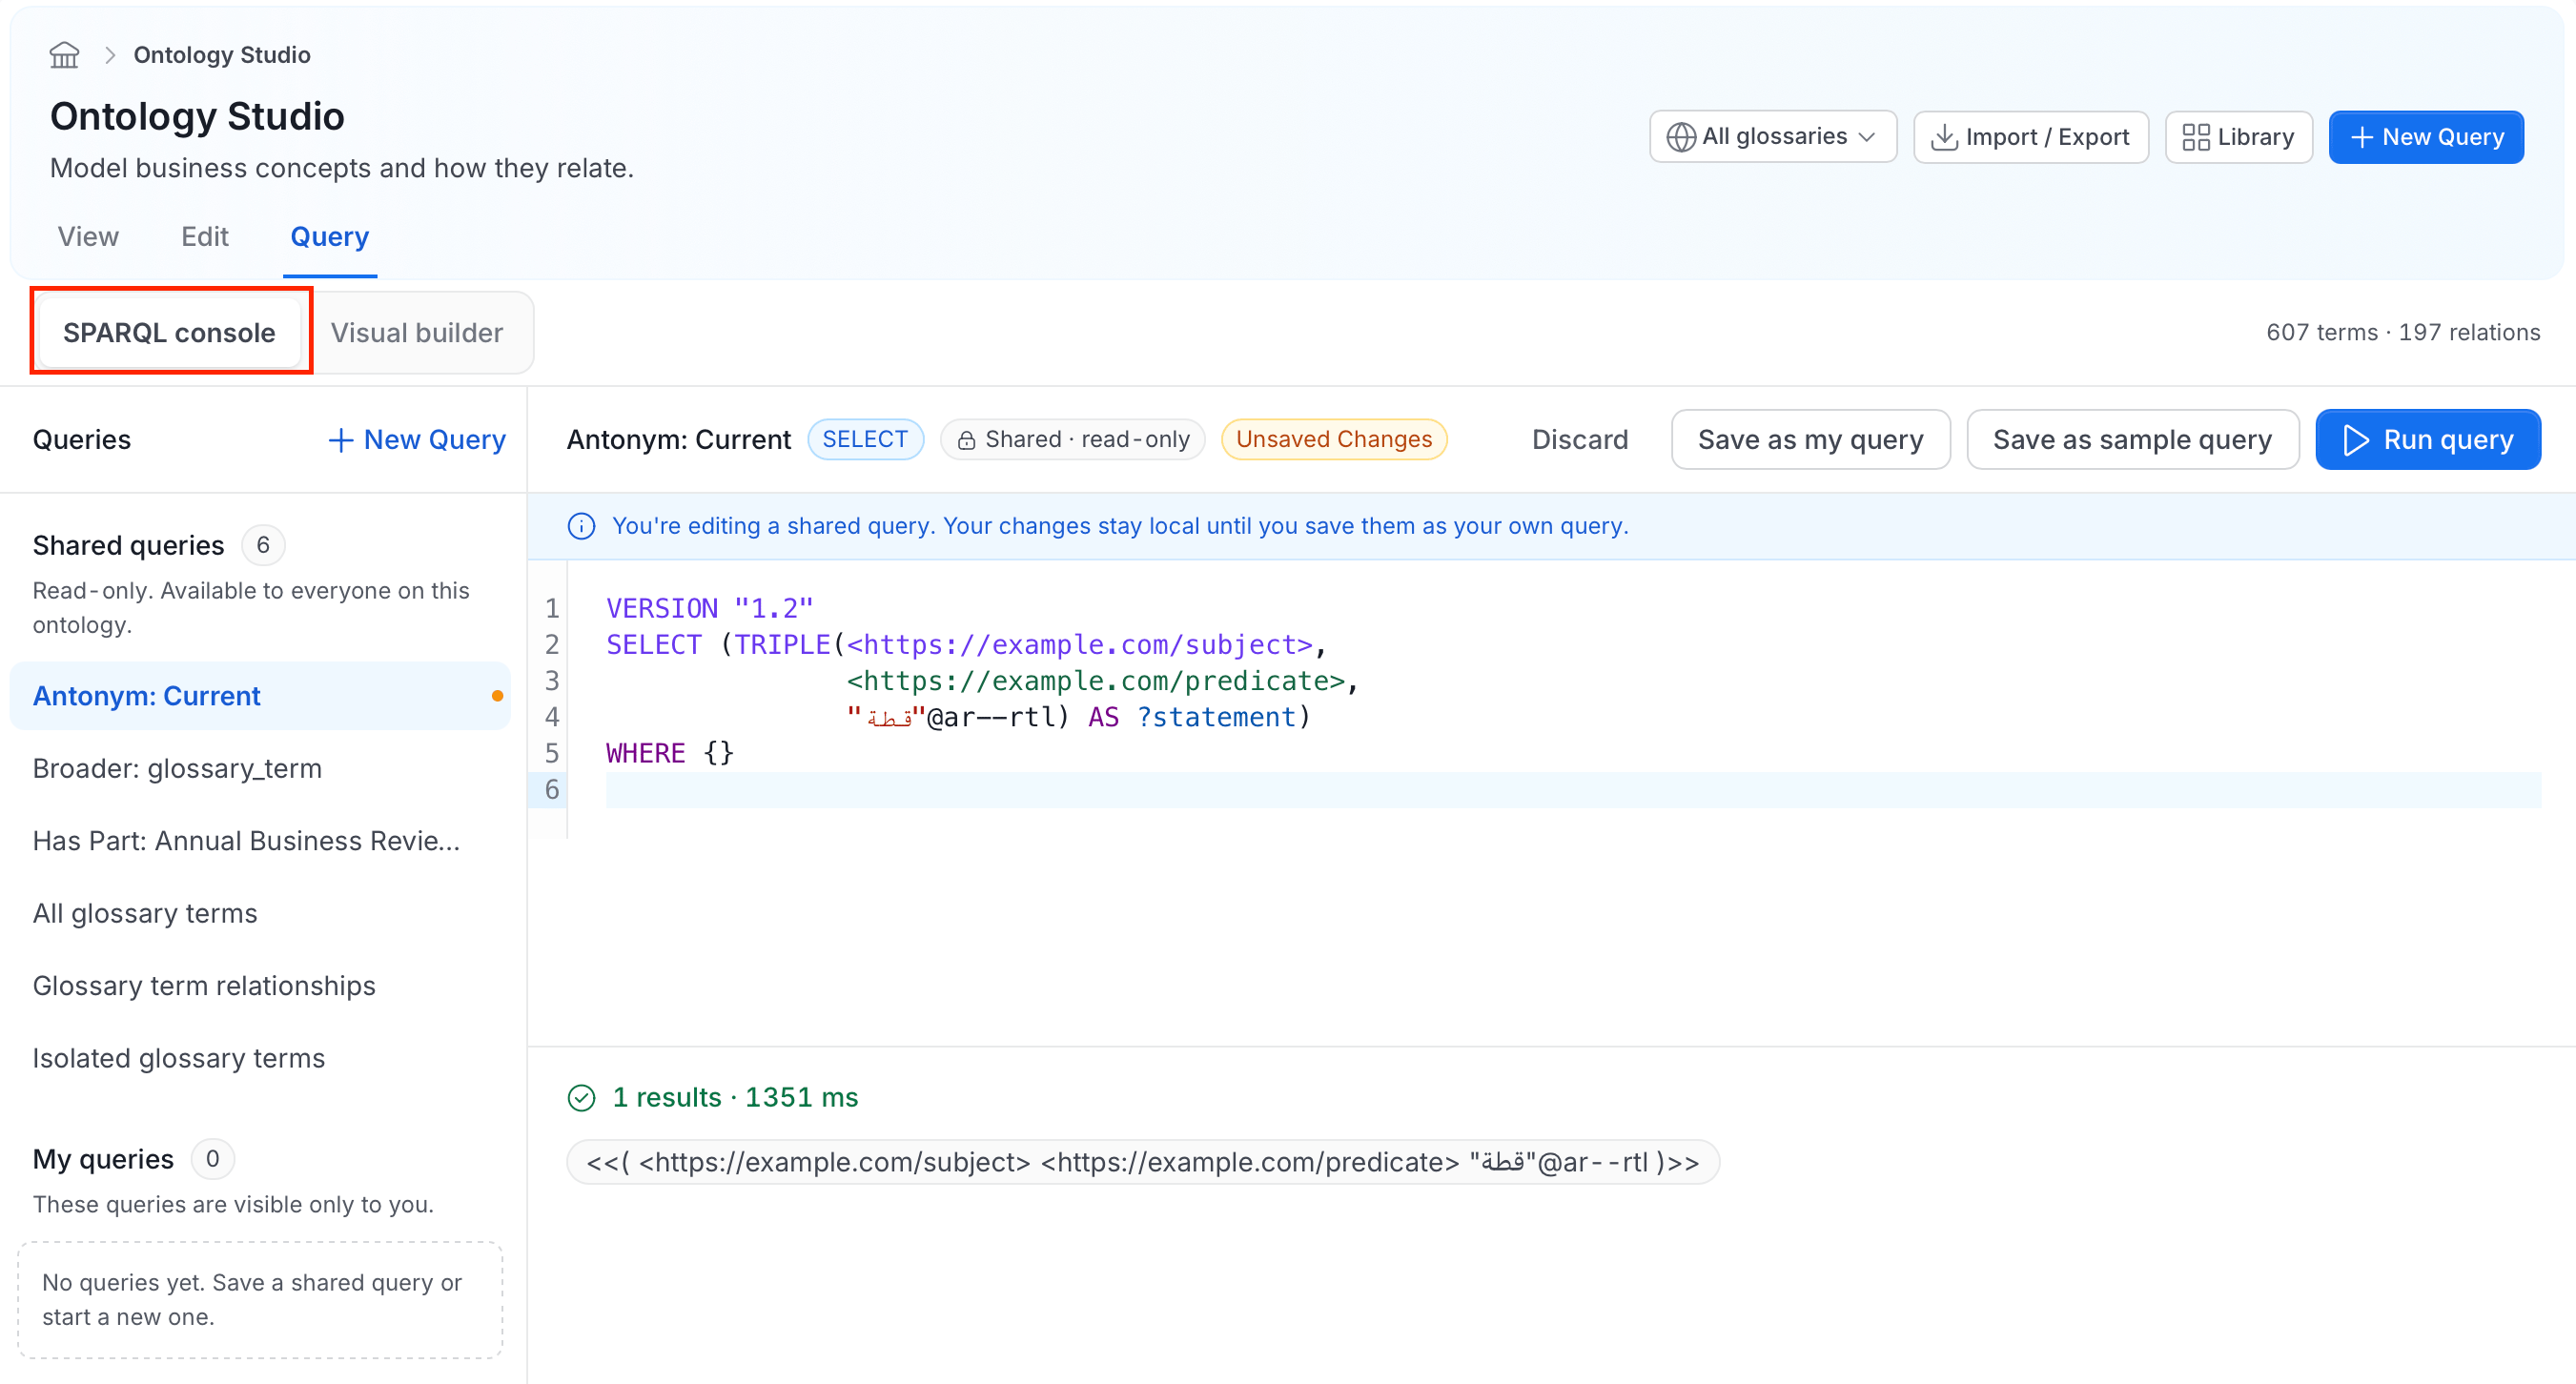
OpenMetadata writes the graph for its own entities as RDF 1.1. RDF 1.2 terms enter through imported ontologies and the queries you write. OpenMetadata carries them through storage, query, and results unchanged.
Serialization Formats
Performance Notes
- Always scope to the named graph. Unscoped patterns scan schema and shapes as well.
LIMITearly. The guard truncates you at 1,000 rows by default anyway; be explicit.- Bind the most selective triple first. Start from a specific IRI or an indexed literal like
om:fullyQualifiedName, not from?s a om:Table. - Property paths are powerful and expensive.
+and*over a large lineage graph can hit the 30-second timeout. If you run one regularly, materialize it as an inference rule instead. - Prefer
FILTER NOT EXISTSoverOPTIONAL+!BOUND. Same result, better plan.
Next
Reasoning & Validation
Materialize the closures you keep re-computing.
Graph Insights
Pre-computed importance, communities, and paths.